You can use Qwen4-Max for free through QwenCloud’s free quota: the qwen4-max model page shows 1M free tokens for the Singapore region, usable through the same OpenAI-compatible API you’d pay for later. You need a QwenCloud account with payment details on file to activate it. Qoder’s 14-day Pro trial, QwenWork’s $0 plan and QwenStudio are softer routes with unpublished model limits.
Qwen4-Max reached general release on November 16, 2026, at $1.50 per million input tokens and $4.50 per million output. This guide covers each free route, where it stops, and when paying gets cheaper. Every route was checked on official pages on November 16, 2026.
If you’re new to the model, start with what Qwen4-Max is, and see how to use Qwen4-Max for the paid routes.
Qwen4-Max free routes at a glance
| Route | What’s free | Card or payment details | Qwen4-Max confirmed on the free tier? |
|---|---|---|---|
| QwenCloud API free quota | 1M tokens, input and output combined | Yes, payment details to activate | Yes, the model page shows it |
| Qoder Pro trial | 300 Credits for 14 days, new users | No for the trial | Listed in Qoder’s model selector docs |
| QwenWork Free plan | 500 sign-up and 200 daily login credits | No | Not published |
| QwenStudio (chat.qwen.ai) | Free account | No | Not published |
| Token Plan | Nothing: paid, from $3 for new users | Yes | Not a free route |
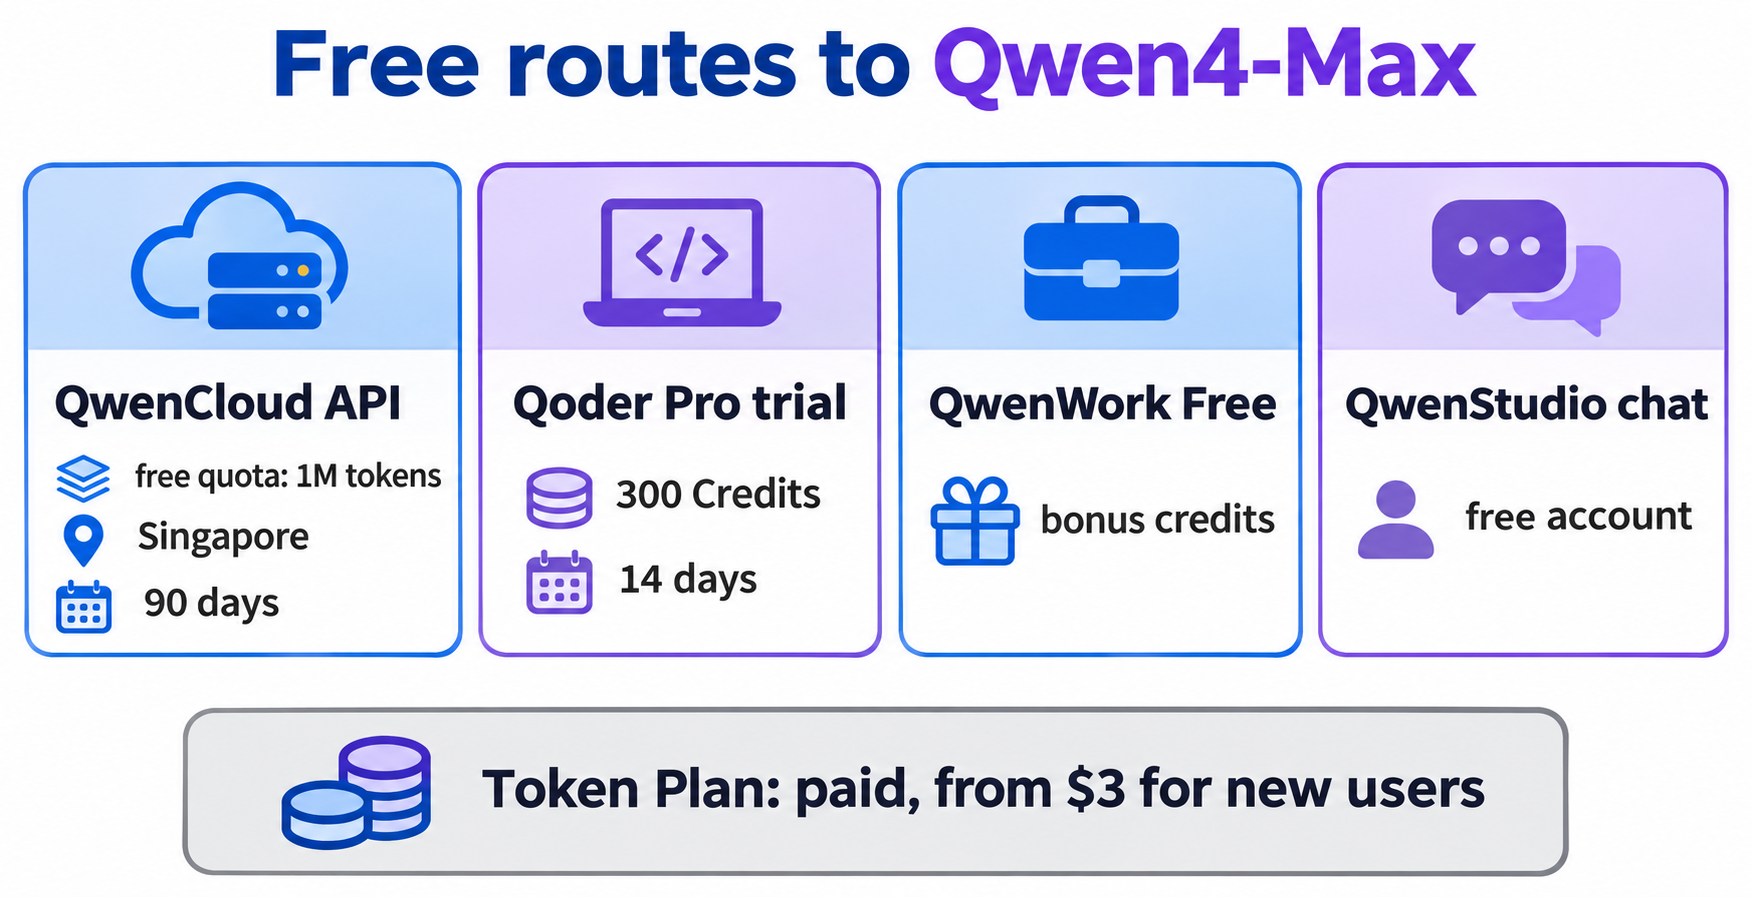
Only the first row is a free Qwen4-Max quota you can count on. The others are free accounts with no published Qwen4-Max allowance.
Route 1: the QwenCloud API free quota
The QwenCloud free quota is a per-model token allowance that new accounts get for API calls. For Qwen4-Max, the model page shows “Free Quota: 1M tokens remaining.” Input and output tokens draw from that one pool, and you call the model with the same key and code you’d use on the paid API.
The free quota rules add the fine print:
- Region: Singapore only. The quota applies to real-time calls made with a Singapore API key against the Singapore endpoint.
- Validity: typically 90 days. For a model released after you sign up, the clock starts at the model’s release date, not your sign-up date.
- Activation: you complete your payment information, and the quota is granted once it’s verified.
- No reset: unused quota expires, and opening a new account doesn’t add more.
- Real-time only: batch jobs don’t draw from the free quota, so they bill at the batch rate from the first request.
How to claim and call it
- Sign up at QwenCloud and add your payment details.
- Open the Free Tier page in the console and turn on Free quota only.
- Create an API key for the Singapore region.
- Call
qwen4-maxon the OpenAI-compatible endpoint.
Step 2 keeps the route at $0. With Free quota only on, calls are blocked once the quota runs out, and nothing is charged. It’s off by default, so a looping script would otherwise roll into paid usage.
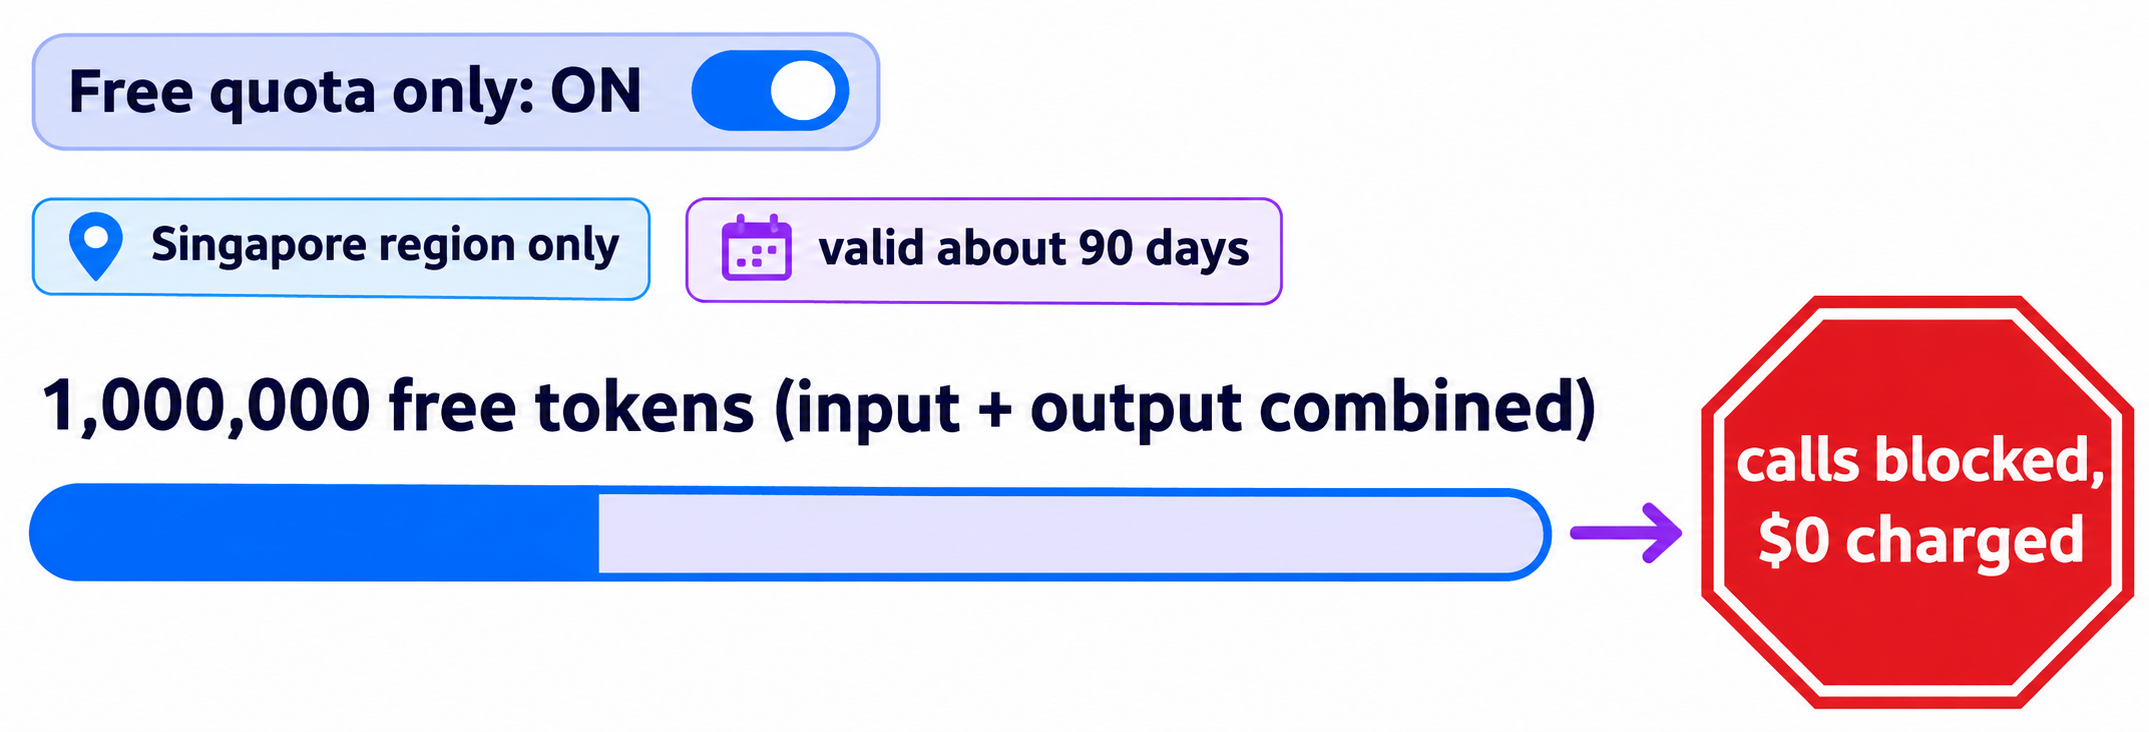
Here’s a minimal call with the OpenAI Python SDK, using the Singapore base URL from the model page:
import os
from openai import OpenAI

client = OpenAI(
    api_key=os.getenv("DASHSCOPE_API_KEY"),
    base_url="https://ap-southeast-1.maas.qwencloudapi.com/compatible-mode/v1",
)

resp = client.chat.completions.create(
    model="qwen4-max",
    messages=[{"role": "user", "content": "Summarize HTTP 429 in two sentences."}],
)
print(resp.choices[0].message.content)
print(resp.usage)  # watch this: every token comes out of the 1M pool
To switch on thinking, add extra_body={"enable_thinking": True}. The answer then streams reasoning_content before the final text. Our Qwen4-Max API guide covers streaming, vision, tools and JSON output in depth.
How far 1M free tokens goes
A million tokens sounds large until you turn on thinking. Here’s the math for three common call shapes:
| Call shape | Tokens per call | Calls from 1M tokens | List-price value |
|---|---|---|---|
| Short chat: 2,000 in, 500 out | 2,500 | about 400 | about $2.10 |
| Same call with 6,000 reasoning tokens | 8,500 | about 117 | about $3.80 |
| Long document: 300,000 in, 2,000 out | 302,000 | 3 | about $1.40 |
Reasoning tokens count as output, so thinking shrinks the free quota fastest. Use it with thinking off for quick prompt tests, and save thinking for the calls where you need to judge reasoning quality.
Route 2: Qoder’s free Pro trial
Qoder is Alibaba’s agentic coding IDE, and the Qwen4-Max launch post names it as a place to use the model. Its Free plan costs $0, and new users who sign in to the desktop client for the first time get a one-time 14-day Pro trial with 300 Credits.
Qoder’s model selector docs list Qwen4-Max-Preview at a 0.5x Credit rate. The same page puts the Auto tier at about 5 Credits for its example task, so 300 trial Credits cover roughly 60 tasks of that size at Qwen4-Max’s rate. Real usage varies with your repo and tool calls, and the rate in the selector is the authoritative number.
The limits:
- The trial needs the latest client and doesn’t run on virtual machines.
- It’s one trial per person; extra trial accounts get suspended.
- Unused trial Credits vanish when the 14 days end.
- After the trial, the Free plan keeps “the basic model” under daily and monthly limits, which doesn’t mean Qwen4-Max.
Pick this route to have Qwen4-Max write code in a real project.
Route 3: QwenWork’s Free plan
QwenWork is Alibaba’s agent workspace for knowledge work: you describe an outcome, and it returns a finished file. The Free plan is $0 and currently includes 500 sign-up bonus credits and 200 daily login bonus credits, both marked limited time.
The launch post lists QwenWork as a Qwen4-Max surface, but the pricing page doesn’t say which models the Free plan can use or how many credits a Qwen4-Max task costs.
Route 4: QwenStudio
QwenStudio at chat.qwen.ai is the zero-setup chat route. Signing up is free, and logged-out visitors see Qwen3.7-Plus as the default model. Alibaba names QwenStudio as a Qwen4-Max surface but hasn’t published a quota for it.
What isn’t free: Token Plan
Token Plan is QwenCloud’s monthly subscription for coding agents such as Claude Code, Qwen Code and Qoder, and it includes Qwen4-Max. It isn’t a free route. The Token Plan pricing page lists Lite at $6 a month for 20,000 Credits, and new customers can get Lite or Essential from $3 during the current event. The final price is set at checkout.
Credits run out with no pay-as-you-go fallback, which makes it a cheap, capped option, not a free one. We break it down in the Qwen4-Max Token Plan guide.
When the paid API is the cheaper answer
The free quota fits evaluation, not production. Paying makes sense once any of these is true:
- You’ve used the 1M tokens. At $1.50 in and $4.50 out per million, 400 more short calls cost about $2.10, which is less than the cheapest Token Plan.
- You need batch. Batch never draws from the free quota.
- You’re outside Singapore’s endpoint. Other regions have their own base URL and key, and the free quota doesn’t apply there.
- You need volume. The paid API keeps the 5,000,000 tokens-per-minute limit shown on the model page.
For full cost math with cache rates and thinking surcharges, read the Qwen4-Max pricing breakdown. For quality per dollar, see the Qwen4-Max benchmarks and the Qwen4-Max vs Qwen3.8 comparison.
Let your coding agent stretch the free quota with Apidog CLI
Free tokens are easy to waste on retries and ad hoc test calls. Have your coding agent save one Qwen4-Max request with assertions in Apidog CLI, then rerun that saved case. Each run uses one short request and returns pass or fail.
Set it up once:
npm install -g apidog-cli@latest
apidog login --with-token <YOUR_TOKEN>
npx -y skills add https://apidog.com   # pick your agent when prompted
Then give your agent one prompt:
In Apidog project <projectId>, create an environment "Qwen free quota" with base URL
https://ap-southeast-1.maas.qwencloudapi.com/compatible-mode/v1 and a secret
variable DASHSCOPE_API_KEY. Add POST /chat/completions with a Bearer auth header,
model qwen4-max and max_tokens 200. Create a test case asserting status 200, a
non-empty choices array and a usage object. Run it once and report total_tokens.
The agent checks each payload schema before it writes, then runs the case:
apidog environment create "Qwen free quota" --project <projectId> --base-url https://ap-southeast-1.maas.qwencloudapi.com/compatible-mode/v1
apidog cli-schema get endpoint-create
apidog endpoint create --project <projectId> --file endpoint.json
apidog cli-schema get test-case-create
apidog cli-schema validate test-case-create --file case.json
apidog test-case create --project <projectId> --file case.json
apidog run --test-case <caseId> --project <projectId> -e <envId> -r cli,json
The max_tokens 200 cap keeps each test run small, and the usage assertion gives your agent a token count to track against the 1M pool. When you move to the paid API, put the same apidog run ... -r junit in CI with the Apidog CLI CI/CD guide, and see Apidog CLI in Claude Code for more agent prompts. Apidog’s Free plan covers up to 4 users.
FAQ
Is Qwen4-Max free?
Partly. QwenCloud’s model page shows a 1M-token free quota for qwen4-max in the Singapore region, activated once you add payment details. Beyond that, the API costs $1.50 per million input tokens and $4.50 per million output tokens.
Do I need a credit card for the Qwen4-Max free quota?
You need to complete your payment information before QwenCloud grants the quota. Turn on Free quota only on the Free Tier page, and calls stop at zero instead of billing you.
How long does the free quota last?
Typically 90 days. For a model released after you sign up, like Qwen4-Max, the period starts at the model’s release date. Unused tokens expire.
Can I download Qwen4-Max and run it locally for free?
No. Alibaba hasn’t released Qwen4-Max weights. The launch post says smaller Qwen4 models are coming to open source, with no names or date. For older open models, see using Qwen3.8 for free.
Is Token Plan free for new users?
No. New customers can get Lite or Essential from $3 during the current event, and Lite normally costs $6 a month. It’s cheap and capped, but paid.
Does the free quota cover the Live Delivery plugin?
The plugin itself is free and open source under Apache-2.0. It runs inside Codex CLI, so your model costs depend on what you configure there. See our Qwen Live Delivery plugin guide for setup.