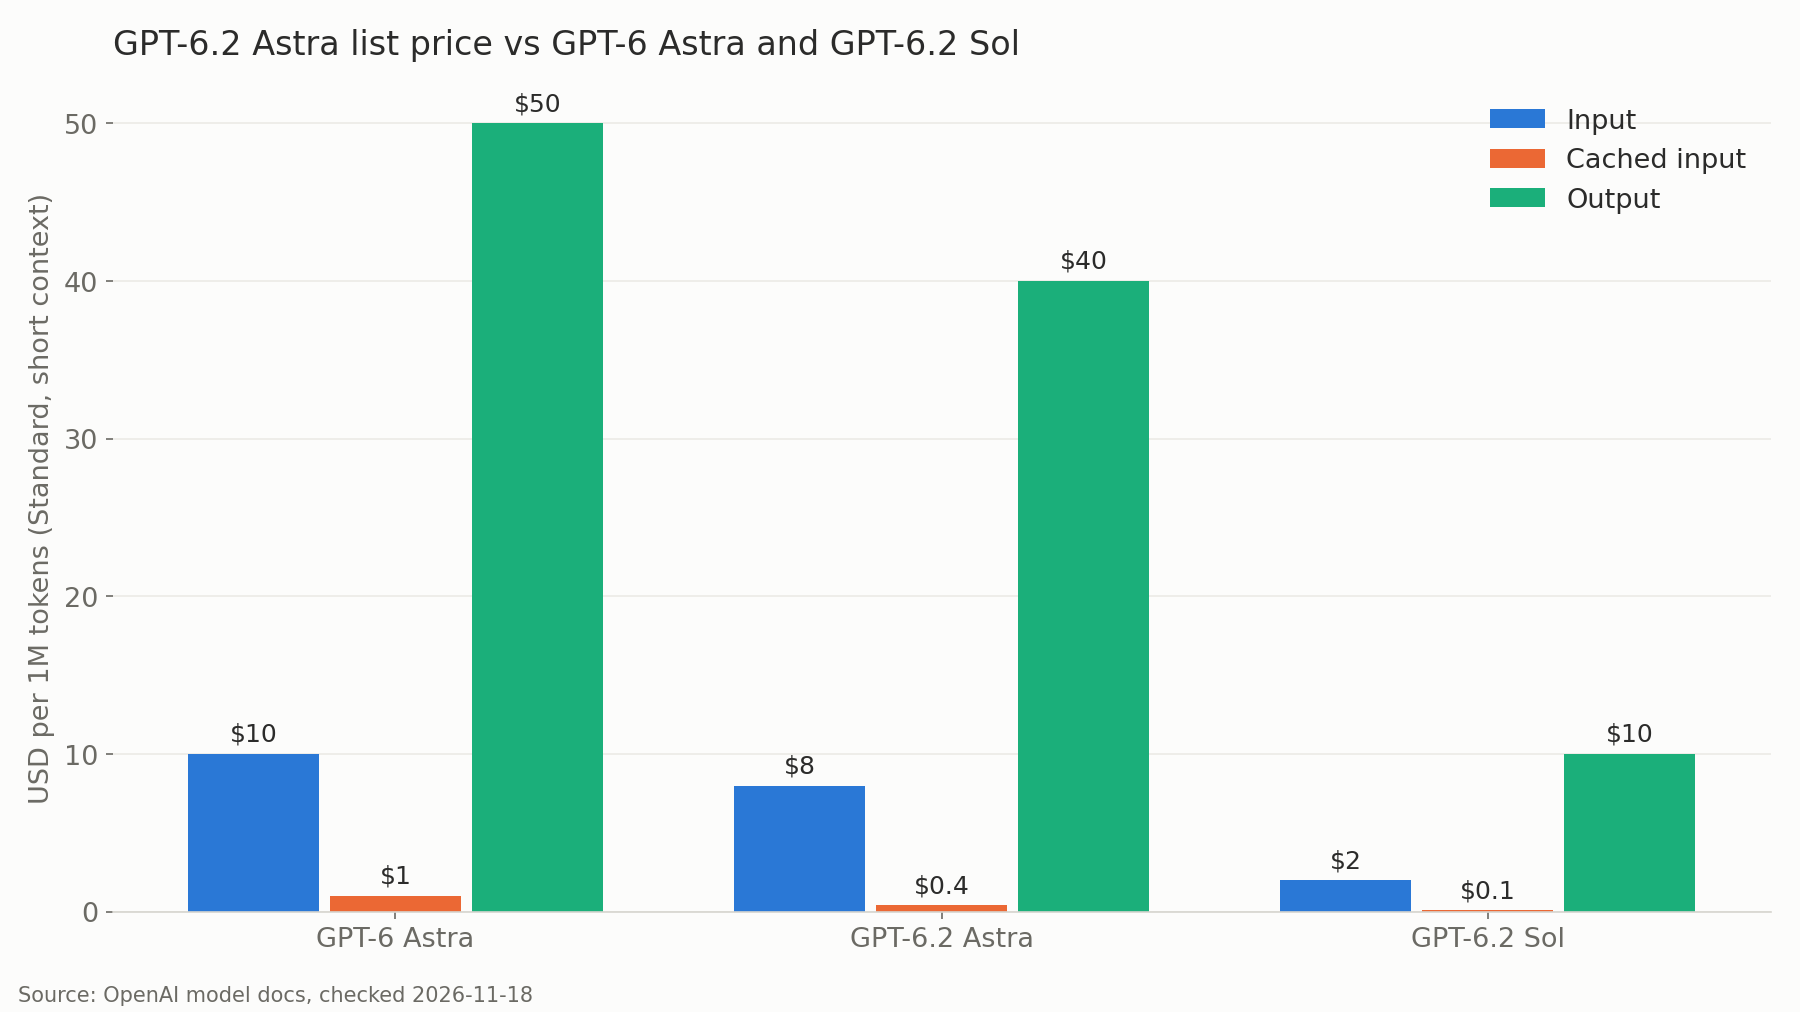
GPT-6.2 Astra pricing is $8 per 1M input tokens and $40 per 1M output tokens on OpenAI’s Standard tier, with cached input at $0.40 per 1M. That’s 20% below GPT-6 Astra ($10/$50), and the cache read rate fell 60%. Its sibling, GPT-6.2 Sol, costs $2 input and $10 output per 1M tokens.
OpenAI shipped both models on November 17, 2026 as gpt-6.2-astra and gpt-6.2-sol.
GPT-6.2 Astra pricing at a glance
GPT-6.2 Astra is OpenAI’s frontier model for long, hard projects: coding, computer use and document work, with a 1,050,000-token context window and up to 128,000 output tokens. On the Standard tier it bills $8 per 1M input tokens, $0.40 per 1M cached input tokens and $40 per 1M output tokens, for prompts up to 272K tokens.
| Rate (per 1M tokens, Standard) | GPT-6.2 Astra | GPT-6.2 Sol | GPT-6 Astra |
|---|---|---|---|
| Input | $8.00 | $2.00 | $10.00 |
| Cached input | $0.40 | $0.10 | $1.00 |
| Cache write (30-minute) | $10.00 | $2.50 | $12.50 |
| Cache write (12-hour) | $20.00 | $5.00 | $25.00 |
| Output | $40.00 | $10.00 | $50.00 |
Reasoning tokens bill as output tokens. That matters on Astra, because the model rejects requests that set reasoning effort to none, so every call carries some reasoning cost on top of the visible answer.
GPT-6.2 Astra API cost per token
One input token costs $0.000008 and one output token costs $0.00004. Output is 5x the price of input, so what the model writes, hidden reasoning included, drives most of your bill.
A typical chat request with 3,000 input tokens and 800 output tokens costs:
- GPT-6.2 Astra: $0.024 input + $0.032 output = $0.056
- GPT-6.2 Sol: $0.006 + $0.008 = $0.014
- GPT-6 Astra: $0.030 + $0.040 = $0.070
Scale that to an app serving 20,000 such requests a day. Over 30 days that’s 600,000 requests: about $33,600 on GPT-6.2 Astra, $8,400 on GPT-6.2 Sol, and $42,000 on GPT-6 Astra. Sol keeps the same $2/$10 list price as GPT-6 Sol and GPT-6.1 Sol, so if you already budget for Sol, nothing moves.
GPT-6.2 Astra cache pricing: the biggest change
The headline cut is 20%, but the cache cut is larger. Cached reads on GPT-6.2 Astra cost $0.40 per 1M, which is 0.05x the input rate. GPT-6 Astra charged $1.00, or 0.1x. The OpenAI prompt caching guide confirms the 0.05x read rate applies to GPT-6.2 Astra, GPT-6.2 Sol, GPT-6.1 Sol and GPT-6.1 Terra.
Three rules shape what you pay:
- Writes replace input, they don’t stack. A token written to cache bills at the write rate instead of the input rate, never both. A 30-minute write costs 1.25x input ($10 on Astra); a 12-hour write costs 2.5x ($20).
- The minimum prefix is 1,024 tokens. Shorter prompts never cache.
- Reads cost the same for both lifetimes. Pick 12-hour writes only for stable system prompts and reference docs reused across long gaps.
At these rates, caching pays off on the first reuse. One 30-minute write plus one read costs 1.30x the uncached price of a prefix, against 2x for sending it twice. Over ten requests it’s 1.70x against 10x.
Simon Willison called the cached price “great news for longer running agentic sessions” in his launch-day write-up. For tactics, see our guide to GPT-6 prompt caching.
What a 50-turn agent session costs
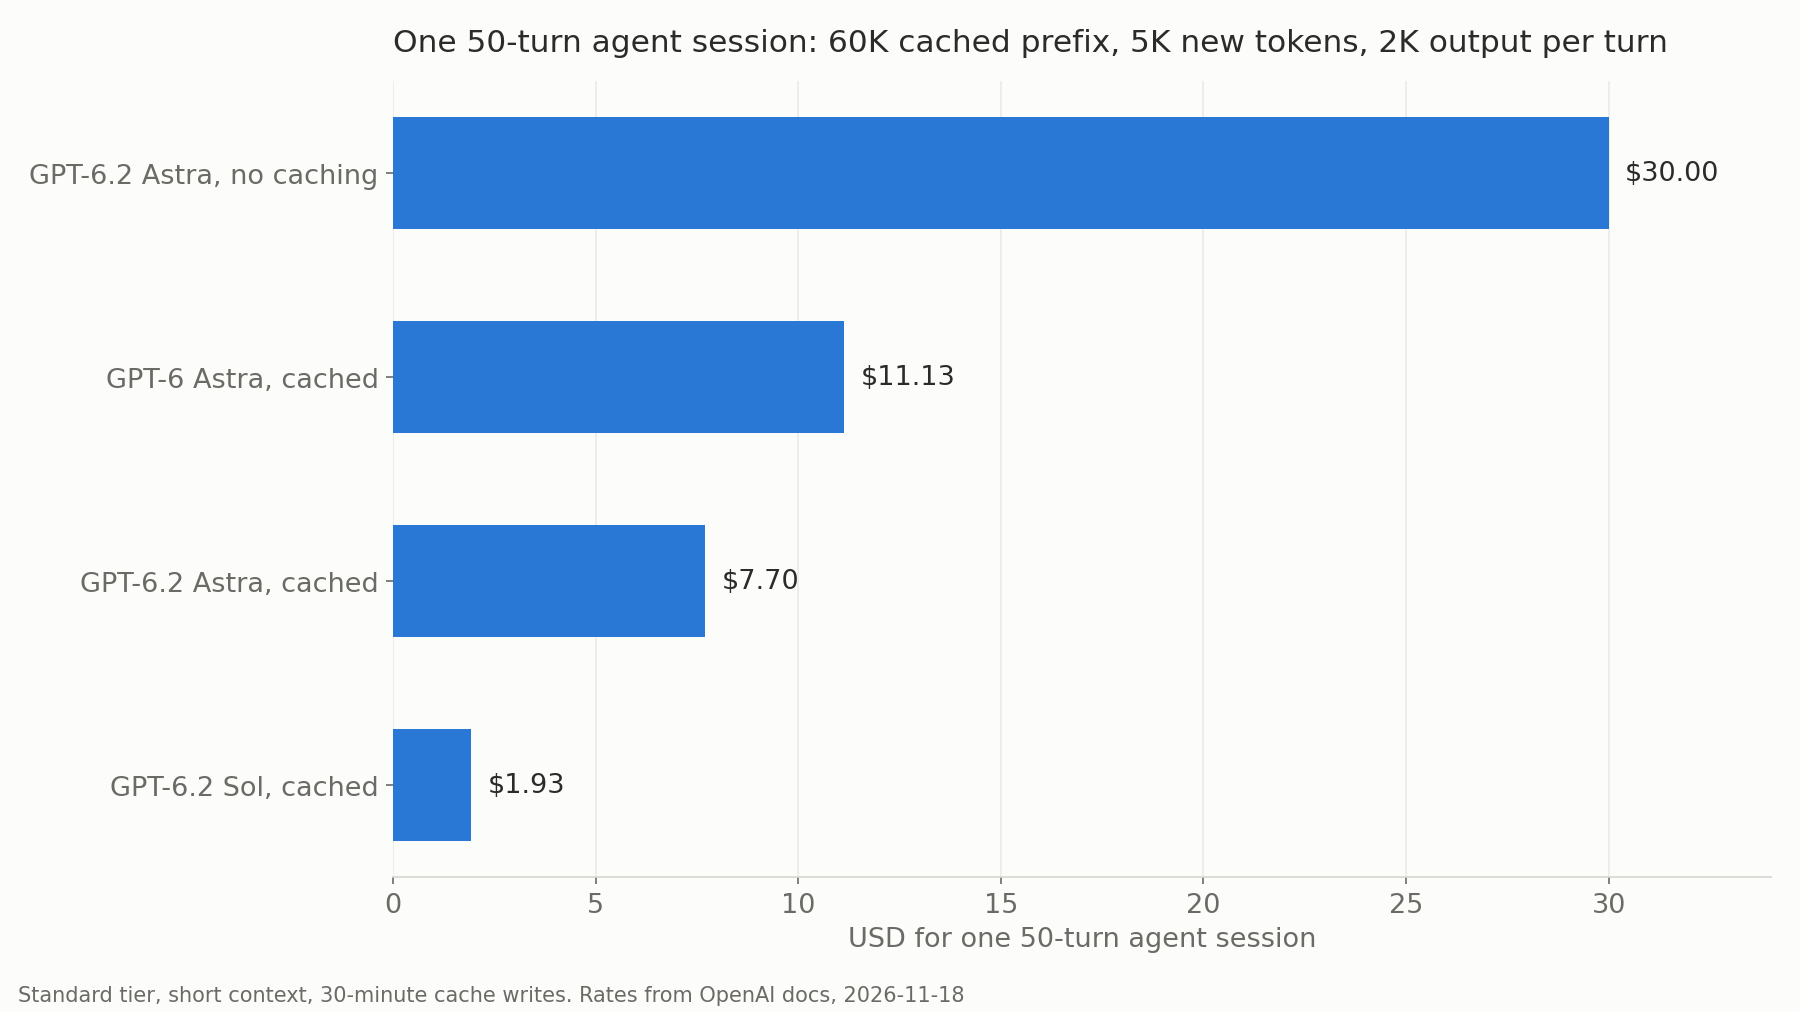
Take a coding agent that runs 50 turns. Each turn re-reads a 60K-token prefix from cache, writes 5K new tokens to a 30-minute cache, and produces 2K output tokens.
| Model and setup | Cost per turn | Cost per session |
|---|---|---|
| GPT-6.2 Astra, no caching | $0.600 | $30.00 |
| GPT-6 Astra, cached | $0.223 | $11.13 |
| GPT-6.2 Astra, cached | $0.154 | $7.70 |
| GPT-6.2 Sol, cached | $0.039 | $1.93 |
Caching cuts the GPT-6.2 Astra session by 74%. Against GPT-6 Astra with the same caching, the new model is 31% cheaper per session, more than the 20% list cut, because the cached prefix is the largest share of input.
Long-context pricing above 272K tokens
GPT-6.2 Astra accepts up to 922,000 input tokens, but the price changes at 272K. Once a request’s input passes 272K tokens, input and cache rates double and output rises to 1.5x, for the whole request, not just the overflow.
| Rate (per 1M tokens) | Up to 272K input | Over 272K input |
|---|---|---|
| Input | $8.00 | $16.00 |
| Cached input | $0.40 | $0.80 |
| Cache write (30-minute) | $10.00 | $20.00 |
| Output | $40.00 | $60.00 |
A single 400K-token codebase review with 4K output costs $6.40 + $0.24 = $6.64. Trim the same review to 250K tokens and it drops to $2.00 + $0.16 = $2.16. If you run the 400K review repeatedly with 380K tokens served from cache and 20K new tokens written, it costs about $0.94 per run.
Retrieval and trimming pay off when a prompt sits just above 272K.
Batch, background windows, Fast and Ultrafast
OpenAI’s pricing page lists GPT-6.2 Astra under four processing tiers, plus discounted background windows. GPT-6.2 does not appear in the Flex table, so the background windows fill that role for work that can wait.
| Tier (short context) | Astra input / output | Sol input / output |
|---|---|---|
| Standard | $8 / $40 | $2 / $10 |
| Batch (50% off) | $4 / $20 | $1 / $5 |
| Background, 8-hour window (40% off) | $4.80 / $24 | $1.20 / $6 |
| Background, 2-hour window (30% off) | $5.60 / $28 | $1.40 / $7 |
| Fast (2x) | $16 / $80 | $4 / $20 |
| Ultrafast, through Feb 28, 2027 (3x) | $24 / $120 | $6 / $30 |
| Ultrafast, from Mar 1, 2027 (6x) | $48 / $240 | $12 / $60 |
The background windows are a public beta on the Responses API. You set background to true and background_options.completion_window to 2h or 8h, and leave streaming off. The background mode guide notes two catches: these requests share the Batch rate limit, and Standard requests can’t reuse cache entries that 2h or 8h requests created.
Here’s a nightly job that summarizes 10,000 documents, each 4K input and 500 output tokens:
| Tier | GPT-6.2 Astra | GPT-6.2 Sol |
|---|---|---|
| Standard | $520 | $130 |
| Background, 2-hour | $364 | $91 |
| Background, 8-hour | $312 | $78 |
| Batch | $260 | $65 |
Ultrafast’s 3x rate is a promotion; on March 1, 2027 it doubles to 6x, so don’t budget on it.
GPT-6.2 Astra vs GPT-6.2 Sol and rival flagships
Astra costs exactly 4x Sol on every line. Sol’s model page lists the same 1,050,000-token context, the same 128,000 output cap, the same tools and the same rate limits. So the choice comes down to quality per task, not features.
| Model (per 1M tokens) | Input | Cached read | Output |
|---|---|---|---|
| GPT-6.2 Astra | $8.00 | $0.40 | $40.00 |
| Claude Fable 5.2 | $8.00 | $0.20 | $40.00 |
| Claude Opus 5.5 | $4.00 | $0.20 | $20.00 |
| GPT-6.2 Sol | $2.00 | $0.10 | $10.00 |
Claude prices come from Anthropic’s pricing page, checked November 18, 2026. GPT-6.2 Astra and Claude Fable 5.2 share the same $8/$40 list price; Fable 5.2’s cache hits cost $0.20 and its write rates follow Anthropic’s 5-minute and 1-hour lifetimes, not OpenAI’s 30-minute and 12-hour ones, so compare realized cost on your own traffic.
Early reviews are mixed on quality. Willison notes that GPT-6.2 Astra “isn’t scoring quite as high as Fable 5.2 on various benchmarks”, so run your own evaluation before you commit. If you’re coming from the earlier generation, our GPT-6 Astra API guide covers the request shape, and the GPT-6 Astra to Sol migration explains when the cheaper model is enough.
Both models share the same Standard rate limits: 5,000 requests and 1M tokens per minute on the Build tier, up to 15,000 requests and 40M tokens per minute on Grow.
Let Codex check your GPT-6.2 Astra costs with Apidog CLI
Price tables only help if your requests actually hit the cache and stay under 272K. Your coding agent can check that on every build with Apidog CLI.
npm install -g apidog-cli@latest
apidog login --with-token <YOUR_TOKEN>
npx -y skills add https://apidog.com   # pick your agent when prompted
Then give your agent one prompt:
Create an Apidog test case in project <id> for POST /v1/responses with model
gpt-6.2-astra. Send the same 2,000-token system prompt twice. Assert both calls
return 200, usage.input_tokens stays under 272000, and the second call reports
usage.input_tokens_details.cached_tokens above 0. Run it against the openai
environment and summarize any failures.
The agent reads the schema, validates its payload, creates the case and runs it:
apidog cli-schema get test-case-create
apidog cli-schema validate test-case-create --file case.json
apidog test-case create --project <id> --file case.json
apidog run --test-case <caseId> --project <id> -e <envId> -r cli,json
If a prompt change breaks caching or pushes a request past 272K, the run fails before the bill arrives. The same apidog run with -r junit drops into CI; our Apidog CLI CI/CD pipeline guide has a copy-paste setup, and Apidog CLI in Codex covers the agent side. Apidog’s Free plan covers up to 4 users.
FAQ
How much does GPT-6.2 Astra cost per 1M tokens? $8 per 1M input tokens, $0.40 per 1M cached input tokens and $40 per 1M output tokens on the Standard tier, for requests up to 272K input tokens.
Is GPT-6.2 Astra cheaper than GPT-6 Astra? Yes. Input and output are 20% lower ($8/$40 vs $10/$50) and cached reads 60% lower ($0.40 vs $1.00). Our cached agent session came out 31% cheaper.
How much does GPT-6.2 Sol cost? $2 per 1M input tokens, $0.10 cached and $10 output, the same list price as GPT-6.1 Sol and GPT-6 Sol. It’s one quarter of Astra’s price on every line.
Does GPT-6.2 Astra charge more for long prompts? Yes. Above 272K input tokens, input and cache rates double and output goes to 1.5x for the entire request: $16 input, $0.80 cached and $60 output per 1M tokens.
Can I get a discount on GPT-6.2 Astra? Batch costs 50% of Standard. Background requests on the Responses API get 30% off with a 2-hour window or 40% off with an 8-hour window (public beta). Caching cuts repeated prefixes to 0.05x the input rate.
Do reasoning tokens count toward the GPT-6.2 Astra bill? Yes. Reasoning tokens bill at the output rate of $40 per 1M, and the model rejects reasoning effort none, so budget for reasoning on every call.