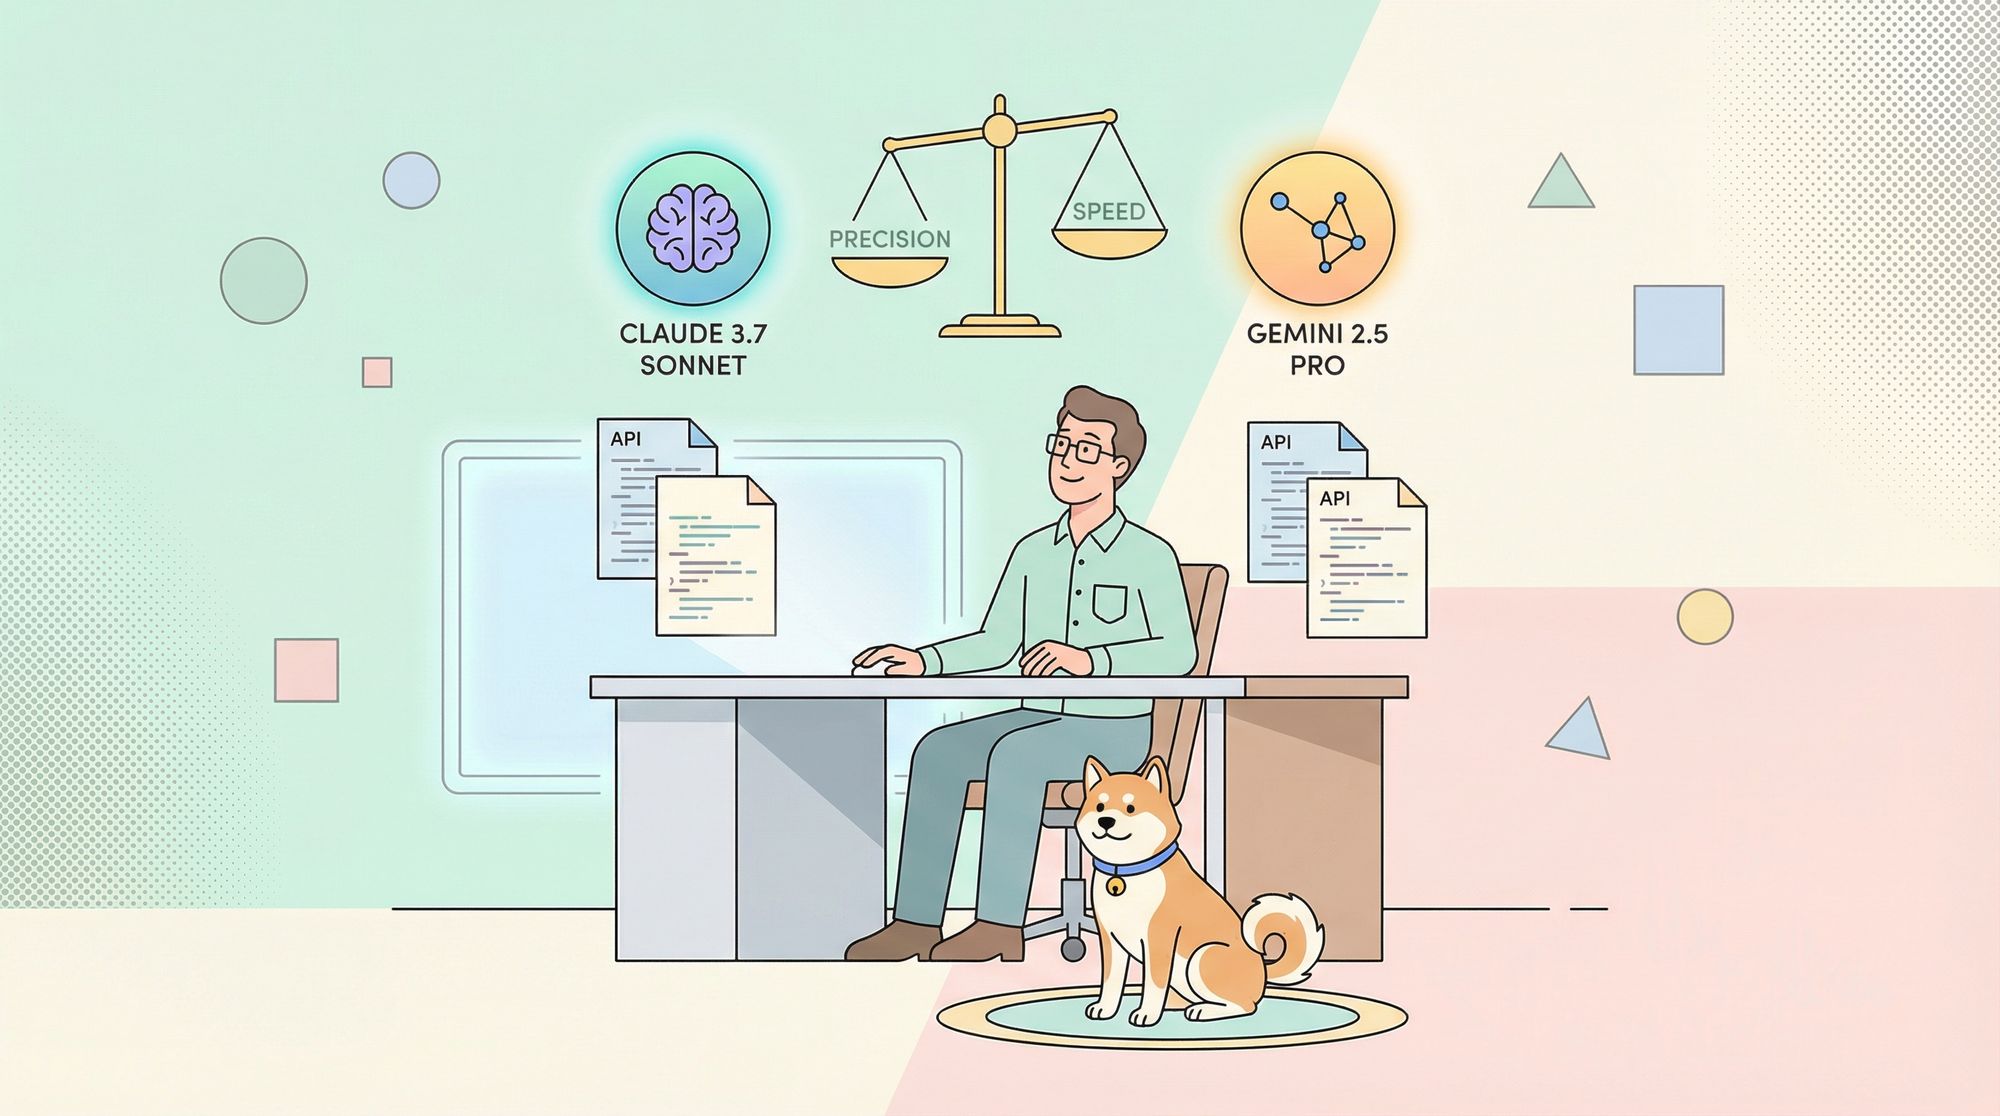
Artificial intelligence is rapidly transforming the way developers build, test, and document code. Two of the most advanced large language models (LLMs) for code-related tasks are Claude 3.7 Sonnet by Anthropic and Gemini 2.5 Pro by Google. But which model is better for software engineering, debugging, and API development?
In this technical comparison, we’ll break down the coding strengths, weaknesses, and use cases for both Claude 3.7 Sonnet and Gemini 2.5 Pro—so you can choose the best AI assistant for your workflow as a developer or API engineer.
Whether you work on backend APIs, complex codebases, or technical documentation, pairing the right AI model with robust API tools can dramatically improve productivity. That’s why Apidog is trusted by developers to streamline API design, testing, and docs—no matter which AI you choose.
Meet the AI Contenders: Claude 3.7 Sonnet and Gemini 2.5 Pro
Claude 3.7 Sonnet: Advanced Reasoning for Developers
Anthropic’s Claude 3.7 Sonnet is engineered for precision and transparent reasoning. Its hybrid system features a unique "extended thinking" mode, making its step-by-step logic visible—ideal for tackling intricate debugging or refactoring challenges. Claude 3.7 Sonnet stands out in software engineering and front-end web projects, earning top scores on developer benchmarks like SWE-bench Verified and TAU-bench.
You can access Claude 3.7 Sonnet through Claude.ai, the Anthropic API, Amazon Bedrock, and Google Cloud Vertex AI.

Gemini 2.5 Pro: Google’s Multimodal Powerhouse
Google’s Gemini 2.5 Pro is designed for versatility and scale. It leverages advanced reasoning to solve coding problems efficiently and supports multimodal input—processing code, text, images, audio, and video. Its standout feature is a massive context window (up to 2 million tokens), making it a strong choice for large codebases or data-heavy projects.
Gemini 2.5 Pro is available on Google AI Studio and Google Cloud services.

Coding Performance: Direct Comparison for Developers
Let’s dive into how each model performs on real-world coding tasks relevant to API and backend engineers.
Code Generation: Fast Delivery vs. Clean Output
-
Gemini 2.5 Pro:
- Delivers code solutions rapidly, great for prototyping or building out features in frameworks like Next.js.
- Excels at large-scale or agent-based workflows.
- Occasionally produces code with minor bugs or formatting issues, requiring a manual review.
-
Claude 3.7 Sonnet:
- Focuses on clarity and correctness over speed.
- Extended thinking mode breaks down complex logic—ideal for maintainable, well-documented code.
- For example, when building a 3D visualization in JavaScript, Claude’s code was easier to read and maintain.
Summary:
- Choose Gemini for rapid iteration and large projects, but double-check the output.
- Use Claude for correctness, maintainability, and teaching scenarios.
Debugging and Refactoring: Analyzing and Improving Codebases
-
Gemini 2.5 Pro:
- Handles massive codebases thanks to its large context window.
- Multimodal input means you can upload error screenshots for faster troubleshooting.
- Best for quickly scanning large projects for bugs.
-
Claude 3.7 Sonnet:
- Excels at refactoring and explaining changes.
- Offers detailed, step-by-step reasoning on code improvements.
- Acts like a pair-programming partner for logic-heavy or legacy refactoring tasks.
Technical Documentation: Simplicity vs. Multimedia
-
Claude 3.7 Sonnet:
- Produces clear, easy-to-understand documentation.
- Breaks down complex code for better team onboarding and handoffs.
-
Gemini 2.5 Pro:
- Generates rich docs with diagrams and visual aids.
- Useful for sharing multimedia explanations, e.g., ML model sketches or data charts.
Benchmark Results: Coding Performance by the Numbers
How do these models compare on industry-standard coding benchmarks?

-
SWE-bench Verified (Software Engineering):
- Claude 3.7 Sonnet: 70.3% (extended mode)
- Gemini 2.5 Pro: 63.8%
- Claude outperforms on complex engineering tasks.
-
GPQA Diamond (Logical Reasoning):
- Claude 3.7 Sonnet: 84.8%
- Gemini 2.5 Pro: 84.0%
- Both models excel, with Claude slightly ahead.
-
AIME (Mathematical Reasoning):
- Claude 3.7 Sonnet: 80.0%
- Gemini 2.5 Pro: 92.0%
- Gemini leads for math-heavy coding or data analysis.
-
WeirdML (Creative ML Tasks):
- Gemini 2.5 Pro is top performer for unusual or creative PyTorch code challenges.
Developer Feedback: Real-World Use Cases
Benchmarks are useful, but developer experiences reveal the practical strengths and weaknesses of each model.
Gemini 2.5 Pro: Speed and UI Fidelity
A developer on X tackled a ChatGPT UI clone:

- Gemini 2.5 Pro: Matched the UI almost exactly, with only a minor icon discrepancy.
“Gemini 2.5 Pro is the new UI king.” - Claude 3.7 Sonnet: Missed some design details and omitted the input box.
Result: Gemini is superior for fast, accurate UI prototyping.
Claude 3.7 Sonnet: Reliable Solutions and Explanations
Solving the classic “median of two sorted arrays” coding problem:
- Gemini 2.5 Pro: Produced a fast, optimal solution but missed an edge case, requiring manual debugging.
- Claude 3.7 Sonnet: Provided a correct, fully explained solution with detailed inline comments.

Result: Claude is more reliable for algorithmic and educational use cases.
Refactoring Legacy Code: Guidance vs. Outlines
- Gemini 2.5 Pro: Supplied a high-level plan but lacked concrete code.
- Claude 3.7 Sonnet: Offered hands-on, step-by-step refactoring guidance and sample code.
Result: Claude is ideal for developers seeking mentoring or thorough code improvement.
Pricing and Accessibility for API Teams
- Claude 3.7 Sonnet:
- Access via Claude.ai or API.
- $3 per million input tokens, $15 per million output tokens.
- Integrated with Anthropic, Amazon Bedrock, and Google Cloud.

- Gemini 2.5 Pro:
- Free tier (generous for small projects).
- Reportedly 36x cheaper than Claude for input/output.
- Access via Google AI Studio and Google Cloud.

Takeaway:
Gemini 2.5 Pro offers a significant cost advantage for high-volume or budget-conscious developers.
Streamlining API Testing with Apidog
While AI models like Claude 3.7 Sonnet and Gemini 2.5 Pro can generate and explain code, robust API testing is still critical for shipping reliable software. Apidog is designed to help API-focused teams:
- Design APIs visually with an intuitive interface.
- Test endpoints and flows—from simple GET requests to complex authentication scenarios.
- Document APIs with clear, shareable docs for internal and external teams.

How to Test APIs with Apidog: Developer Workflow
-
Create a New Project
Organize your API testing in a dedicated workspace.0 -
Define API Endpoints
Specify HTTP methods, parameters, headers, and responses.1 -
Set Up Test Cases
Configure request bodies, authentication, and even custom scripts for advanced testing.2 -
Execute and Analyze
Run your test cases, review results, and debug using detailed logs and status codes. -
Generate and Share Documentation
Automatically generate user-friendly API docs for your team or external developers.3
Tip: Pairing your chosen AI model with Apidog’s end-to-end API workflow ensures your code is not just generated, but fully tested and documented for production.
To extend this comparison beyond two models,GPT-4.5 measured against Claude 3.7 and DeepSeek R1offers a broader view of where each frontier model actually lands on developer tasks.
Conclusion: Which AI Model Should Developers Choose?
- Choose Claude 3.7 Sonnet if you value precision, step-by-step reasoning, and detailed explanations—especially for complex problem-solving or mentoring.
- Choose Gemini 2.5 Pro for speed, handling large-scale projects, or when you need multimodal capabilities and cost-efficiency.
- For any coding workflow: Use Apidog to ensure your APIs are well-designed, fully tested, and clearly documented—no matter which AI assistant you rely on.
Ready to boost your API development and testing? Download Apidog for free and see how it fits into your coding toolkit.