Muse Wonder is Meta’s first frontier-class AI model, released on October 12, 2026 by Meta Superintelligence Labs. It comes in two sizes. Muse Wonder is available today through the Meta Model API as muse-wonder-1.0 at $4 per million input tokens and $20 per million output, and inside Muse Code, Meta’s terminal coding agent. Muse Wonder Full, the larger sibling, is only available to Muse Code subscribers on the two top plans and has no API and no per-token price. Both take text, images, video and audio, return text, and carry a 1M-token context window.
Meta built the pair for agents: software that reads your email, runs your code, fills in forms, and keeps going when something breaks. That framing shapes everything about the release, from the two headline features to the benchmarks Meta chose to publish. This guide covers what the models are, what they score on Meta’s tests and on independent ones, how to get access, what it costs, and where the catches are. If you want to call it today, the Muse Wonder API guide walks through the first request in Apidog.
The two models at a glance
| Muse Wonder | Muse Wonder Full | |
|---|---|---|
| Model ID | muse-wonder-1.0 |
muse-wonder-full-1.0 (catalog only) |
| Where you get it | Meta Model API, Muse Code (all plans) | Muse Code Power ($50/mo) and Maximum ($200/mo) |
| API price | $4 in / $20 out / $0.20 cached per 1M tokens | None published |
| Context window | 1M tokens | 1M tokens |
| Inputs | Text, image, video, audio | Same |
| Output | Text | Text |
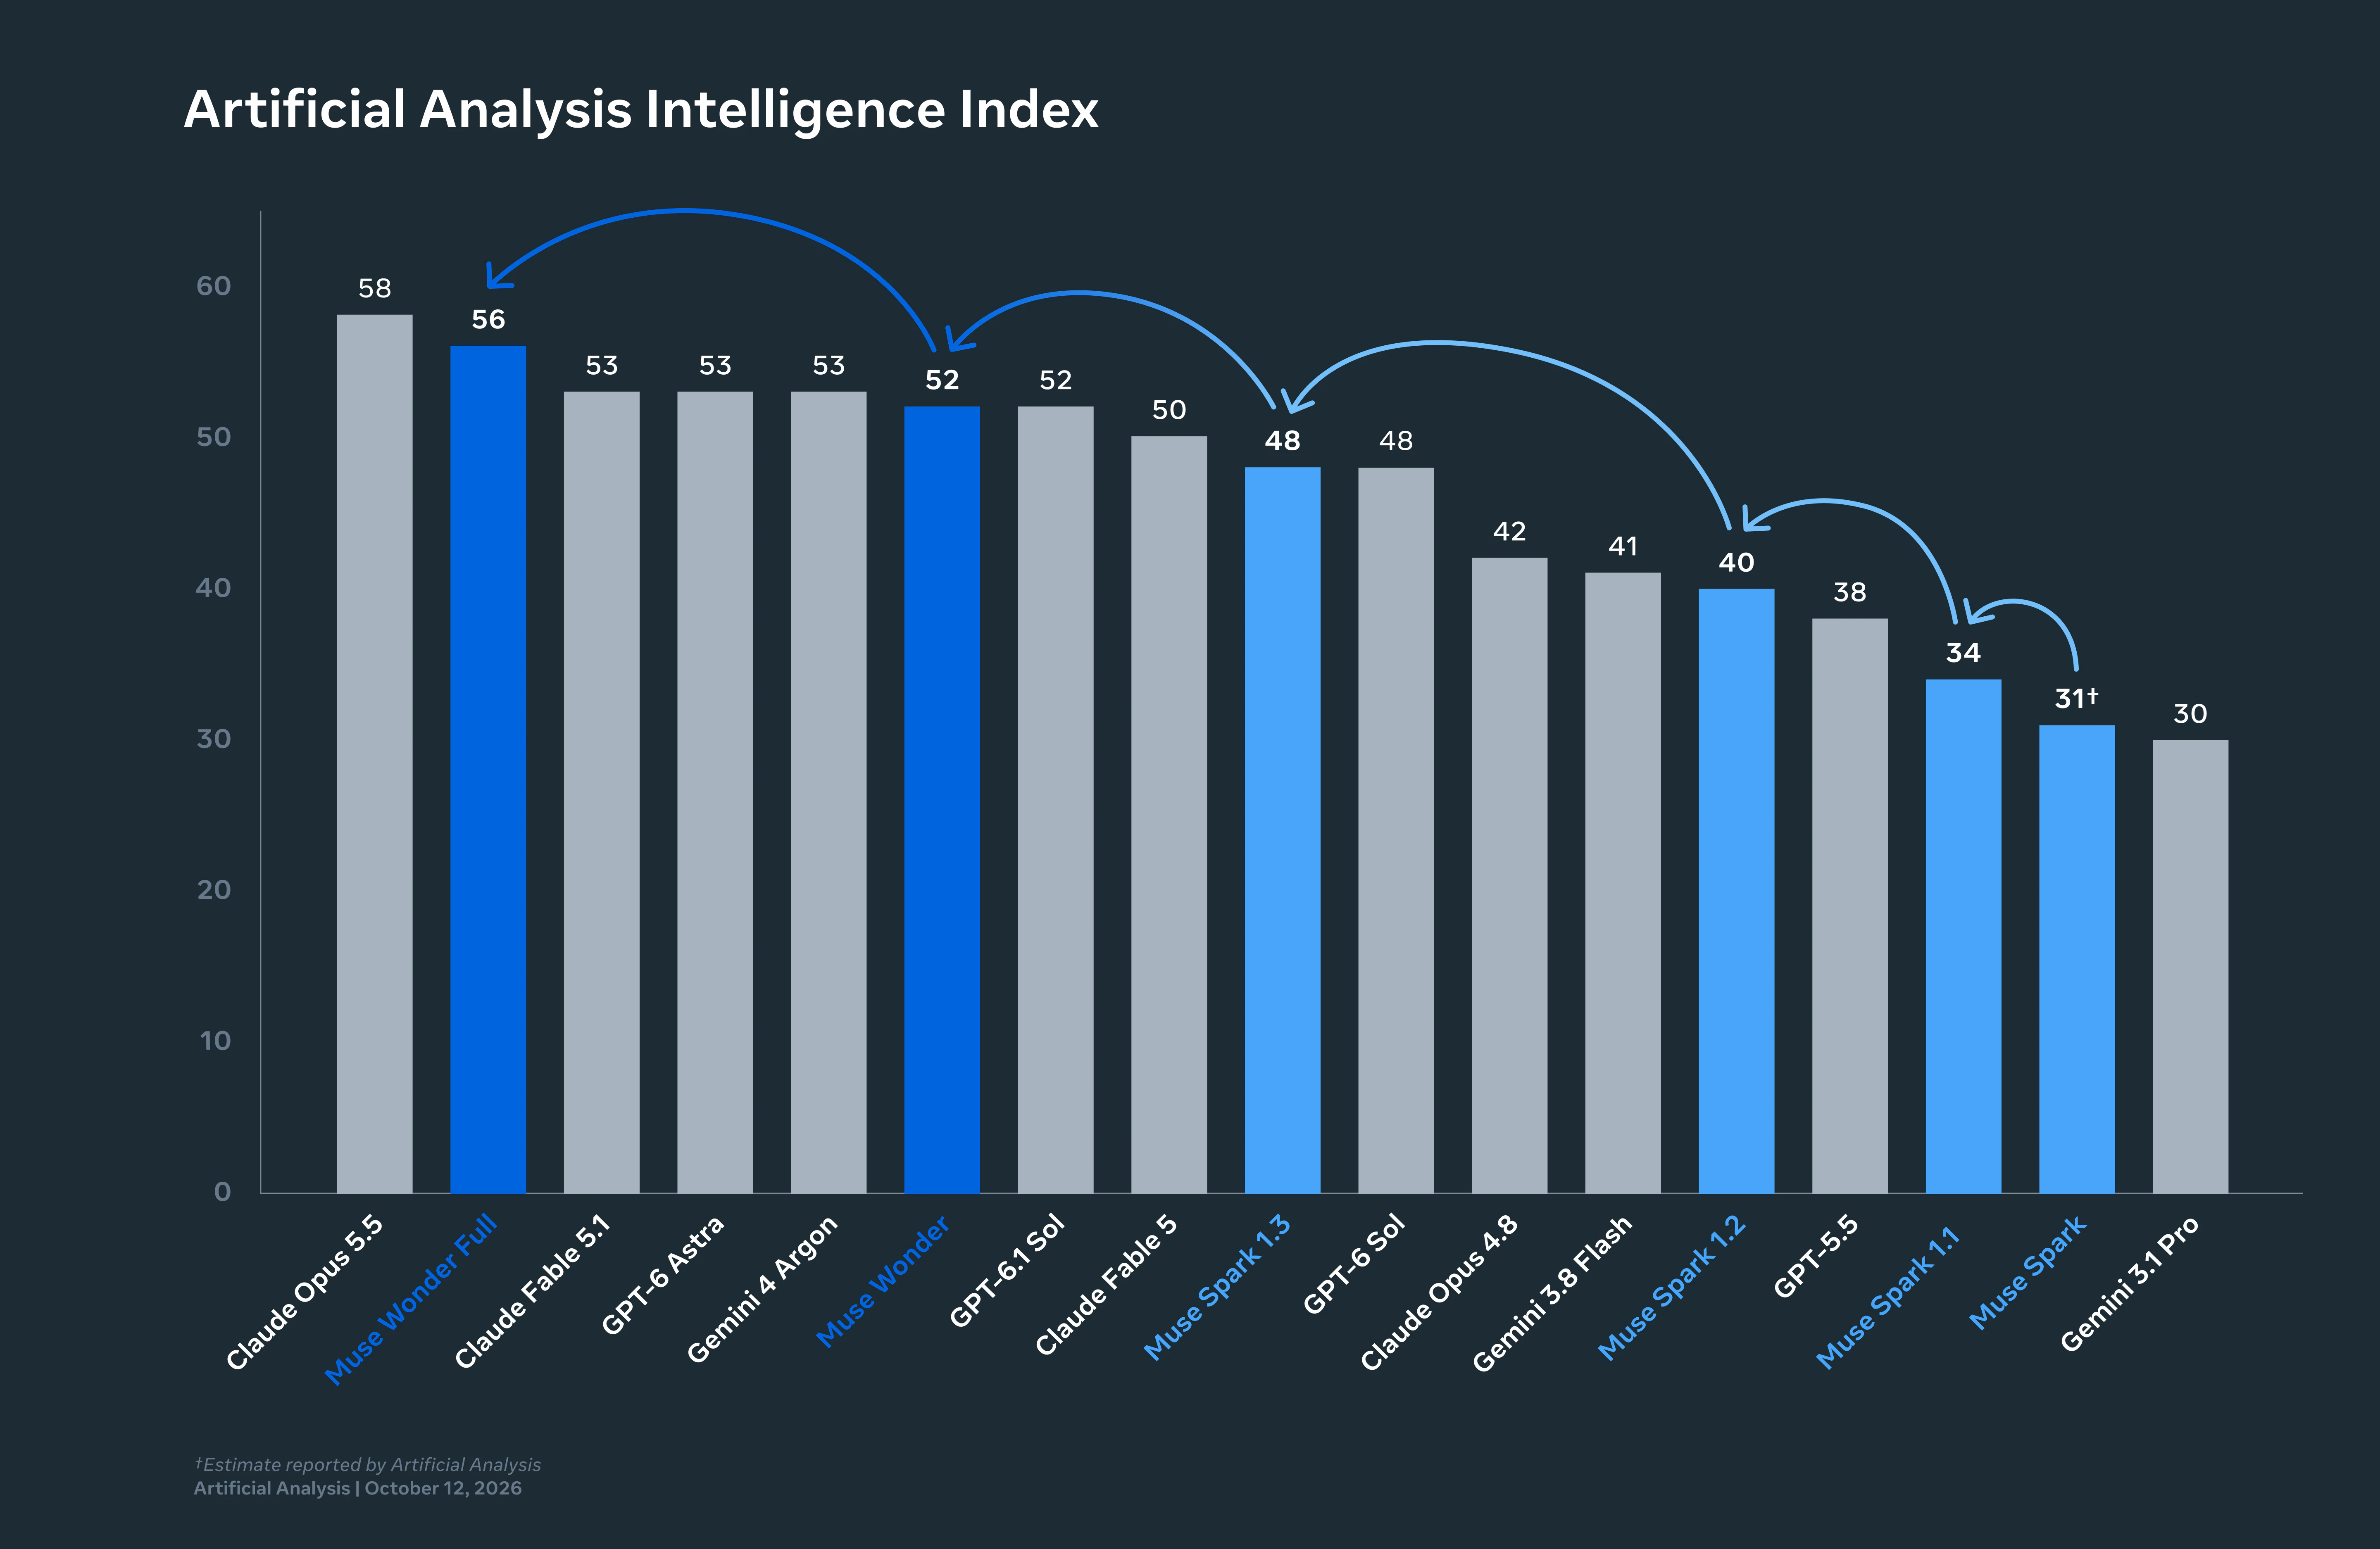
| Artificial Analysis Intelligence Index | 52 | 56 |
| Weights | Closed | Closed |
Both models came out about six weeks after Muse Spark 1.3, which scored 48 on the same index and costs $1.25 / $4.25. Mark Zuckerberg described Wonder on X as “a much larger and more advanced class of models” than Spark. Meta’s research post says the models were trained at its gigawatt-scale Prometheus data center in Ohio, which came online this year.
What’s new: Active Memory and Active Focus
Meta names two capabilities that it says distinguish the Wonder series from earlier models.
Active Memory carries context about a person across conversations and pulls the relevant parts into the current task. In Meta’s framing this is a model behavior, not a separate memory API: there is no endpoint to write memories into. Meta’s internal MemoryBench, which hides facts in 64K to 100K-token conversations and changes some of them halfway through, scores Muse Wonder at 85.6 against 81.5 for Claude Opus 5.5 and 81.4 for GPT-6 Astra.
Active Focus is Meta’s term for persistence on a hard goal: trying alternative approaches, working through blockers, adapting to new information, and, in Meta’s words, asking for clarification when needed and checking in before important actions. On the internal FocusBench, Wonder Full leads at 54.2% with GPT-6 Astra at 47.7%, Opus 5.5 at 45.8%, and the smaller Wonder at 44.9%.
Both benchmarks are Meta’s own and cannot be rerun outside Meta. Treat them as a statement of intent about what the models were trained for, and look to the independent numbers below for how that intent landed.
Beyond those two, Meta lists domain expertise in law, finance and health, frontier coding across large repositories, computer use (operating browsers, desktops and mobile apps), sub-agent delegation, parallel tool calls, and error recovery.
What the benchmarks say
Meta’s model card compares the two models with GPT-6 Astra and Claude Opus 5.5 at maximum reasoning effort. The selection favors agentic and professional work:
| Benchmark | Wonder Full | Wonder | GPT-6 Astra | Claude Opus 5.5 |
|---|---|---|---|---|
| Harvey LAB-AA (legal) | 13.1 | 10.0 | 8.6 | 4.2 |
| SWE-Marathon (long coding runs) | 57.5 | 53.1 | 42.5 | 46.3 |
| DeepSWE 1.1 | 79.0 | 78.8 | 74.1 | 74.2 |
| JobBench | 75.3 | 70.5 | 66.1 | 75.4 |
| Terminal-Bench 4.0-AA | 57.1 | 52.0 | 59.1 | 59.6 |
| HealthBench Pro | 62.3 | 60.5 | 65.3 | 65.6 |
The pattern is consistent: Wonder leads on long-running agent work and legal tasks, and trails Opus 5.5 and Astra on terminal work and health. Meta’s own card notes that competitor runs were best-effort and that some coding comparisons used different tools.
The independent read comes from Artificial Analysis. On its Intelligence Index v4.3, Wonder Full scores 56, tied with Claude Sonnet 5.5, below Opus 5.5 at 58 and above GPT-6 Astra, Gemini 4 Argon and Claude Fable 5.1 at 53 each. Wonder scores 52. Full’s biggest gain over Spark 1.3 was Terminal-Bench 4.0, from 33% to 57%. Its hallucination rate fell from 33% to 23%, the second-lowest among frontier models. Knowledge recall remains the weak spot: 30 on AA-Omniscience against 46 for Opus 5.5. The benchmarks post goes through every row, including the one where Meta’s table and Artificial Analysis disagree.
How to get access
Meta Model API. Create a key at dev.meta.ai, point any OpenAI SDK at https://api.meta.ai/v1, and set the model to muse-wonder-1.0. The API also serves Chat Completions and an Anthropic-compatible Messages endpoint, so Claude Code and Codex can run on it with a few environment variables. Rate limits are 3,000 requests and 4 million tokens per minute, shared across a team rather than per key.
Muse Code. Meta’s terminal agent installs with one curl command and includes Muse Wonder on every subscription from the $5 Everyday plan up. The Power ($50) and Maximum ($200) plans unlock Muse Wonder Full. Subscriptions default to Contributor mode, which lets Meta train on your prompts, code and outputs in exchange for more usage; you can turn it off.
Muse app. The consumer agent app is free, but Muse Wonder is rolling out to its $20 and $100 subscribers first. There is no free route to the model today; the free-access post lists what exists and what it costs.
Third parties. Vercel AI Gateway and Cloudflare Workers AI both serve meta/muse-wonder-1.0 at the same token prices.
What it costs in practice
At $4 / $20, Muse Wonder’s list price matches Claude Opus 5.5 and undercuts GPT-6 Astra and Claude Fable 5.1 ($10 / $50) by 60%. Cached input at $0.20 is a 95% discount. There is no long-context premium: a 900K-token prompt costs the same per token as a 9K one.
List price is not task price. Artificial Analysis measured about $4.52 per Intelligence Index task for Wonder, against $5.98 for Opus 5.5 and $3.26 for GPT-6 Astra. The reason is tokens: Wonder consumed 7.69 million input tokens across the index, two to seven times more than the OpenAI and Google models, and most of its cost was cache writes and reads rather than fresh input. Verbose agents on a cheap-looking rate can still be expensive. The pricing post works through examples, and Apidog will show you usage.input_tokens_details.cached_tokens on every response so you can see where the money goes.
The catches
- The best model is not on the API. Everything Meta’s launch headlines claim about frontier performance rests on Wonder Full, which you can only use through a Muse Code subscription. The API model is four index points lower.
- Internal benchmarks. MemoryBench, FocusBench and the Personal Superintelligence Index are Meta-only tests. Meta’s table also lists Full at 59.0 on an Artificial Analysis row where Artificial Analysis itself publishes 56.
- Data modes matter. API traffic in Standard mode is not used for training. Muse Code subscriptions default to Contributor mode, which is. Zero data retention is available to approved organizations but disables server-side conversation state, background requests, file uploads and built-in web search.
- Launch-week bugs. Wonder and Wonder Full drained Muse Code quotas abnormally fast on day one; Meta reset quotas and Alexandr Wang said there were “still issues we’re trying to iron out.”
- Safety report pending. Meta says it could not rule out the high-risk threshold for chemical and biological misuse without safeguards, assessed residual risk as moderate or lower with them, and promises a full report soon.
- Agents still make mistakes. Meta itself recommends human confirmation before consequential actions, which is the same advice we give for any agent that can act on your APIs.
Frequently asked questions
Is Muse Wonder open weights like Llama? No. Both Wonder models are closed and served only through Meta’s API, Muse Code, and partner gateways. There is nothing to download.
Which API format does it use? Three. The Responses API is Meta’s recommended surface for multi-step work, Chat Completions works with any OpenAI SDK, and the Messages endpoint accepts Anthropic-format requests. Reasoning effort runs from minimal to max; none returns a 400 because the model always reasons.
Is it better than Claude Opus 5.5? On Meta’s agentic benchmarks, Wonder Full leads on long coding runs and legal work. On the independent index, Opus 5.5 is still ahead of both Wonder models, and it beats them on terminal tasks and health. The head-to-head covers it; the short version is that they are priced identically and win different jobs.
Can I try it before paying? Only by spending cents on the API. A few test calls at $4 / $20 cost less than a coffee. Download Apidog, store the key as a secret variable, and run them from one project.
Where this leaves you
Muse Wonder is a credible frontier entry priced at Opus 5.5 rates, with a real edge on long-running agent tasks and a real gap on knowledge and terminal work. The model that wins Meta’s headline benchmarks is behind a $50 subscription. If you build agents, it is worth a test on your own tasks this week, measured on tokens consumed rather than list price.