Claude Fable 5.1 is Anthropic’s newest Fable-tier model, released on September 1, 2026, alongside its access-gated twin Claude Mythos 5.1. It replaces Claude Fable 5 at the same $10 per million input tokens and $50 per million output tokens, with one pricing change that matters for agents: prompt cache reads now cost $0.25 per million tokens, a quarter of what Fable 5 charged. Anthropic positions it “for demanding reasoning and long-horizon agentic work,” and its docs still tell you to start with Opus 5 and reach for Fable 5.1 only when Opus 5 at higher effort falls short.
This guide is the map for the whole launch: specs, the cache-read pricing story, Anthropic’s benchmark claims and how much weight they deserve, the three API changes that break Fable 5 code, the five additive features, plan access, and the honest ceiling. Every request in this cluster is plain HTTP with JSON, so you can build and inspect them in Apidog before they touch application code. Anthropic’s launch post and the Fable 5.1 model page are the primary sources.
Each section links to a focused deep dive: the API walkthrough, the cost math, and the migration from Fable 5 and Opus 5.
Claude Fable 5.1 at a glance
| Spec | Value |
|---|---|
| API model ID | claude-fable-5-1 (no date suffix) |
| Released | September 1, 2026 |
| Retirement commitment | Not sooner than September 1, 2027 |
| Context window | 1,000,000 tokens, default and maximum, standard pricing across the window |
| Max output | 128,000 tokens on the Messages API |
| Base pricing | $10 per million input tokens, $50 per million output tokens |
| Cache reads | $0.25 per million tokens (0.025x base input; every other Claude model is 0.1x) |
| Batch API | $5 input, $25 output per million tokens |
| Knowledge cutoff | June 2026 (reliable and training data) |
| Thinking | Adaptive, always on; cannot be disabled |
| Effort levels | low, medium, high, xhigh, max; defaults to high |
| Comparative latency | Slower than Opus 5 and Sonnet 5 |
| Priority Tier | Not supported (Fable 5 supported it) |
| Data retention | 30-day retention required; no zero data retention unless Anthropic expressly authorizes it |
| Availability | Claude API, Amazon Bedrock, Claude Platform on AWS, Google Cloud, Microsoft Foundry; claude.ai (Pro, Max, Team, Enterprise); Claude Code 2.1.250+ |
Three rows deserve a second look. The June 2026 cutoff is the freshest of any Claude model; Opus 5 sits at May 2026 and Sonnet 5 at January 2026. Priority Tier moved backwards: Fable 5 supports it and Fable 5.1 does not. And the retention rule produces a confusing error: a request from an organization without 30-day retention returns 400 invalid_request_error, so check that setting before you debug a payload.
What Claude Fable 5.1 is
Fable 5.1 succeeds Fable 5 in the same tier, at the same per-token price, on the same tokenizer (introduced with Opus 4.7, roughly 30% more tokens per text than pre-4.7 models). Anthropic calls Fable 5.1 and Mythos 5.1 “the same model but with different levels of safeguards.” Fable 5.1 is generally available. Mythos 5.1 is offered only to approved customers in Project Glasswing, through the Cyber Verification Program and the Life Sciences Verification Program, and it powers Anthropic’s Claude Security product. The Mythos 5.1 vs Fable 5.1 comparison covers where the two diverge.
If you followed the Fable 5 story, the context matters. Fable 5 was suspended in June 2026 under U.S. export controls and came back on July 1 with a retrained safety classifier. Fable 5.1 keeps that classifier architecture and the same refusal categories, but Anthropic reports the classifiers fire far less often on benign work.
Anthropic’s docs are direct about where it fits: start with Opus 5 for most workloads, and use Fable 5.1 “for demanding reasoning and long-horizon agentic work, or when your evals on Claude Opus 5 at higher effort still fall short.” The Fable 5.1 vs Opus 5 comparison works through that rule by workload.
The cache-read pricing story
Per-token prices did not move. The cache-read multiplier did. Every other Claude model prices a cache hit at 0.1x base input. Fable 5.1 and Mythos 5.1 price it at 0.025x, which is $0.25 per million.
| Model | Base input | Cache read | Output |
|---|---|---|---|
| Claude Fable 5.1 | $10 | $0.25 | $50 |
| Claude Fable 5 | $10 | $1.00 | $50 |
| Claude Opus 5 | $5 | $0.50 | $25 |
| Claude Sonnet 5 | $2 | $0.20 | $10 |
Two consequences. A Fable 5.1 cache hit is cheaper than an Opus 5 cache hit, even though Fable 5.1’s base price is double. And long agentic sessions that re-read a cached prefix every turn get most of the saving, which is why Anthropic quotes “an estimated 25%” cheaper for typical workloads and “up to approximately 45%” for highly agentic ones. Those are Anthropic’s estimates for Anthropic’s mix; the pricing breakdown reproduces the math so you can plug in your own cache-hit ratio. Cache writes ($12.50 and $20 per million) and the 512-token cache minimum are unchanged. Because a miss now costs 40x a hit, keeping the cache warm matters more than it did on Fable 5.
What Anthropic says the benchmarks show
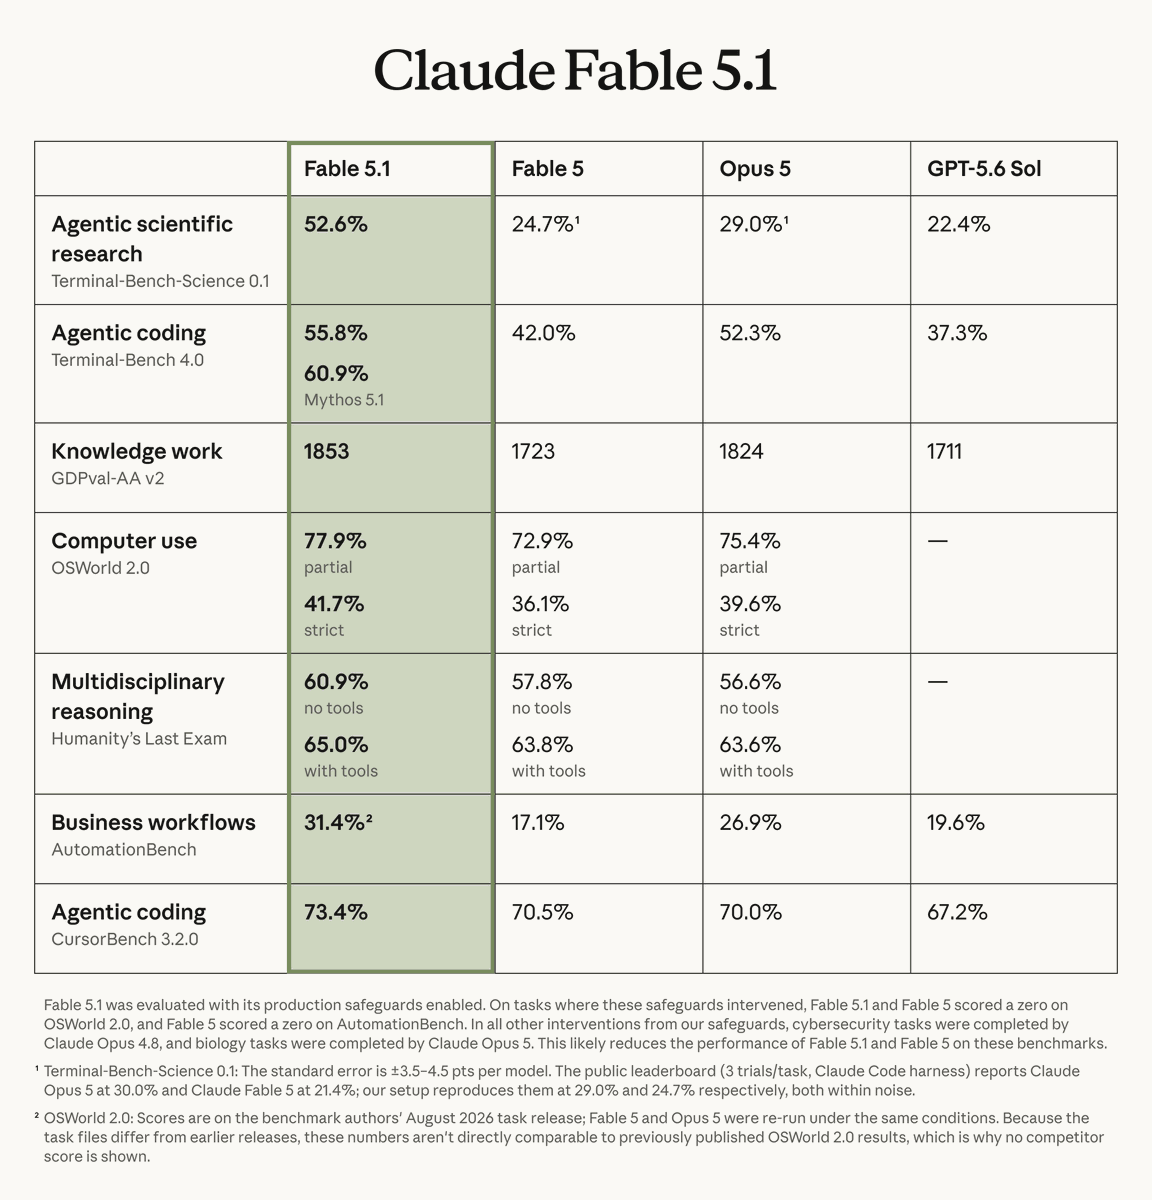
Every number is Anthropic-run, with no independent reproduction yet.
| Benchmark | Fable 5.1 | Fable 5 | Opus 5 | GPT-5.6 Sol |
|---|---|---|---|---|
| Terminal-Bench-Science 0.1 | 52.6% | 24.7% | 29.0% | 22.4% |
| Terminal-Bench 4.0 | 55.8% | 42.0% | 52.3% | 37.3% |
| GDPval-AA v2 (knowledge work) | 1853 | 1723 | 1824 | 1711 |
| OSWorld 2.0 (partial credit) | 77.9% | 72.9% | 75.4% | not reported |
| OSWorld 2.0 (strict) | 41.7% | 36.1% | 39.6% | not reported |
| Humanity’s Last Exam (no tools) | 60.9% | 57.8% | 56.6% | not reported |
| Humanity’s Last Exam (with tools) | 65.0% | 63.8% | 63.6% | not reported |
| AutomationBench | 31.4% | 17.1% | 26.9% | 19.6% |
| CursorBench 3.2.0 | 73.4% | 70.5% | 70.0% | 67.2% |
Anthropic also reports Mythos 5.1 at 60.9% on Terminal-Bench 4.0, five points above Fable 5.1, which is the clearest published evidence that the safeguards cost some capability on agentic coding.
The Terminal-Bench-Science result more than doubles Fable 5 and is the number every outlet led with. The CursorBench gap to Opus 5 is 3.4 points, a real but modest edge for a model that costs twice as much per token. The benchmarks breakdown goes row by row.
The three changes that break Fable 5 code
Migration from Fable 5 is mostly drop-in, but three things return errors Fable 5 never did, all documented in What’s new in Claude Fable 5.1.
1. Forced tool use returns a 400. tool_choice: {"type": "any"} and {"type": "tool", "name": "..."} are rejected with tool_choice: type "tool" and "any" are not supported for this model. The replacement is auto plus an instruction naming the tool, with strict: true on the tool if you need schema-valid arguments, or structured outputs if the forced call only existed to get JSON back.
2. Older models cannot read Fable 5.1 thinking blocks. Fable 5.1 reads blocks from Opus 5, Fable 5, and earlier models. The reverse is not true. When a router, retry, or refusal fallback moves a Fable 5.1 conversation to Opus 5, the API drops the blocks, unbilled, and the target model re-plans without them.
3. Editing earlier turns invalidates thinking blocks. A Fable 5.1 thinking block is valid only against the exact system prompt, tools array, and history that preceded it. Change any of those and the next request fails with a 400 saying the block is “bound to a different conversation.” The check is enforced for accounts created on or after August 31, 2026, and Anthropic frames it as an anti-distillation measure. If your code builds the messages array itself, budget time here. The preserved thinking guide explains the error, the drop_block escape hatch, and the append-only patterns that keep both the thinking and the cache intact.
Everything else carries over: thinking cannot be disabled, prefill returns a 400, non-default temperature returns a 400, and thinking.display defaults to "omitted". The migration guide has the before-and-after snippets.
The five additive features
- Per-message effort (beta). An empty-content
role: "system"message withoutput_config: {"effort": "low"}changes effort from the next user turn onward without invalidating the cache. Headermid-conversation-output-config-2026-07-01. - Turn-scoped system messages (beta).
clear_at: "next_user_message"gives a mid-conversation system message authority for one turn, then stops rendering. Headermid-conversation-system-clear-at-2026-08-21. This replaces injecting a reminder and deleting it next request. - Progress updates between tool calls (beta).
thinking.display: "updates"returns the model’s between-tool notes as text while reasoning stays hidden. Headerthinking-display-updates-2026-08-18. - Lower cache-read price. Covered above.
- Content provenance. Text carries Anthropic’s statistical watermark on every platform; supported media from the code-execution sandbox carries C2PA credentials via the Files API. Our watermarking explainer covers the mechanism.
How Fable 5.1 behaves differently
Anthropic’s prompting guide lists the shifts you will notice without changing code. Three affect API integrations: one tool call per turn in long agent loops where Fable 5 batched several; fewer progress messages between tool calls; and more answers from memory at low effort. The rest are style: denser prose, less chat formatting, unmarked quotations in summaries, and whole-file rewrites. Each has a one-paragraph fix, collected in the prompting guide. On effort, start at high and re-run your sweep; Anthropic claims medium roughly matches Fable 5 at lower cost.
The honest ceiling
Fable 5.1 still runs safety classifiers. A declined request returns HTTP 200 with stop_reason: "refusal" and a stop_details.category of cyber, bio, frontier_llm, reasoning_extraction, or general_harms. Anthropic’s improvement figures: biology classifiers fire 85% less often on benign questions than Fable 5’s did at launch, and cyber safeguards cause around 60% fewer interventions per Claude Code session. Fable 5.1 can now identify vulnerabilities in code you own, but it will not develop exploits; that stays with Mythos 5.1.
Handle refusals in code. The permitted fallback targets are Opus 4.8 and Opus 5, and the simplest setup is fallbacks: "default" with the server-side-fallback-2026-07-01 header. A refusal before any output is not billed. Our refusal handling guide still applies, with the caveat that the fallback model cannot read Fable 5.1’s thinking blocks. Two more limits: Mythos 5.1 outscores Fable 5.1 where both were published, and the classifiers are broader than Opus 5’s cyber-only set.
Where you can run it
Fable 5.1 is on the Claude API as claude-fable-5-1, on Amazon Bedrock as anthropic.claude-fable-5-1, and on Claude Platform on AWS, Google Cloud, and Microsoft Foundry as claude-fable-5-1. The setup on each is the same as for Fable 5, which our cloud availability guide covers. In the Claude apps it is on Pro, Max, Team, and Enterprise, not Free. Max includes Fable models for up to 50% of the weekly limit; Pro meters them through usage credits. Claude Code needs 2.1.250 or later. The Claude Code guide and the free and cheapest paths guide have the details.
Testing Fable 5.1 requests in Apidog
In Apidog, create a POST to https://api.anthropic.com/v1/messages with the x-api-key and anthropic-version: 2023-06-01 headers and this body:
{
  "model": "claude-fable-5-1",
  "max_tokens": 16000,
  "output_config": {"effort": "high"},
  "messages": [
    {"role": "user", "content": "Review this pagination handler and list the edge cases it misses."}
  ]
}
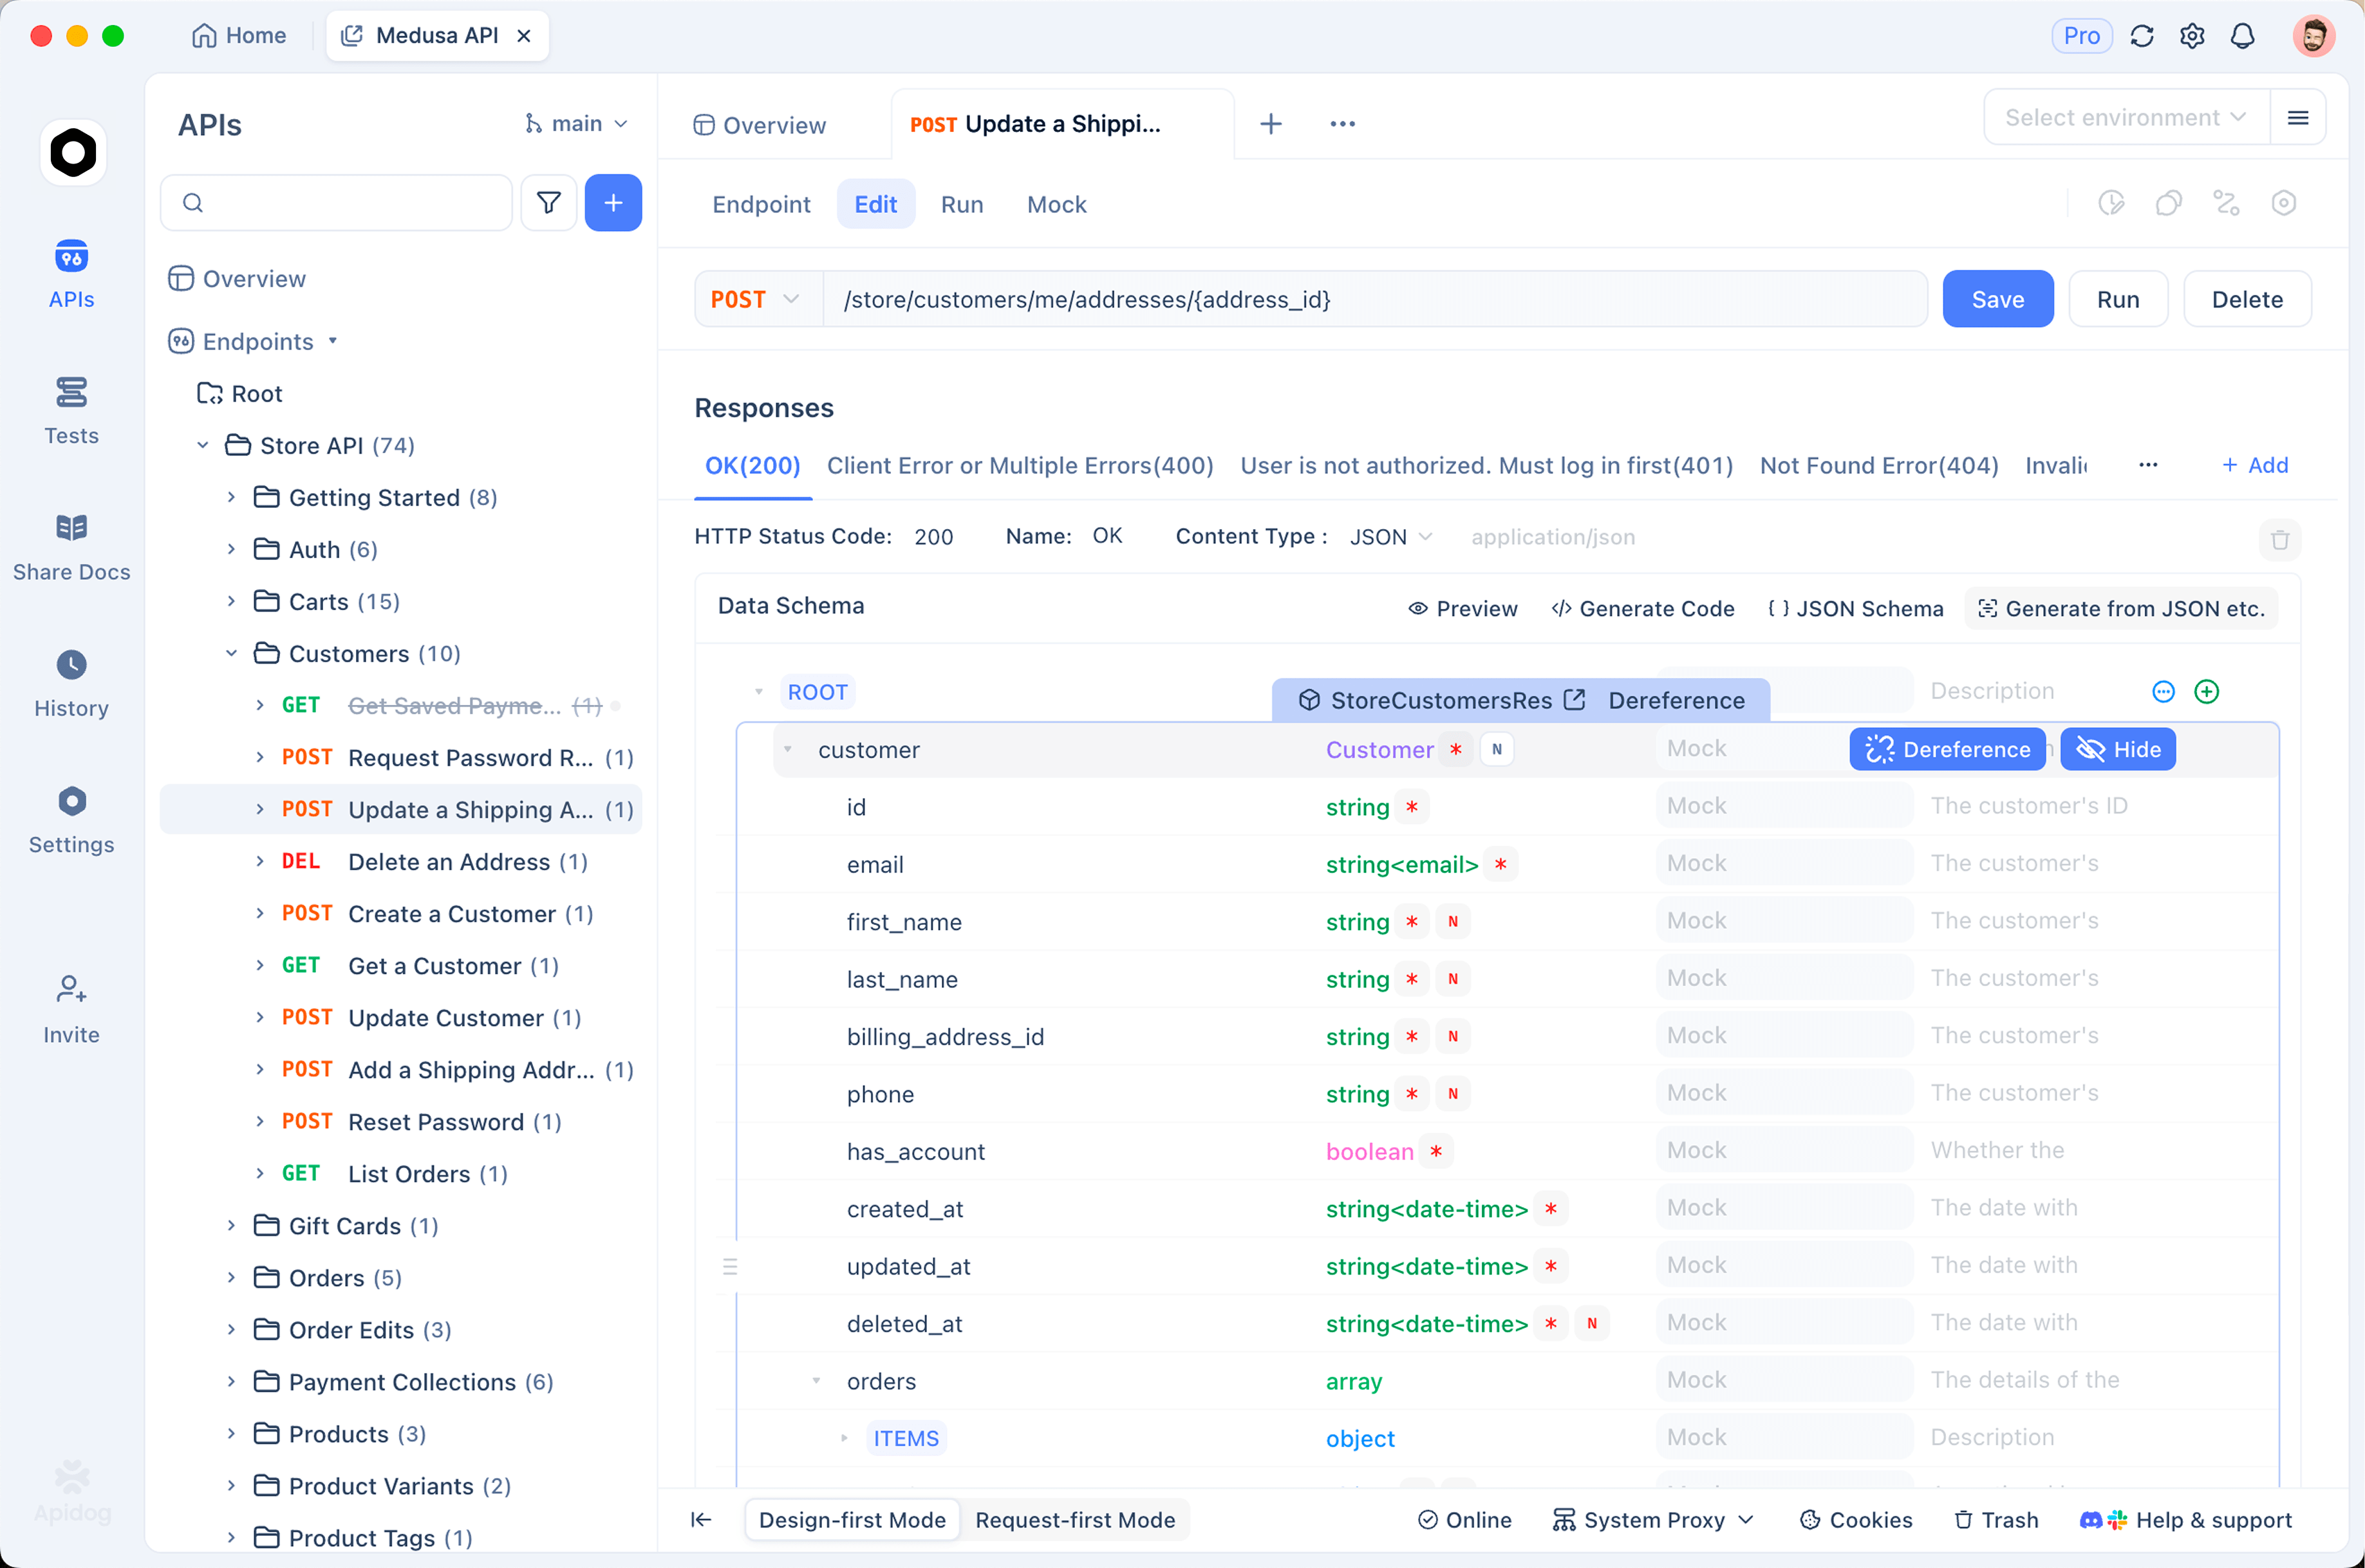
No thinking field is needed. Give max_tokens room, since it caps thinking and response together. Inspect stop_reason (branch on refusal before reading content), the empty thinking block, and usage.cache_read_input_tokens on the second send, where the $0.25 rate shows up. Download Apidog to save it as a test case.
Who should use Claude Fable 5.1
Reach for it when your agents run for hours, when you are on Fable 5 today (same price, cheaper cache, better numbers; see the Fable 5.1 vs Fable 5 comparison), when Opus 5 at xhigh still misses, or when you need June 2026 knowledge. Stay where you are when Priority Tier is load-bearing, when your org is on zero data retention, when your harness edits conversation history, or when the workload is cheap and high volume, where Opus 5 or Sonnet 5 is enough.
FAQ
What is the model ID for Claude Fable 5.1? The exact string claude-fable-5-1. On Amazon Bedrock use anthropic.claude-fable-5-1.
How much does Claude Fable 5.1 cost? $10 per million input tokens and $50 per million output tokens, the same as Fable 5. Cache reads are $0.25 per million, down from $1. Batch is $5 and $25. No fast mode, no Priority Tier.
Is Claude Fable 5.1 better than Fable 5? On every benchmark Anthropic published, yes, with the largest gains on Terminal-Bench-Science (52.6% vs 24.7%) and AutomationBench (31.4% vs 17.1%). Those are vendor-run results.
What breaks when I switch from Fable 5? Forced tool_choice returns a 400, older models cannot read Fable 5.1 thinking blocks, and editing earlier turns invalidates later thinking blocks on accounts created on or after August 31, 2026.
Does Fable 5.1 still refuse cybersecurity requests? Sometimes. Anthropic reports around 60% fewer cyber interventions per Claude Code session and permits finding vulnerabilities in code. Exploit development is still declined.
Can I use Claude Fable 5.1 for free? Not on the Free plan. Pro uses usage credits; Max includes it for up to 50% of the weekly limit. The API has no free tier beyond the signup credit.