Claude Opus 5.5 is Anthropic’s newest Opus-tier model, released on September 22, 2026. It landed on the same day OpenAI shipped GPT-6 Sol and GPT-6 Luna, which is why your feed spent that week arguing about price per token instead of reading either launch page.
If you have claude-opus-5 sitting in a config file, here is the short version of what the id change buys you. Opus 5.5 costs $4 per million input tokens and $20 per million output tokens, down from $5 and $25 on Opus 5. It carries a 1,000,000 token context window and a 128,000 token maximum output. Anthropic says it runs 40% cheaper than Opus 5, produces output 30% faster, and stays on a single task for 18 or more hours. On the Artificial Analysis Intelligence Index it ranks first of 212 models with a score of 58, though that index is a third party measurement and not a vendor claim.
This guide covers the spec sheet, the eight benchmark scores Anthropic published, the caching arithmetic that decides your real bill, and the comparisons you should refuse to make. Every request below is plain HTTP with JSON, so you can build and inspect it in Apidog. For the wider context of three frontier launches in two days, see the September 2026 model price war.
Claude Opus 5.5 at a glance
| Spec | Value |
|---|---|
| API model ID | claude-opus-5-5 |
| Released | September 22, 2026 |
| Input pricing | $4 per million tokens |
| Output pricing | $20 per million tokens |
| Cached input read | $0.20 per million tokens |
| Cache write | $5 per million tokens |
| Fast mode | $8 input / $40 output per million tokens |
| Context window | 1,000,000 tokens |
| Max output | 128,000 tokens |
| Cost to run vs Opus 5 | 40% less, per Anthropic |
| Output speed vs Opus 5 | 30% faster, per Anthropic |
| Sustained task length | 18+ hours on task |
| Safety | 85% fewer successful boundary-circumvention attempts |
| Availability | Claude Platform, AWS, Google Cloud, Azure |
| Artificial Analysis Intelligence Index | 58, ranked #1 of 212 (third party) |
Two rows deserve a second look. The cached read rate of $0.20 is 5% of the standard input rate, which changes what architectures are affordable. And the 18 hour figure is a claim about task persistence, not about a request timeout. Those are very different engineering problems.
What changed from Opus 5
The model id is the obvious break. Anthropic uses a dotted product name and an undotted API id, so Claude Opus 5.5 is claude-opus-5-5. A string replace over your config is the first migration step.
| Claude Opus 5 | Claude Opus 5.5 | |
|---|---|---|
| API model ID | claude-opus-5 |
claude-opus-5-5 |
| Input per million | $5 | $4 |
| Output per million | $25 | $20 |
That is a 20% cut on both sides of the meter. Anthropic separately says Opus 5.5 costs 40% less to run than Opus 5, which is a different measurement and worth keeping straight. A price cut per token plus fewer tokens spent finishing the same work compounds into a larger drop in cost per task. Cost per token is what you verify on an invoice. Cost per task is what the vendor measured on its own evaluations, so reproduce it on your workload before you budget against it.
The rest of the delta is behavioral: 30% faster output, 18 or more hours of sustained work on one task, and 85% fewer successful boundary-circumvention attempts. That last number is a narrow security claim, not a general “safer” badge. Our prompt injection and API security piece unpacks what it measures. For the previous generation’s spec sheet, see what is Claude Opus 5.
The eight benchmark scores Anthropic published
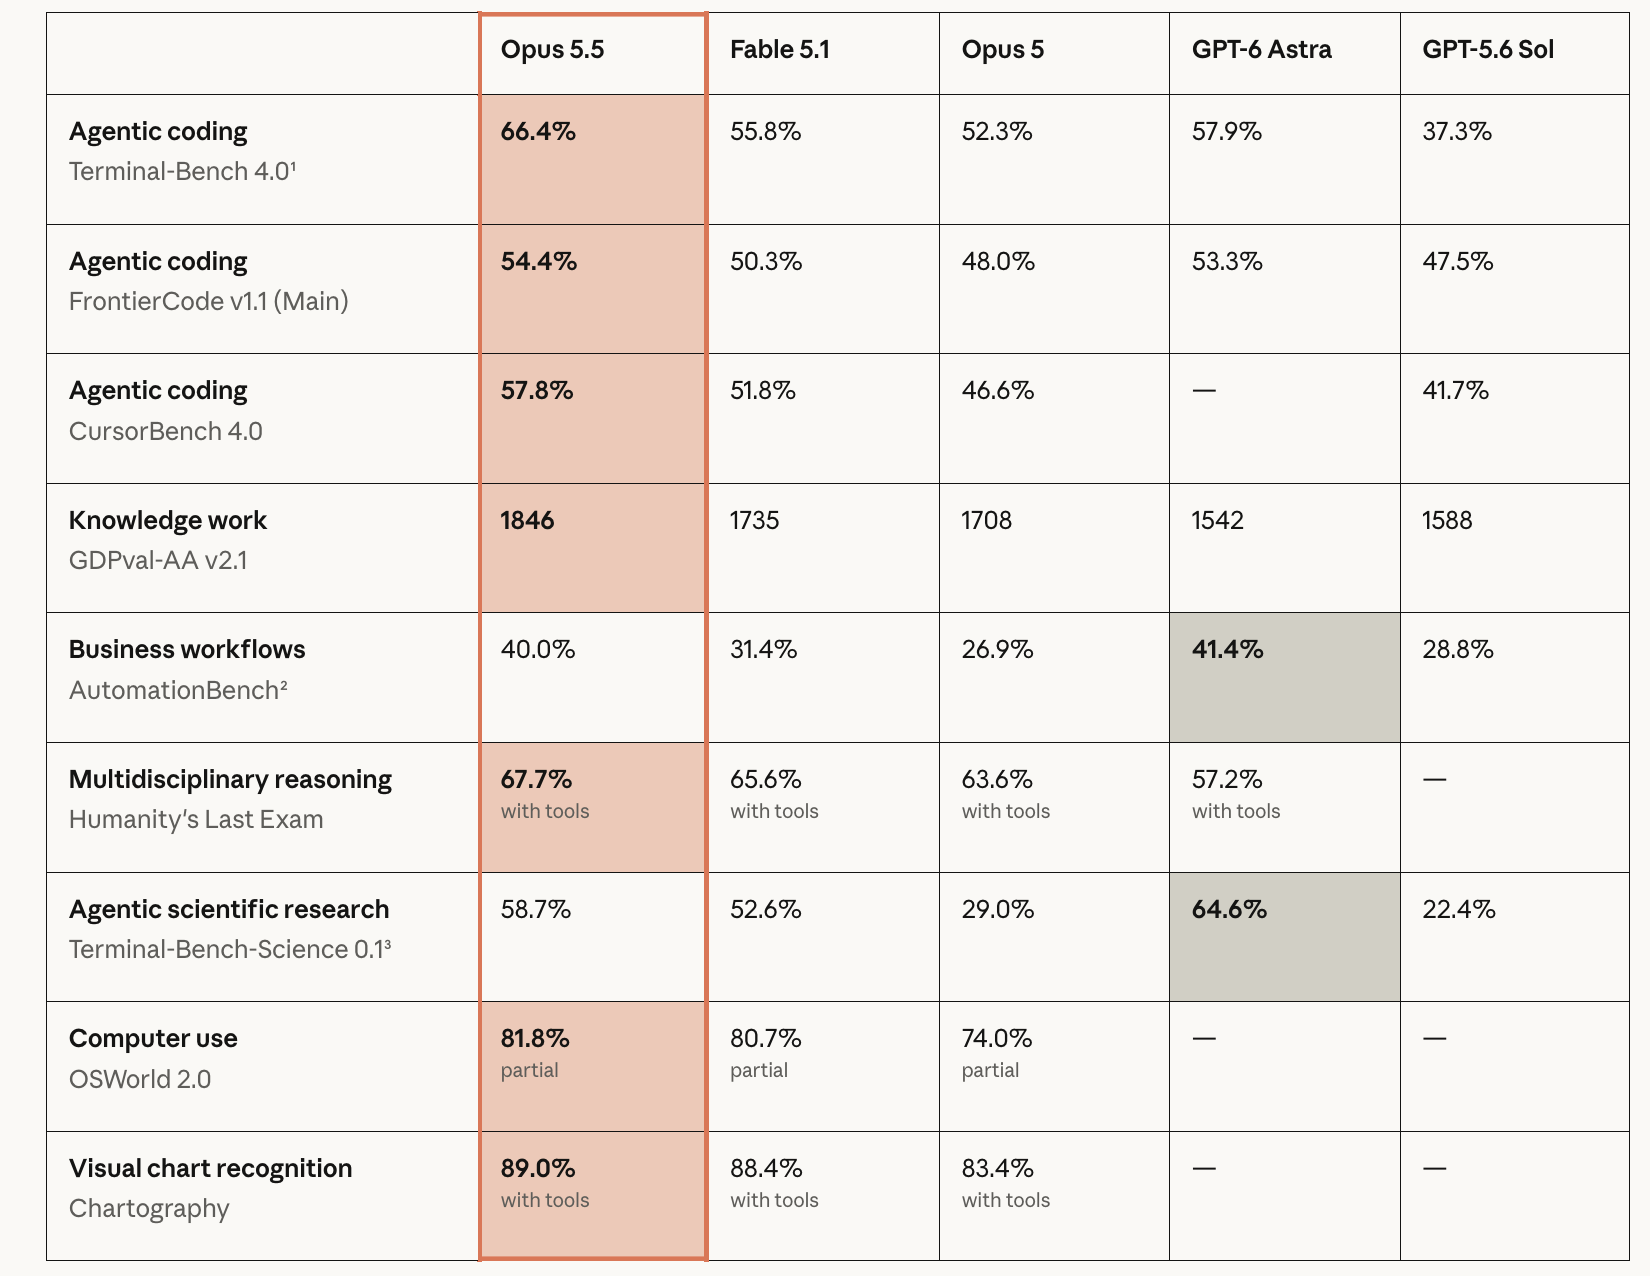
These are Anthropic-run numbers from its own launch material.
| Benchmark | Claude Opus 5.5 |
|---|---|
| Terminal-Bench 4.0 | 66.4% |
| FrontierCode v1.1 | 54.4% |
| CursorBench 4.0 | 57.8% |
| GDPval-AA v2.1 | 1846 Elo |
| AutomationBench | 40.0% |
| Humanity’s Last Exam, with tools | 67.7% |
| OSWorld 2.0 | 81.8% |
| Chartography | 89.0% |
Notice what is missing: opposing columns. Anthropic published scores, not a head-to-head grid against GPT-6, so anyone showing you a tidy Opus 5.5 versus Astra table built from these rows assembled it themselves.
AutomationBench is the trap, because it appears on both vendors’ launch materials. OpenAI’s numbers are from AutomationBench 1.0.6 and put GPT-6 Sol at extra-high reasoning on 33.2%, GPT-6 Astra at low on 30.3%, and Claude Opus 5 at max on 26.9%. Anthropic’s 40.0% for Opus 5.5 comes from its own run, and the version and effort level are not stated in the material we verified. Two vendors, two harnesses, two effort settings, possibly two benchmark versions. Do not subtract one from the other and call the difference a lead.
Where Opus 5.5 sits in the September 22 field
| Model | API id | In $/M | Out $/M | Context | AA Index |
|---|---|---|---|---|---|
| Claude Opus 5.5 | claude-opus-5-5 |
$4 | $20 | 1M | 58 |
| GPT-6 Sol | gpt-6-sol |
$2 | $10 | 872k | 48 |
| GPT-6 Luna | gpt-6-luna |
$0.10 | $0.50 | 1M | 37 |
| GPT-6 Astra | n/a | $10 | $50 | n/a | n/a |
| Claude Opus 5 | claude-opus-5 |
$5 | $25 | n/a | n/a |
| Grok 4.7 | n/a | $2 | $6 | n/a | n/a |
The Artificial Analysis column is a third party index, not a vendor claim, and one composite number stands in for a lot of very different tasks. Treat it as a sort order, not a verdict.
There is one genuinely useful thing to notice about the timing. OpenAI’s launch post benchmarks Sol and Luna against Claude Opus 5, because Opus 5.5 did not exist when that post was written. Anthropic shipped Opus 5.5 hours later at 20% below Opus 5’s price. So the widely quoted line that Sol at extra-high beats Opus 5 at max for 9% of the cost per task is true as written and measured against a model that was superseded the same day. Nobody has published the rerun.
The reverse claim is equally unsupported. OpenAI states that Astra “continues to be our best model across the board,” and neither vendor has published an Astra versus Opus 5.5 comparison. The specific head-to-head numbers circulating on X are tweets, not vendor data. If you need that answer, the only honest source is your own evaluation harness on your own tasks.
The caching arithmetic that decides your bill
At $4 input and $0.20 for a cached read, a cache hit costs 5% of a fresh read. Cache writes bill at $5 per million, a 25% premium over the standard input rate. That ratio makes the break-even shallow.
Take a 200,000 token system prefix, a tool schema plus a chunk of your codebase or spec. Uncached, every call bills 200,000 tokens at $4 per million, so $0.80 each. Ten calls cost $8.00 on input alone.
Cached, you pay the write once at $5 per million, so $1.00, then each subsequent read bills at $0.20 per million, so $0.04. Ten calls cost $1.00 plus nine reads at $0.04, which is $1.36. The write premium is repaid on the first re-read, and by the tenth call you pay about 17% of the uncached bill.
At the top of the range, sending the full 1,000,000 token window costs $4.00 as fresh input and $0.20 as a cached read. That is the difference between a context strategy you can run in a loop and one you cannot. The full caching cost model works through agent loops and multi-tenant prefixes.
Fast mode bills at $8 input and $40 output, exactly double the standard rate. Price it as a latency purchase for interactive paths, not as a default.
What 18 hours on task does to your API layer
A model that works for 18 hours is not a longer request. It is a different integration shape, and most API code written for chat completions will break on it.
Four things need attention. Timeouts at the load balancer, gateway, and client must tolerate long-lived streams, or you need a job-plus-polling design instead. Retries must be idempotent, because replaying a request that already burned three hours of tool calls is expensive in a way a retried GET never is. Streaming needs keepalive handling so an idle-looking connection is not reaped mid-task. And resumability matters more than throughput: if the process dies at hour 11, you need to know what state was durable. The 18 hour task API design piece covers each with concrete patterns.
Calling Claude Opus 5.5
The Messages API shape is unchanged. Swap the id and give max_tokens real room.
curl https://api.anthropic.com/v1/messages \
  --header "x-api-key: $ANTHROPIC_API_KEY" \
  --header "anthropic-version: 2023-06-01" \
  --header "content-type: application/json" \
  --data '{
    "model": "claude-opus-5-5",
    "max_tokens": 16384,
    "messages": [
      {"role": "user", "content": "Review this handler and list the failure modes."}
    ]
  }'
Two habits pay off immediately. Keep the key in an environment variable so it never lands in a shared collection. And read the usage block on every response, because that is where you confirm cached reads are landing rather than quietly rebilling at $4 per million. A cache that silently misses looks exactly like a working integration until the invoice arrives.
This is where an API client earns its keep. In Apidog you can save one baseline Messages request, duplicate it for streaming and non-streaming, run both on the same prompt, and assert on the usage fields so a cache regression fails a test instead of surprising you at month end. The SSE viewer also shows where a long stream actually stopped. Download Apidog and import the request above to follow along.
Availability
Anthropic lists Opus 5.5 on the Claude Platform, AWS, Google Cloud, and Azure. Consumer app tiers and the knowledge cutoff are not in the material we verified, so we are not printing either. Check Anthropic’s model page before writing a cutoff date into a system prompt.
Should you move?
Move if you are on claude-opus-5 today. Same tier, 20% less per token on both sides, better published numbers, and the only cost is the id swap plus a regression run. The migration notes cover the caller-visible details.
Think harder if your workload is cheap and high volume. Opus tier pricing is not where bulk classification or extraction belongs, and the September launches put a 1M context window into the sub-dollar tier. Compare against that tier before defaulting to Opus.
And measure before you believe any cross-vendor claim from that week, including the table above. Two labs shipped three frontier models on the same day, every published comparison was written against a model that had already been replaced, and the only benchmark that settles your decision is the one running your own requests.