Z.ai released GLM-5.3-Flash on August 26, 2026. It is a 320-billion-parameter mixture-of-experts model with 18 billion active parameters, it ships under the MIT license, and it is the first model in the GLM-5 series that handles images natively rather than through a bolted-on vision adapter.
It is also the model a lot of developers had already been using for a week without knowing it. More on that below.
If you came here expecting “Flash” to mean “fast,” this post is going to disagree with you. That naming convention comes from Google, where Flash models genuinely are the low-latency tier. Here it means something different, and getting that distinction right changes whether this model fits your workload.
TL;DR
- What it is: an open-weights (MIT) 320B-A18B mixture-of-experts model from Z.ai, released August 26, 2026.
- The headline change: native multimodality. Image, video, and file input go straight into the model. GLM-5.3 routes vision through separate adapters, and GLM-5.2 was text-only.
- Context: 1,048,576 tokens, the same 1M window as GLM-5.3.
- The real selling point: cost. Z.ai puts it at roughly one tenth the price of GLM-5.2, with a list rate of $0.15 per million input tokens and $0.50 per million output.
- The honest caveat: it is not fast. Artificial Analysis measures 48.7 output tokens per second, which is slow for its size class. Time to first token is genuinely good at 1.52 seconds.
- Where to get it: the Z.ai API as
glm-5.3-flash, plus OpenRouter, Cloudflare Workers AI, Vercel AI Gateway, and several other providers. Weights are on Hugging Face.
The specs
| Property | Value |
|---|---|
| Total parameters | 320B |
| Active parameters | 18B |
| Architecture | Mixture of experts, hybrid linear and sparse attention |
| License | MIT |
| Context window | 1,048,576 tokens |
| Input modalities | Text, image, video, files |
| Output | Text |
| Reasoning modes | low, high, max (default max) |
| API model id | glm-5.3-flash |
| Hugging Face | zai-org/GLM-5.3-Flash |
One number to treat carefully: maximum output tokens. OpenRouter lists 131,072 and the Hugging Face model card indicates 163,840. Those sources disagree and Z.ai has not published a figure that settles it. If your application depends on very long single generations, check the limit against your actual provider before you build around it.
Native multimodality is the actual news
Every previous vision capability in the GLM line arrived as a separate model or a separate pathway. Z.ai shipped GLM-5V-Turbo and GLM-4.6V as distinct vision models. If you wanted a GLM model to look at a screenshot, you called a different endpoint than the one your text traffic used.
GLM-5.3-Flash collapses that. Images, video, and files are content blocks in the same chat completion request that carries your text. There is one model id, one billing line, and one context window that holds your image and your million tokens of surrounding text at the same time.
That last part is the interesting bit. A 1M-token context window that also accepts images means you can put a long specification document and a screenshot of the rendered result in the same prompt and ask the model to reconcile them. Z.ai’s own framing leans on this: it describes the model observing “interfaces, rendering results, and interaction feedback,” which is a coding-agent use case, not a photo-captioning one.
If you are working with vision models more broadly, our guide to GLM-5V-Turbo’s API covers the older dedicated-vision approach, and GLM-OCR for document understanding covers the specialist case.
The architecture, briefly
Z.ai built GLM-5.3-Flash on a new base model rather than post-training GLM-5.2. Two design choices matter for how it behaves:
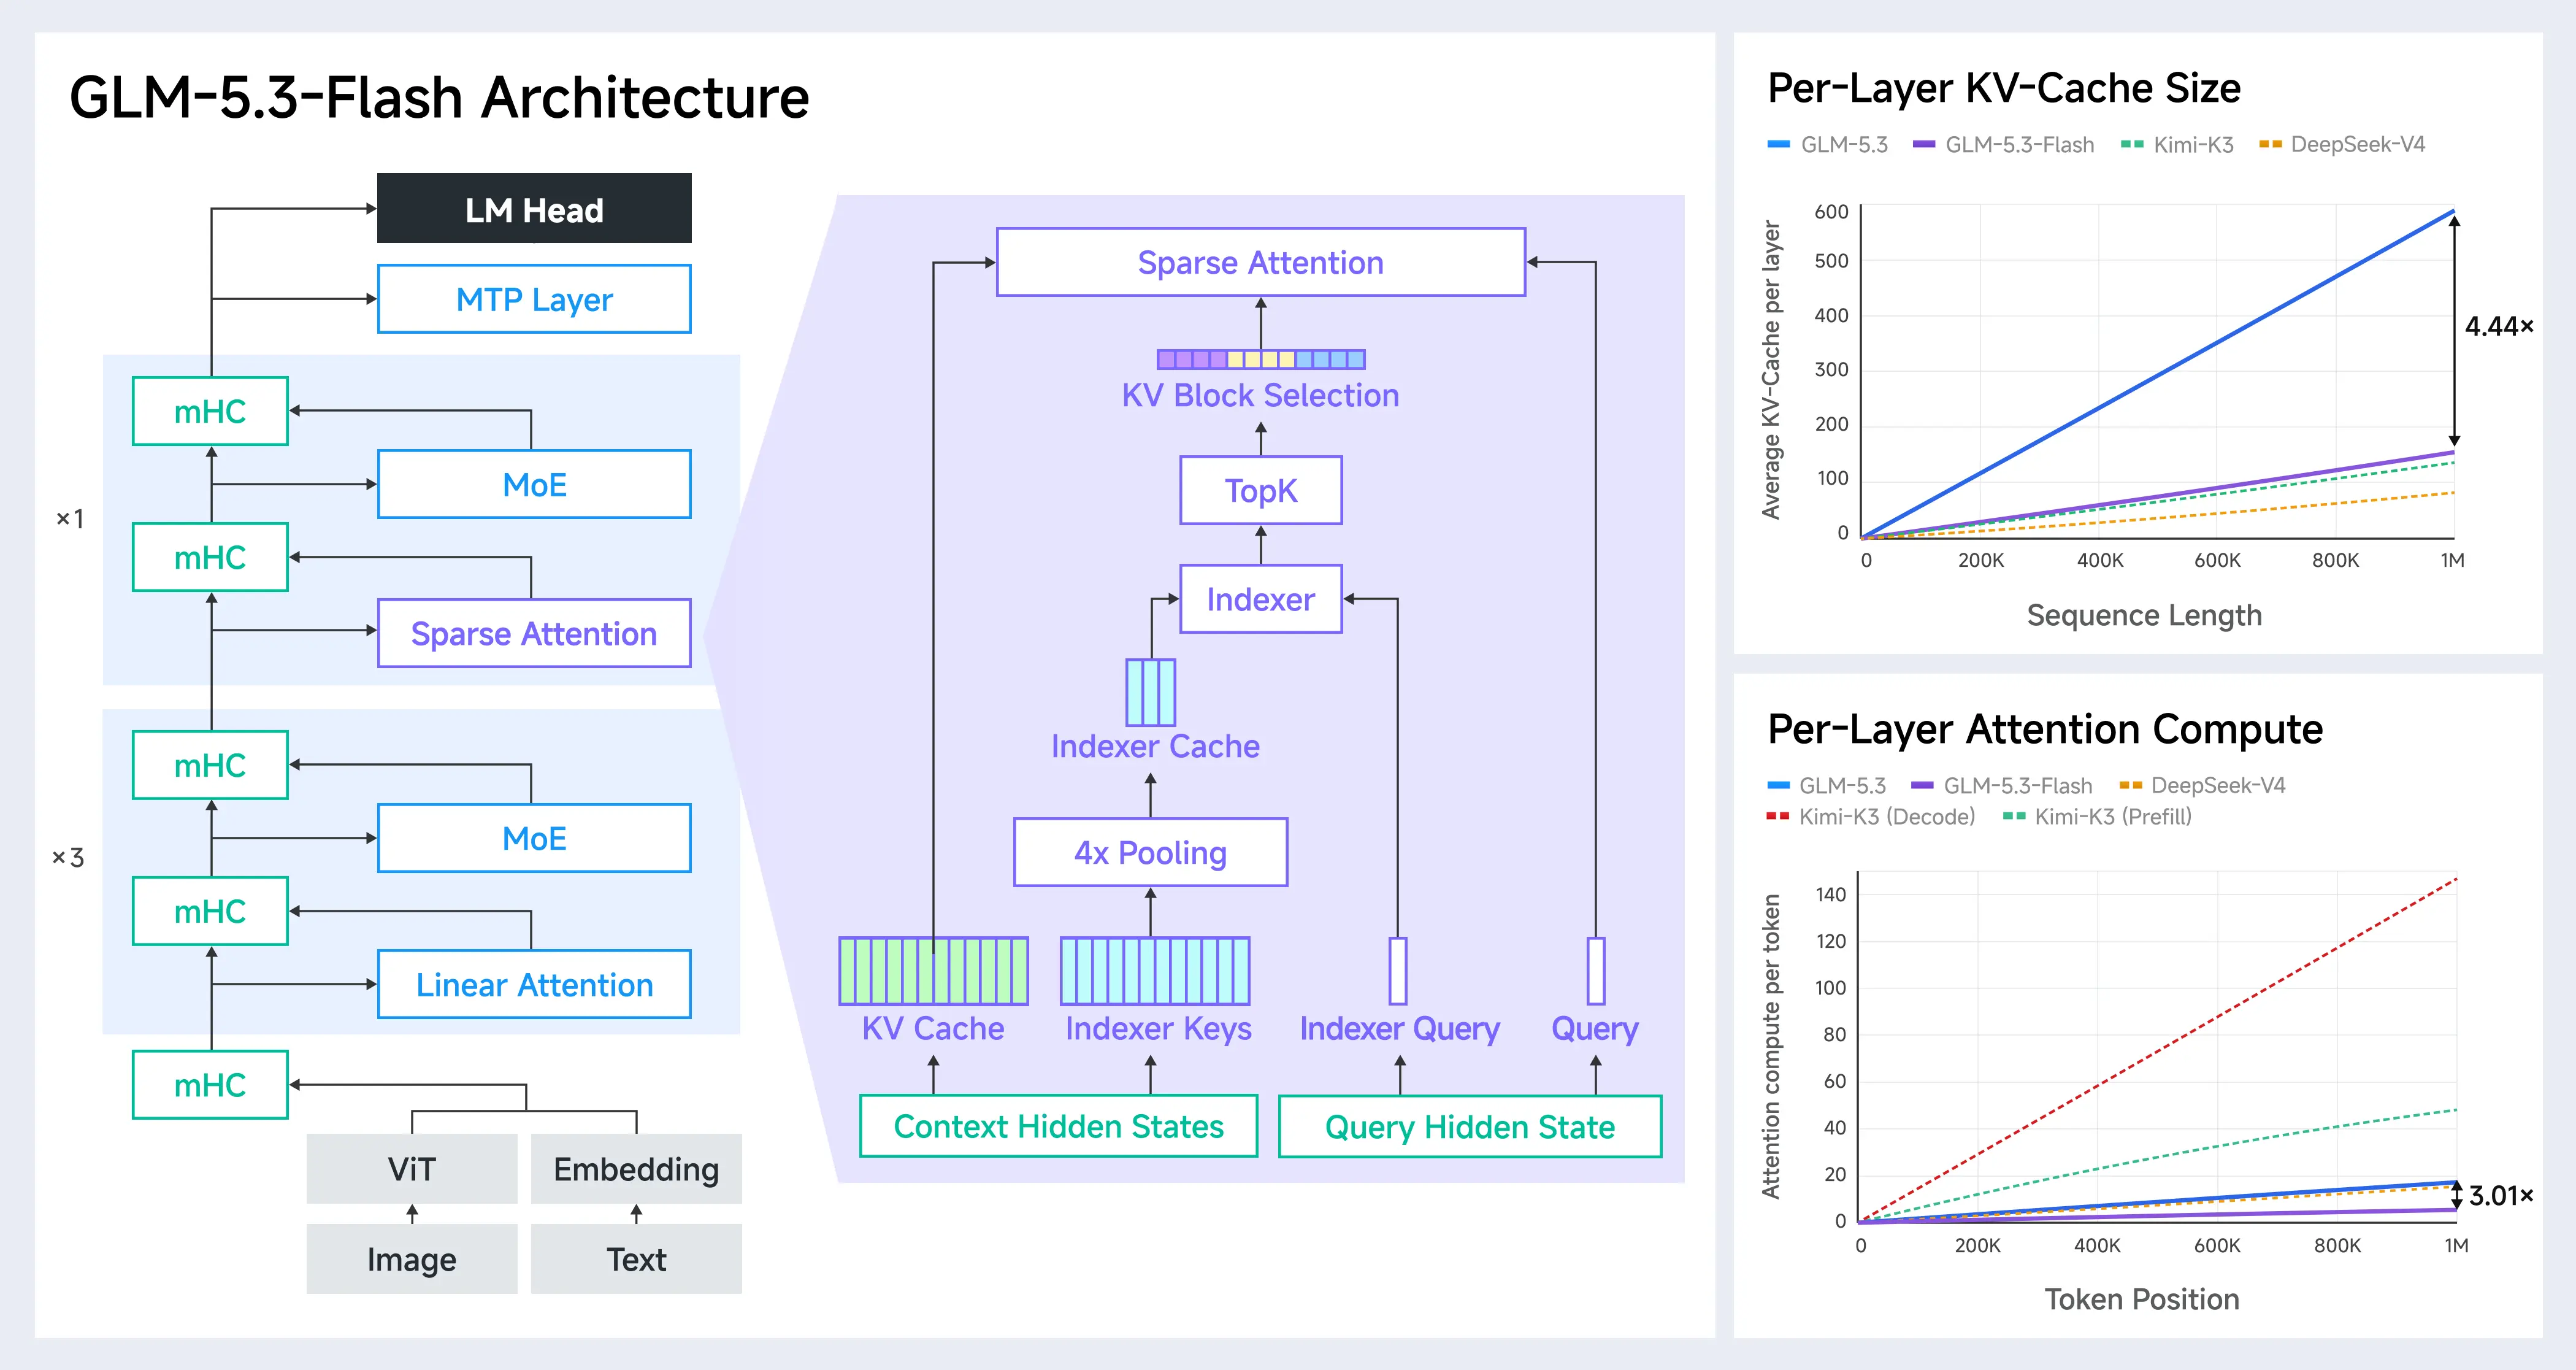
Hybrid attention. The model mixes linear attention with sparse attention. Linear attention handles local dependencies cheaply; sparse attention reaches for the globally relevant tokens. The stated result is roughly three times less attention compute than GLM-5.3 and a KV cache about 4.4 times smaller.
Manifold-Constrained Hyper-Connections. Z.ai’s term for its scaling-efficiency work in this release. There is not enough public detail yet to evaluate it independently, so treat it as a vendor-described architectural feature rather than a proven advantage.
The KV cache reduction is the part with obvious practical consequences. KV cache is what makes long-context inference expensive in memory, and shrinking it by 4.4x is most of the reason this model can be served at a tenth of GLM-5.2’s price while keeping a 1M window.
Training used a corpus Z.ai describes as roughly 30 trillion multimodal tokens.
About the name
Artificial Analysis measures GLM-5.3-Flash at 48.7 output tokens per second. For context, that is at the lower end for open-weight models of comparable size. GLM-5.3, the larger sibling, runs at about 86 tokens per second on the same measurement.
So the Flash model is roughly half the speed of the non-Flash model.
What it does win is time to first token, at 1.52 seconds against an open-weight median of 2.14 seconds. If your workload is many short interactive turns, that responsiveness is real. If your workload is generating long documents, you will wait longer than you would on GLM-5.3.
The efficiency this model delivers is in cost and memory, not wall-clock generation speed. The smaller KV cache and lower attention compute translate into a cheaper per-token price and a smaller serving footprint. They do not translate into faster streaming.
This matters because most of the coverage published in the days after launch repeated the vendor framing without checking the throughput number, which was public the whole time. Pick this model because it is inexpensive and handles images, not because you expect it to stream quickly.
Benchmarks
Numbers published at launch by Z.ai, so read them as vendor claims until third parties reproduce them:
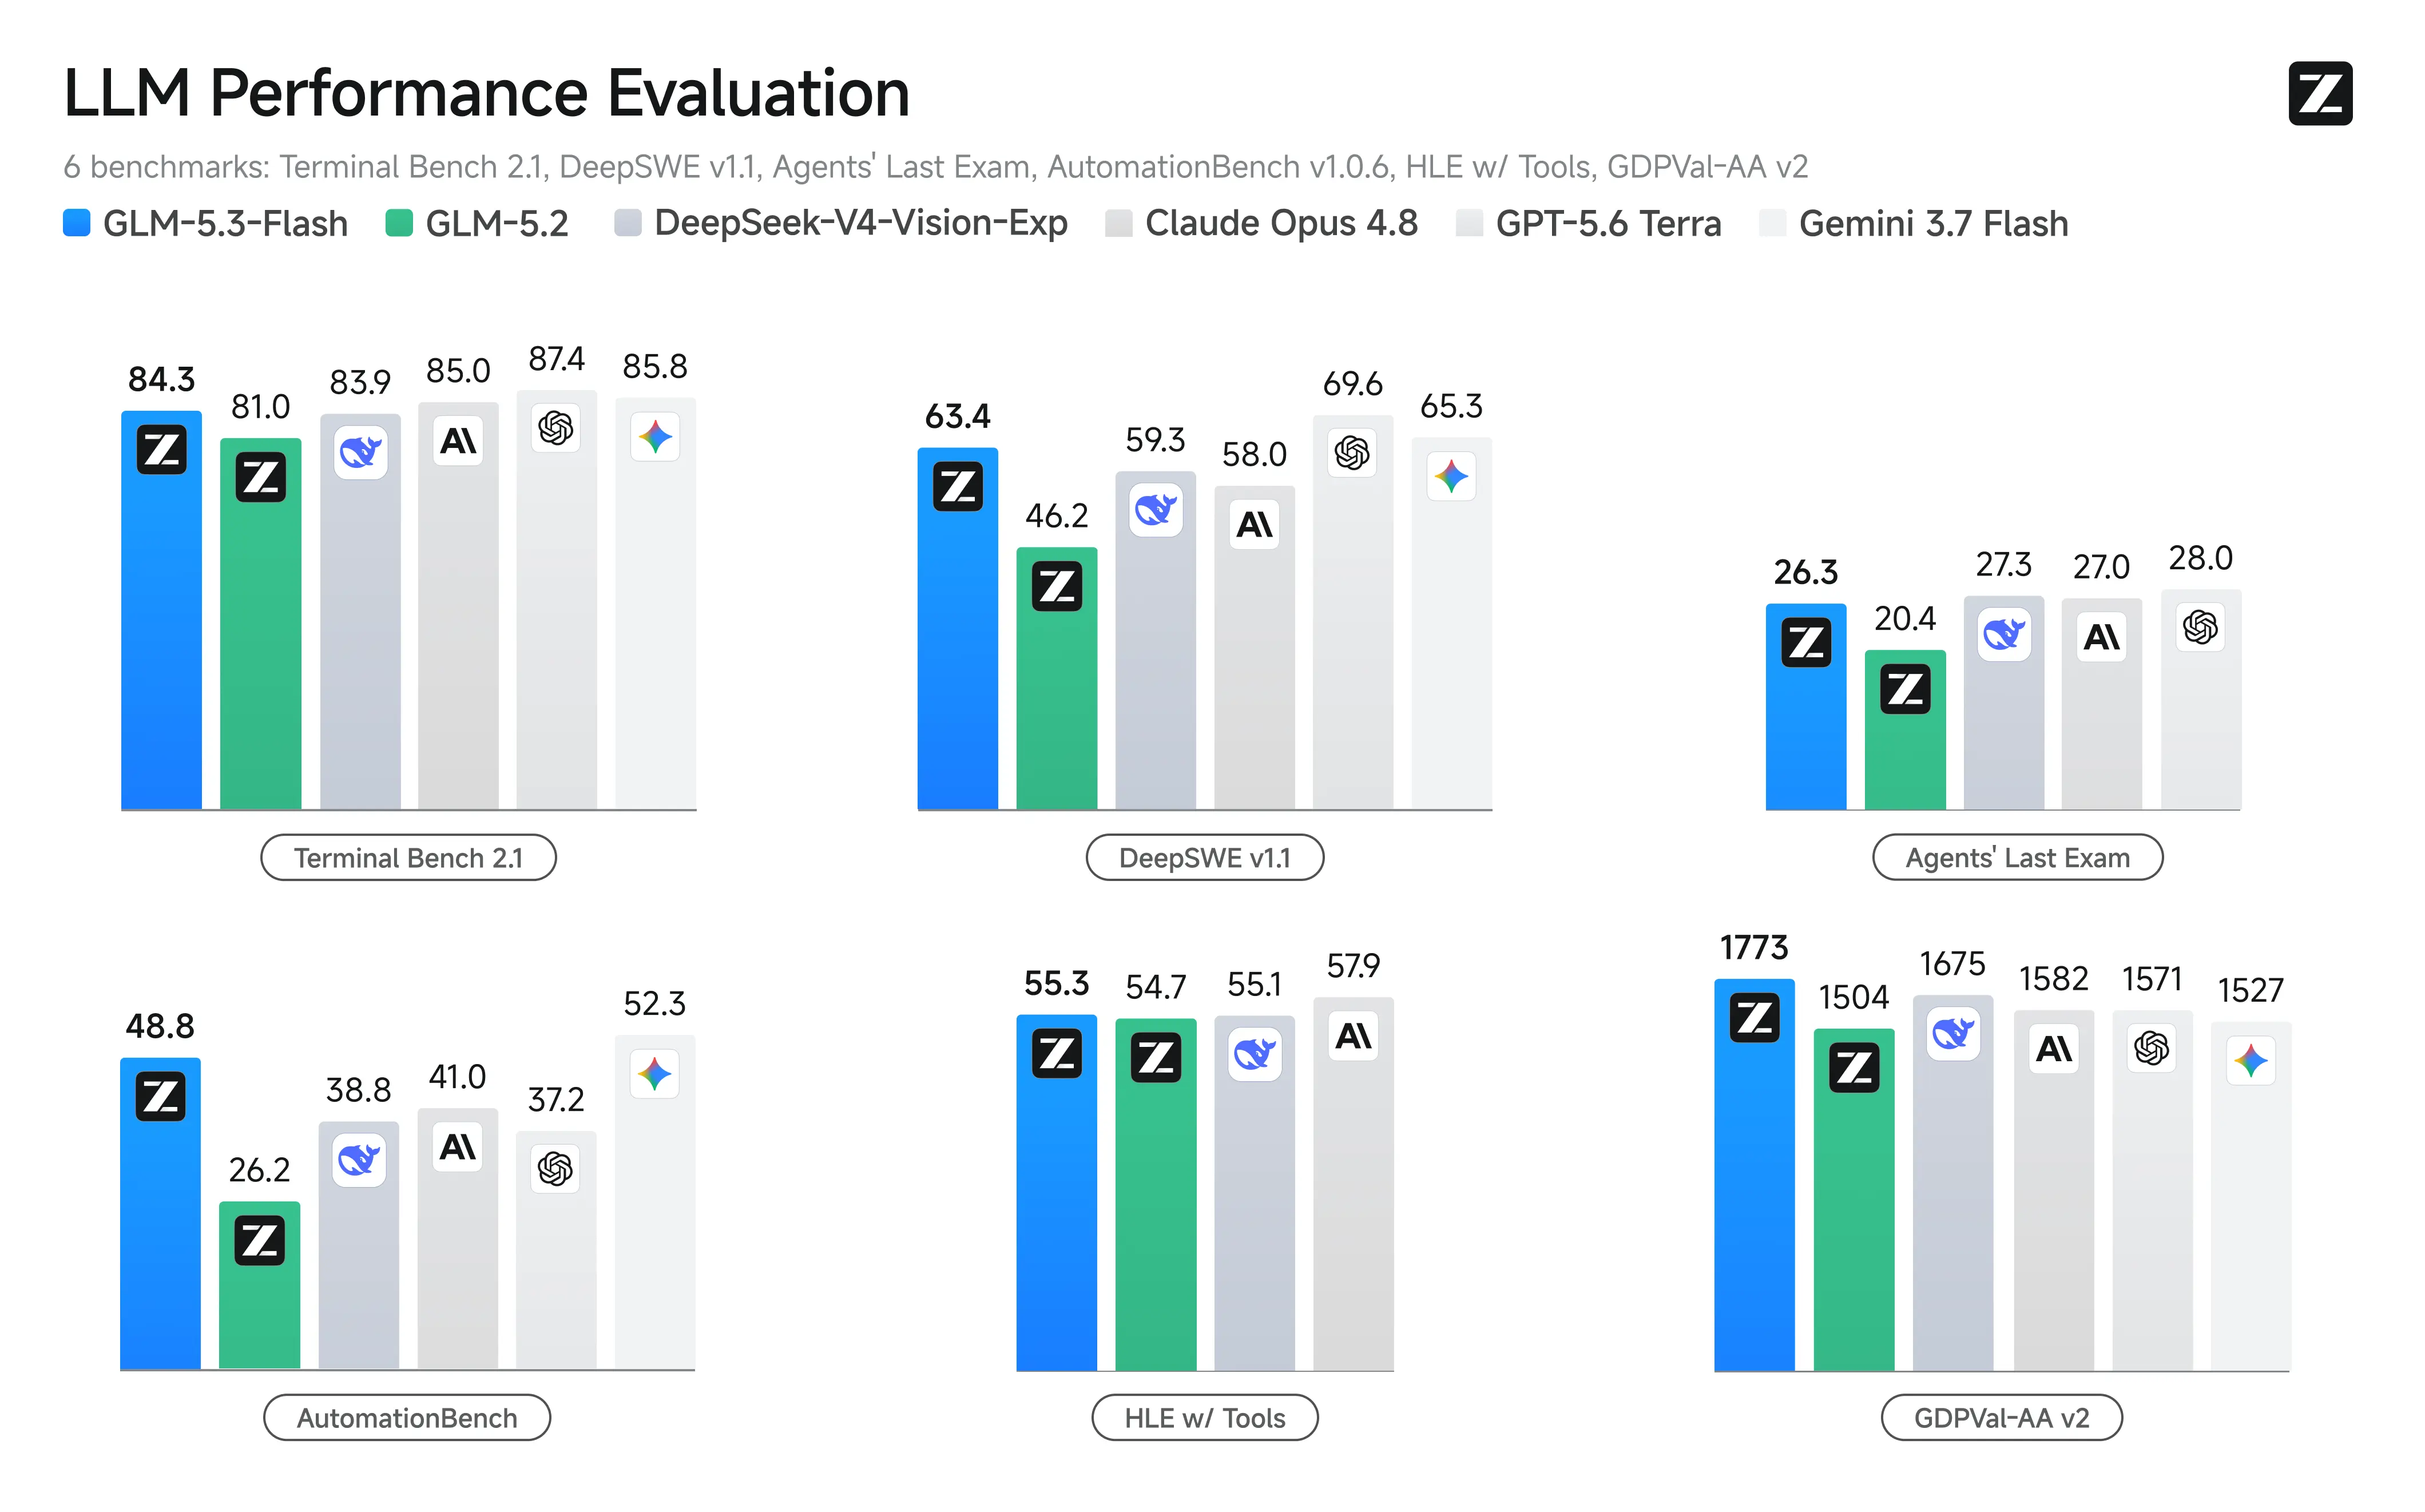
The independent figure is Artificial Analysis, which places GLM-5.3-Flash at 57 on its Intelligence Index v4.1.1. GLM-5.3 scores 60. The median for open-weight models of similar size is 27, so 57 is a strong result for the class even though it sits below its larger sibling.
Z.ai frames the model as approaching Claude Opus 4.8 on coding and agentic work. That is the vendor’s characterization of its own internal evaluations, not a measured third-party result, and the three-point Intelligence Index gap to its own GLM-5.3 suggests some restraint is warranted.
For how the GLM benchmark story developed over previous releases, our GLM-5.2 benchmark breakdown explains what each of these evaluations actually measures.
The Ox Alpha week
On August 20, an anonymous model called ox-alpha appeared on third-party inference platforms with a 1M-token context window and a price of zero. It became one of the most-used models on those platforms within days. The community fingerprinted it to Zhipu inside about 48 hours based on output characteristics.
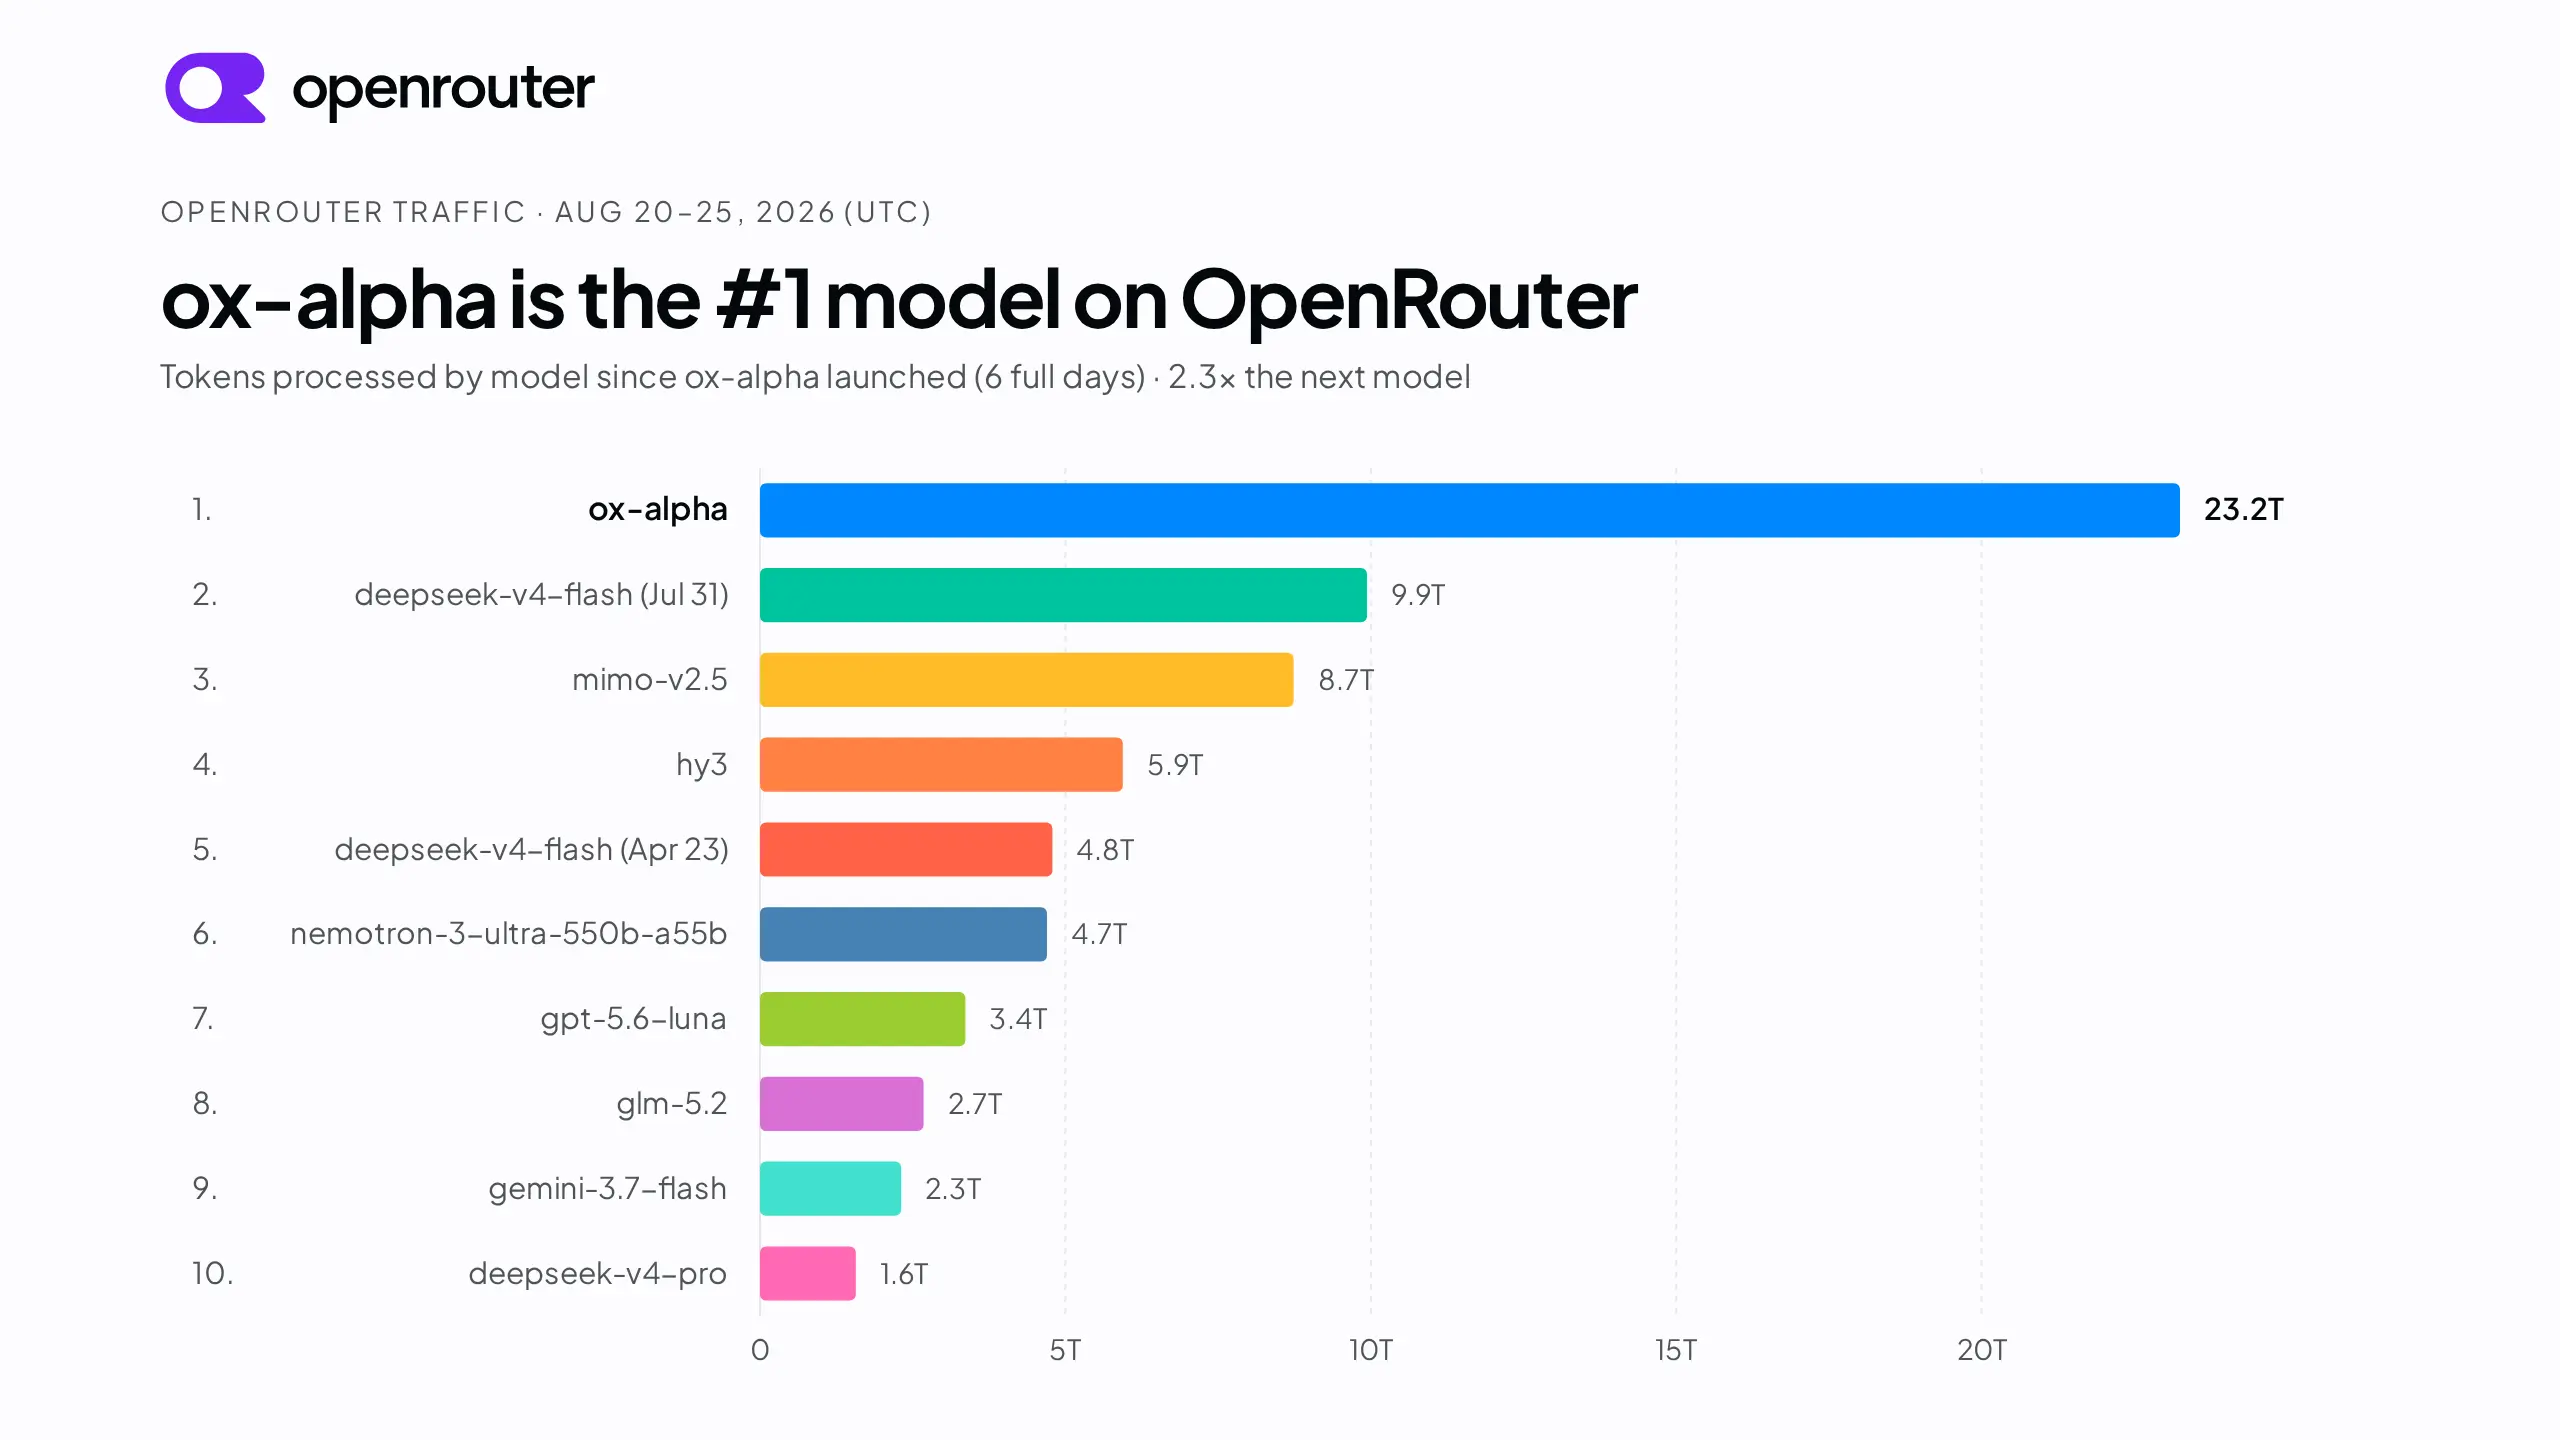
On August 26, Z.ai confirmed it: Ox Alpha was GLM-5.3-Flash, and the free week was a deliberate load test.
Z.ai also says that during that week, all traffic was served on domestic Chinese accelerators using an SGLang-based stack, and claims per-token serving cost comparable to mainstream NVIDIA hardware. That is a vendor claim about its own infrastructure with no independent verification available, so weigh it accordingly.
We have written up this pattern before when Pony Alpha turned out to be a DeepSeek or GLM model. Stealth launches on third-party routers are becoming a standard pre-release step, and the useful takeaway is that an unusually capable anonymous model with a suspiciously round context window is almost always somebody’s unreleased flagship gathering evaluation data.
How to actually use it
Hosted API. The Z.ai endpoint is OpenAI-compatible. Point your existing client at https://api.z.ai/api/paas/v4/ and set the model to glm-5.3-flash. Our GLM-5.3-Flash API guide walks through authentication, the image-input payload, and the reasoning-effort parameter.
Third-party providers. OpenRouter carries it as z-ai/glm-5.3-flash. It is also on Cloudflare Workers AI, Vercel AI Gateway, DeepInfra, Novita, GMICloud, Baseten, and io.net. Prices vary between resellers, sometimes significantly.
Coding agents. Flash is included in the GLM Coding Plan and reportedly carries three times the usable quota of GLM-5.3, which is the practical reason a subscriber would switch. Z.ai’s documentation also notes that off-peak calls consume half the standard points.
Self-hosted. The weights are MIT-licensed and on Hugging Face. vLLM, SGLang, TokenSpeed, and KTransformers all support it, and GGUF quantizations exist for smaller rigs.
Should you use it?
Use GLM-5.3-Flash if you need image or video understanding in the same call as your text, if your cost per token is the constraint you are optimizing, or if you want open weights you can self-host under a permissive license.
Reach for GLM-5.3 instead if you need the last few points of reasoning quality, or if generation throughput matters more to you than price. Our side-by-side comparison of the two works through the decision in detail, and what GLM-5.3 is covers the base model on its own terms.
Whichever you pick, the swap is a one-line model id change on an OpenAI-compatible endpoint, which makes it easy to test both against your own workload rather than trusting anyone’s benchmark table. That is the right way to settle it.
Testing a model swap properly means sending real requests and checking real responses, including the multimodal ones that are awkward to hand-roll in curl. Apidog lets you save those calls as a reusable collection with assertions attached, so when you move from GLM-5.3 to Flash you can confirm the response shape did not change instead of finding out in production.
FAQ
Is GLM-5.3-Flash free? Not anymore. The free Ox Alpha week ended when the model was officially announced. There is a 50% launch discount running through September 9, 2026, after which list pricing applies.
Is it faster than GLM-5.3? No. It generates roughly 49 tokens per second against GLM-5.3’s 86. It does start responding sooner, at 1.52 seconds to first token.
Can it really handle a million tokens of context? The configured window is 1,048,576 tokens, confirmed in the model config and by Artificial Analysis. Note that OpenRouter lists a larger figure of 1,310,720; treat that as a provider-side listing rather than a model spec.
Does it accept video? Z.ai’s documentation lists text, image, video, and file input. Video support is newer and less widely exercised than image input, so validate it against your own media before depending on it.
What license are the weights under? MIT, with the weights published at zai-org/GLM-5.3-Flash on Hugging Face.