Claude Haiku 5.5 (claude-haiku-5-5, released October 7, 2026) costs 90% less than Haiku 4.5 for prompts up to 100K tokens ($0.10/$0.50 per million input/output tokens vs $1/$5), has a 1M-token context window instead of 200K, and scores far higher on every launch benchmark that lists both. The catch: five request shapes that worked on 4.5 now return a 400, and several more changes alter responses and costs with no error.
Below: a side-by-side table, each breaking change with before/after JSON, the silent changes, and a test plan for Apidog. For the full spec sheet, read what is Claude Haiku 5.5. If you’re still running the older model, our Claude Haiku 4.5 API guide covers it.
Haiku 4.5 vs Haiku 5.5 at a glance
| Claude Haiku 4.5 | Claude Haiku 5.5 | |
|---|---|---|
| Model ID (Claude API) | claude-haiku-4-5-20251001 |
claude-haiku-5-5 |
| Context / max output | 200K / 64K | 1M / 128K |
| Input / output per MTok | $1 / $5 | $0.10 / $0.50 for prompts up to 100K tokens; $0.50 / $2.50 over |
| Cache read / 5m write per MTok | $0.10 / $1.25 | $0.01 / $0.125 up to 100K; $0.05 / $0.625 over |
| Batch input / output per MTok | $0.50 / $2.50 | $0.05 / $0.25 up to 100K; $0.25 / $1.25 over |
| Thinking | Manual budget_tokens |
Adaptive only, on by default |
| Effort levels | None | low, medium (default), high, xhigh, max |
| Minimum cacheable prompt | 4,096 tokens | 512 tokens |
| Tokenizer | Older | About 30% more tokens for the same text |
| Non-default sampling params, prefill | Accepted | 400 error |
| Priority Tier | Supported | Not supported |
| Status | Active, retirement not sooner than Oct 15, 2026 | Active, retirement not sooner than Oct 7, 2027 |
Haiku 4.5 is not deprecated. The model deprecations page lists it as Active with no deprecation date, so you can migrate on your own schedule. Rate limits are the same on both.
The five breaking changes
Each returns a 400 on Haiku 5.5 for a body that works on 4.5. The Haiku 5.5 migration guide lists them all.
1. Manual thinking with budget_tokens
Haiku 5.5 only runs adaptive thinking. A fixed budget is rejected.
// Before (Haiku 4.5)
{
  "model": "claude-haiku-4-5-20251001",
  "max_tokens": 16000,
  "thinking": { "type": "enabled", "budget_tokens": 8000 },
  "messages": [{ "role": "user", "content": "Classify this ticket." }]
}

// After (Haiku 5.5)
{
  "model": "claude-haiku-5-5",
  "max_tokens": 16000,
  "thinking": { "type": "adaptive" },
  "output_config": { "effort": "medium" },
  "messages": [{ "role": "user", "content": "Classify this ticket." }]
}
Effort is now the lever: where 4.5 used a small budget, pick a lower effort. You can still send thinking: {"type": "disabled"}, but only at high effort or below; at xhigh or max that’s a 400 too.
2. Sampling parameters
Remove temperature, top_p and top_k. The only accepted values are temperature: 1 and top_p: 0.99. Any other value is a 400, including top_p: 1, any top_k, and sending temperature and top_p together.
// Before (Haiku 4.5)
{ "model": "claude-haiku-4-5-20251001", "max_tokens": 1024,
  "temperature": 0.2, "top_k": 40,
  "messages": [{ "role": "user", "content": "Extract the order ID." }] }

// After (Haiku 5.5)
{ "model": "claude-haiku-5-5", "max_tokens": 1024,
  "messages": [{ "role": "user", "content": "Extract the order ID." }] }
If you used a low temperature for consistent output, move that intent into the prompt.
3. Assistant prefill
A final assistant turn for the model to continue is rejected, even with thinking off. End messages with a user turn.
// Before (Haiku 4.5)
{ "model": "claude-haiku-4-5-20251001", "max_tokens": 1024,
  "messages": [
    { "role": "user", "content": "Return the sentiment as JSON." },
    { "role": "assistant", "content": "{\"sentiment\": \"" }
  ] }

// After (Haiku 5.5)
{ "model": "claude-haiku-5-5", "max_tokens": 1024,
  "system": "Reply with only a JSON object. No preamble.",
  "messages": [
    { "role": "user", "content": "Return the sentiment as JSON." }
  ] }
For strict formats, the migration guide points to structured outputs, or a tool with enum fields for classification.
4. Computer use: computer_20250124 to computer_toolset_20260801
On the Claude API and Google Cloud, Haiku 5.5 supports computer use only through the new toolset. Drop the computer-use-2025-01-24 beta header, and drop fine-grained-tool-streaming-2025-05-14 if you send it, because it’s a 400 alongside a toolset.
// Before (Haiku 4.5, header anthropic-beta: computer-use-2025-01-24)
{ "model": "claude-haiku-4-5-20251001", "max_tokens": 4096,
  "tools": [{ "type": "computer_20250124", "name": "computer",
              "display_width_px": 1280, "display_height_px": 800 }],
  "messages": [{ "role": "user", "content": "Open the settings page." }] }

// After (Haiku 5.5, no beta header)
{ "model": "claude-haiku-5-5", "max_tokens": 4096,
  "tools": [{ "type": "computer_toolset_20260801" }],
  "messages": [{ "role": "user", "content": "Open the settings page." }] }
Your agent loop changes too: dispatch on each tool_use block’s name and toolset_name instead of input.action, and echo toolset_name on results. Haiku 5.5 also gets the browser use tool (browser_toolset_20260801), which Haiku 4.5 doesn’t support. See Claude Code computer use for the wider picture.
5. Editing earlier turns before a thinking block
A Haiku 5.5 thinking block stays valid only while everything sent before it is unchanged. Change system, tools or an earlier message and send the block back, and you get a 400. Haiku 4.5 never ran this check. Here, turn 1 sent "system": "You are a billing agent." and turn 2 edits it.
// Before: edited system + replayed thinking block = 400
{ "model": "claude-haiku-5-5", "max_tokens": 4096,
  "system": "You are a billing agent. Be brief.",
  "messages": [
    { "role": "user", "content": "Why was I charged twice?" },
    { "role": "assistant", "content": [
      { "type": "thinking", "thinking": "", "signature": "<from turn 1>" },
      { "type": "text", "text": "Checking." } ] },
    { "role": "user", "content": "Order 4412." }
  ] }

// After: earlier turns unchanged, new instruction appended
{ "model": "claude-haiku-5-5", "max_tokens": 4096,
  "system": "You are a billing agent.",
  "messages": [
    { "role": "user", "content": "Why was I charged twice?" },
    { "role": "assistant", "content": [
      { "type": "thinking", "thinking": "", "signature": "<from turn 1>" },
      { "type": "text", "text": "Checking." } ] },
    { "role": "user", "content": "Order 4412. Be brief." }
  ] }
On accounts created before August 31, 2026, 00:00 UTC, the error appears only on requests that set thinking.block_binding.prefix_mismatch_behavior.
Silent changes that won’t throw an error
- Empty thinking field by default. Each
thinkingblock comes back with an emptythinkingfield and only asignature. Haiku 4.5 returned summarized thinking. Setthinking: {"type": "adaptive", "display": "summarized"}if you log or show it. - Responses can start with thinking. Adaptive thinking is on even when you don’t set it, so select content blocks by
type, not by index. - About 30% more tokens. The new tokenizer counts the same text as roughly 30% more tokens. Recount prompts, and remember thinking tokens count toward
max_tokens, so a small limit can stop withstop_reason: "max_tokens"before any text. - Forced
tool_choiceskips thinking.anyor a named tool still works, but the response opens with the tool call and nothinkingblock. Usetool_choice: {"type": "auto"}and tell the model when to call the tool if you want it to reason first. - New refusals, no fallback. Haiku 5.5 runs safety classifiers (
cyber,frontier_llm,bio,general_harms) that can returnstop_reason: "refusal". There’s no server-side fallback, and a retry usually refuses again. - Priority Tier is gone. If you have a Priority Tier commitment on Haiku 4.5, plan capacity separately.
- Thinking blocks are account-bound. They work only in the account that produced them or a linked one. Replaying stored conversations through another account loses that reasoning.
- Cheaper caching starts sooner. The minimum cacheable prompt drops from 4,096 to 512 tokens, so short system prompts that never cached on 4.5 now do.
What got better
These are Anthropic-reported numbers with Haiku 5.5 at max effort; Artificial Analysis ran GDPval-AA and AA-Briefcase independently.
| Benchmark | Haiku 4.5 | Haiku 5.5 |
|---|---|---|
| GDPval-AA v2.1 (Elo) | 735 | 1620 |
| AA-Briefcase v1.1 (Elo) | 614 | 1578 |
| OSWorld 2.1, offline subset | 15.7% | 72.4% |
| Humanity’s Last Exam, with tools | 18.7% | 57.4% |
| Terminal-Bench 4.0 | 0.0% | 39.2% |
| SWE-bench Multilingual | 67.4% | 83.7% |
| Chartography, no tools | 6.4% | 46.4% |
Haiku 4.5’s Terminal-Bench run used a fixed 63,999-token thinking budget. At the default medium effort, Haiku 5.5 scored 1277 on GDPval-AA, still well above 4.5. Box reported scores 11 points higher than Haiku 4.5 at about half the latency. Full tables are in Claude Haiku 5.5 benchmarks.
Anthropic still positions Sonnet 5.5 and Opus 5.5 as better choices for complex agentic coding. Haiku 5.5 targets classification, extraction, summarization, compaction, subagents and browser use.
On cost, Anthropic says Haiku 5.5 runs around 75% cheaper on average. That figure blends 90% lower prices up to 100K tokens and 50% lower above, and it already nets out the extra tokens from the new tokenizer. The tool-use system prompt also shrank, from 496 to 286 tokens with auto tool choice. Worked examples are in Claude Haiku 5.5 pricing.
Test the migration in Apidog
In Apidog, create one project with three saved requests to https://api.anthropic.com/v1/messages:
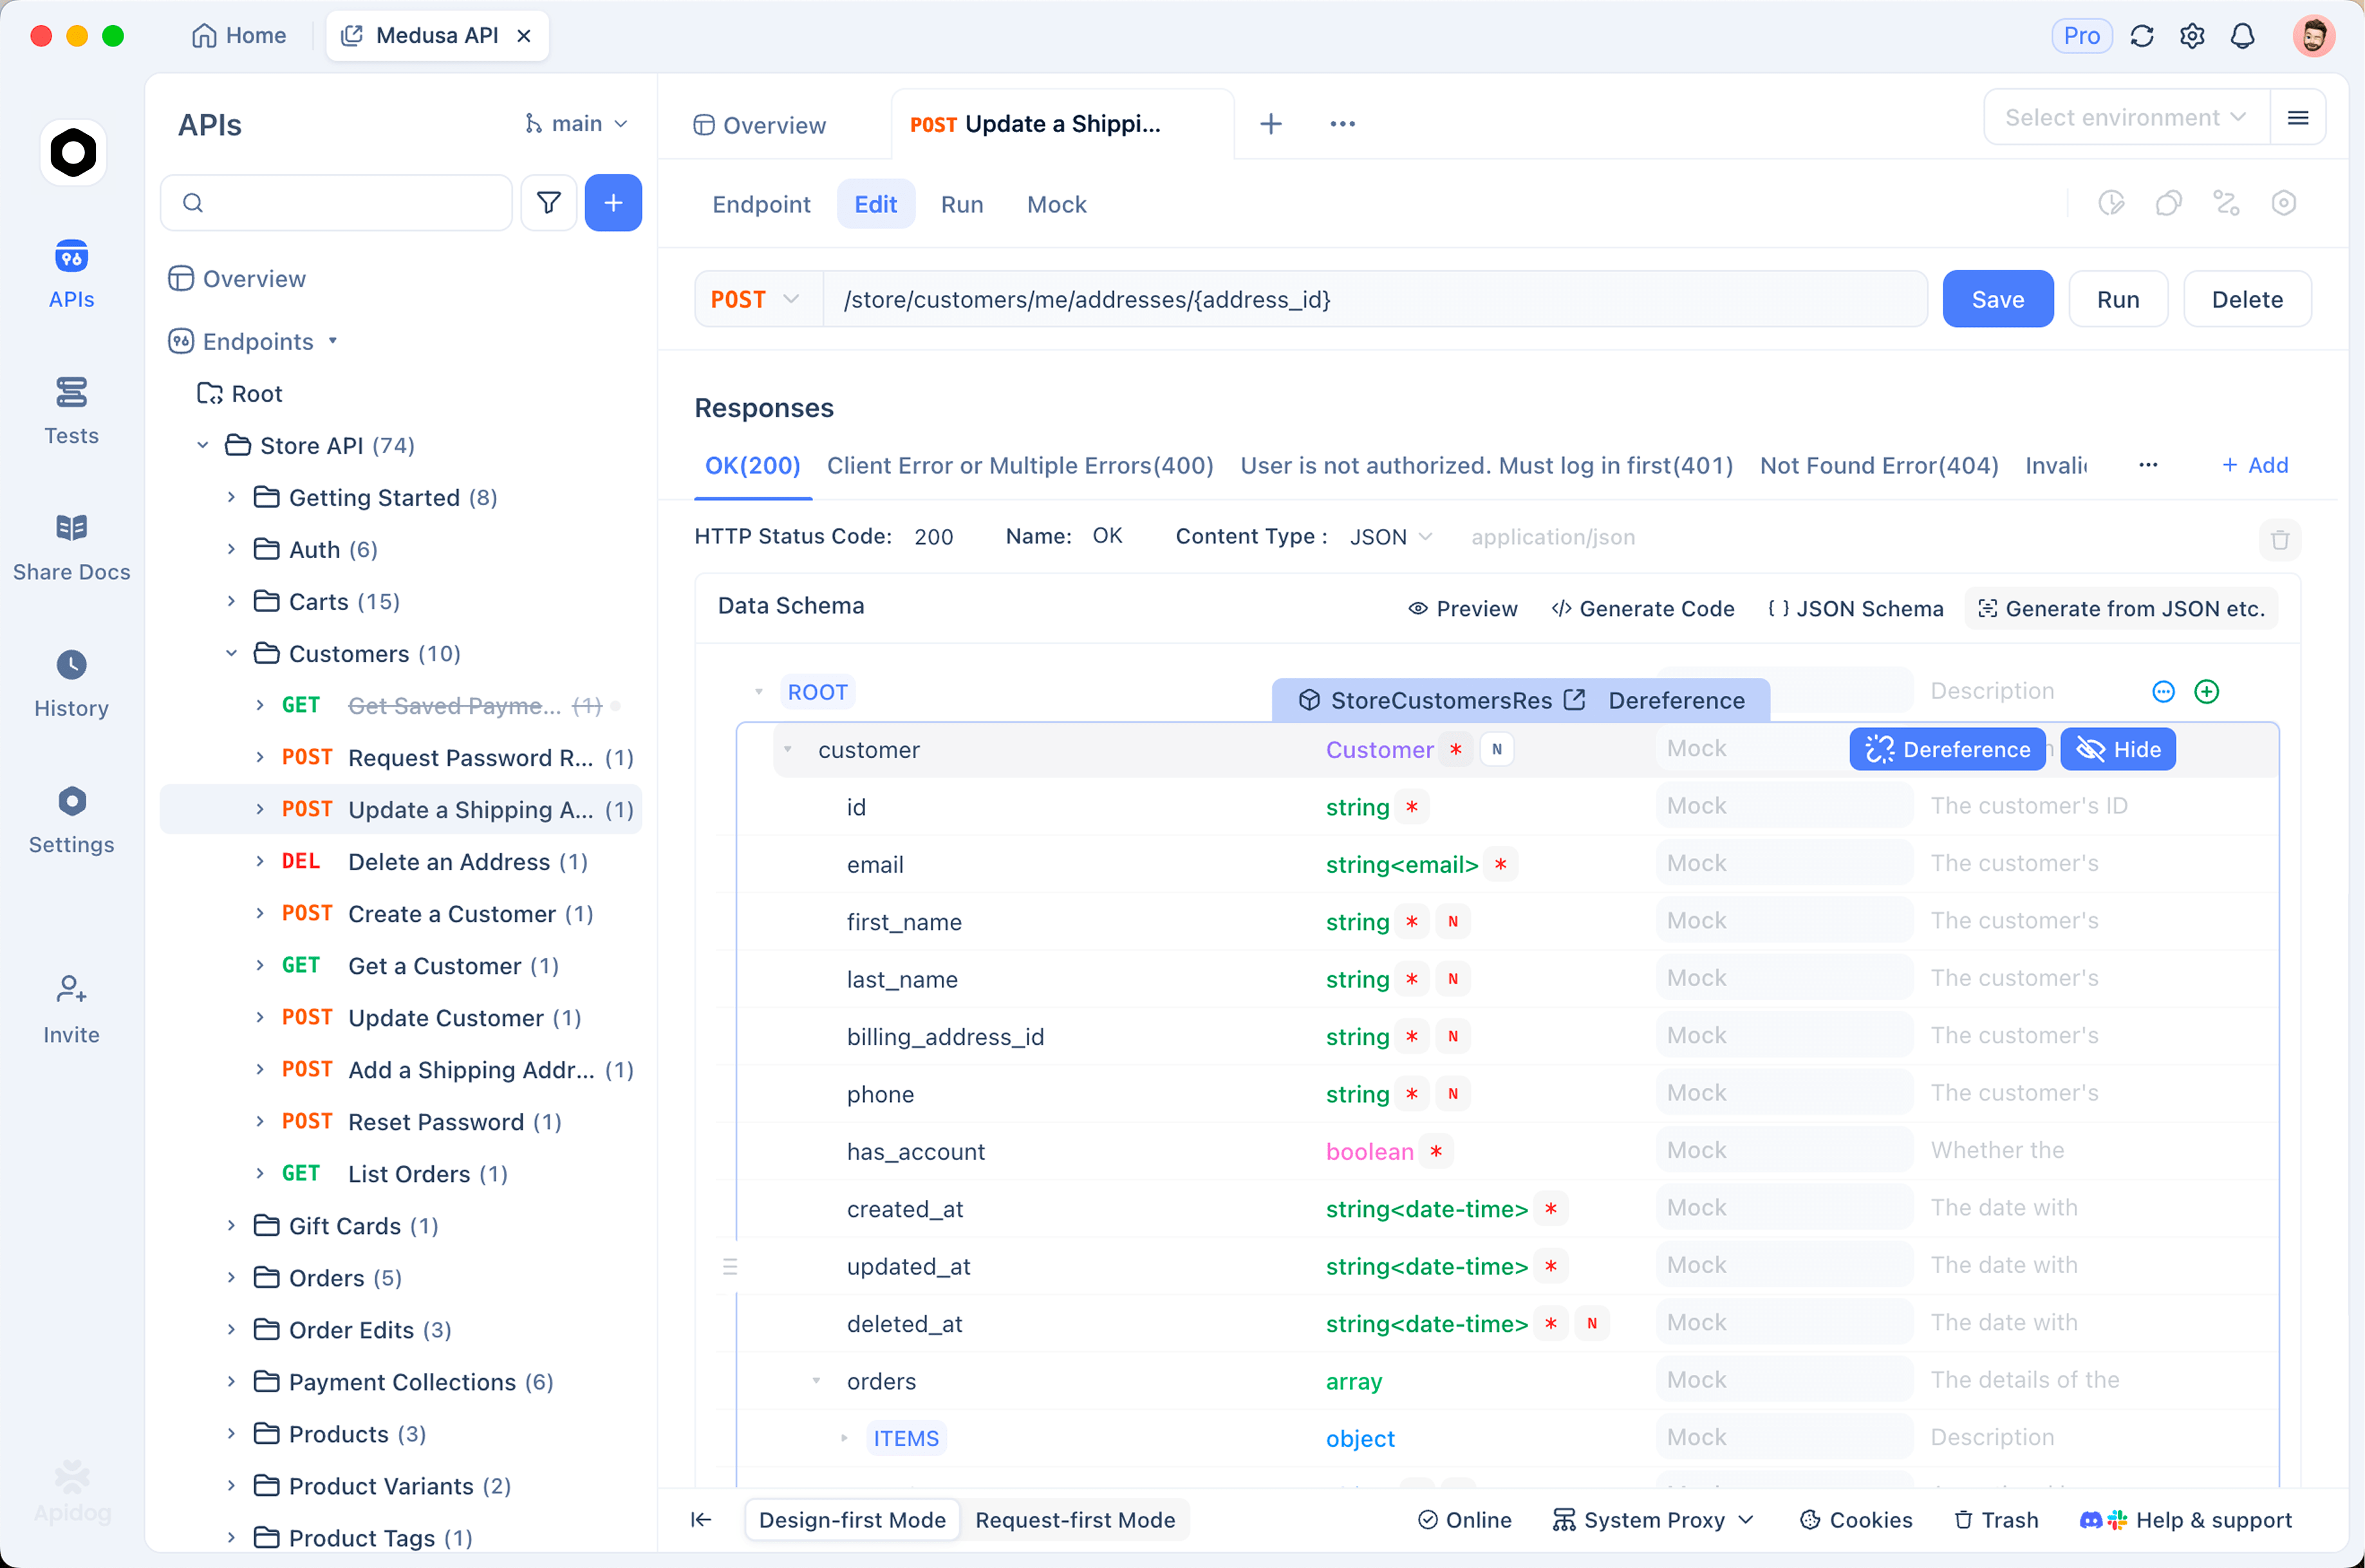
- Baseline: your current Haiku 4.5 body. Assert status 200.
- Old body, new model: change only
modeltoclaude-haiku-5-5. Assert status 400. Keep one copy per breaking change you hit. - Migrated: the fixed body. Assert status 200, a
stop_reasonthat isn’trefusalormax_tokens, and a text block found bytype.
Store ANTHROPIC_API_KEY as an environment variable and reference it as {{ANTHROPIC_API_KEY}} in the x-api-key header, with anthropic-version: 2023-06-01. Compare usage.input_tokens between the baseline and migrated requests to see the tokenizer change on your own prompts. Save the set as a test scenario, and a teammate who reintroduces temperature fails the run instead of production. Request basics are in how to use the Claude Haiku 5.5 API.
If you work in Claude Code, /claude-api migrate this project to claude-haiku-5-5 applies the model ID swap and parameter fixes, then gives you a checklist. Note that the haiku alias resolves to Haiku 5.5 only on the Anthropic API; see Claude Haiku 5.5 in Claude Code.
FAQ
Is Claude Haiku 4.5 deprecated? No. It’s listed as Active with no deprecation date, and its retirement is not sooner than October 15, 2026.
Why does my Haiku 4.5 request return a 400 on Haiku 5.5? Check for budget_tokens, temperature/top_p/top_k, an assistant prefill, computer_20250124, or edits to earlier turns before a thinking block. Those are the five breaking changes.
Is Haiku 5.5 cheaper than Haiku 4.5 for long prompts? Yes. Over 100K tokens it costs $0.50/$2.50 per million, half of Haiku 4.5’s $1/$5. Haiku 4.5 can’t take prompts beyond 200K at all.
Should I switch everything to Haiku 5.5? For classification, extraction and subagent work, test it first, then move. Compare it against its closest rival in Haiku 5.5 vs GPT-6 Luna.
Next step
Save your Haiku 4.5 request next to its Haiku 5.5 twin, confirm the 400, fix it, and move traffic once the migrated request passes. Download Apidog to build that test pair.