ERNIE 5.5 Flash vs DeepSeek V4.1 Flash vs GPT-6 Luna comes down to three different bargains. ERNIE 5.5 Flash Preview is free to call today on OpenRouter. DeepSeek V4.1 Flash gives you open MIT weights and $0.30/$1.20 per 1M tokens at peak, half that off-peak. GPT-6 Luna has the lowest paid list price: $0.10 in, $0.50 out.
All three take about 1M tokens of context and call tools. They differ on price structure, weights and maturity. Every price below was read on the official pages on November 12, 2026, and the last section shows your coding agent testing all three with one prompt.
ERNIE 5.5 Flash vs DeepSeek V4.1 Flash vs GPT-6 Luna at a glance
| ERNIE 5.5 Flash Preview | DeepSeek V4.1 Flash | GPT-6 Luna | |
|---|---|---|---|
| API model ID | baidu/ernie-5.5-flash-preview:free (OpenRouter) |
deepseek-flash |
gpt-6-luna |
| Input per 1M | Free on OpenRouter; paid price [VERIFY] | $0.30 peak, $0.15 off-peak | $0.10 |
| Cached input per 1M | n/a on free endpoint | $0.006 peak, $0.003 off-peak | $0.01 |
| Output per 1M | Free on OpenRouter; paid price [VERIFY] | $1.20 peak, $0.60 off-peak | $0.50 |
| Context window | 1,024,000 tokens | 1M tokens | 1,050,000 tokens |
| Max output | 1,024,000 (OpenRouter listing) | 384K | 128,000 |
| Parameters | 280B total, 14B active (MoE) | 552B backbone, 8B active prefill / 16B decode | Not published |
| Input types | Text | Text, image | Text, image |
| Open weights | Base model yes; Preview “soon” under Apache 2.0 | Yes, MIT | No |
| Status | Preview checkpoint | Production (version 1017) | Production |
Sources: Baidu’s release post, OpenRouter, DeepSeek pricing and OpenAI’s Luna page.
What each cheap model is
ERNIE 5.5 Flash Preview is Baidu’s first post-trained model on top of the ERNIE 5.5 Flash Base it released on Hugging Face earlier in November. It’s a 280B sparse mixture-of-experts model with 14B active parameters and a 1M-token context. Baidu calls it an intermediate checkpoint: post-training isn’t finished. Background: what ERNIE 5.5 Flash is and the earlier ERNIE 5.1.
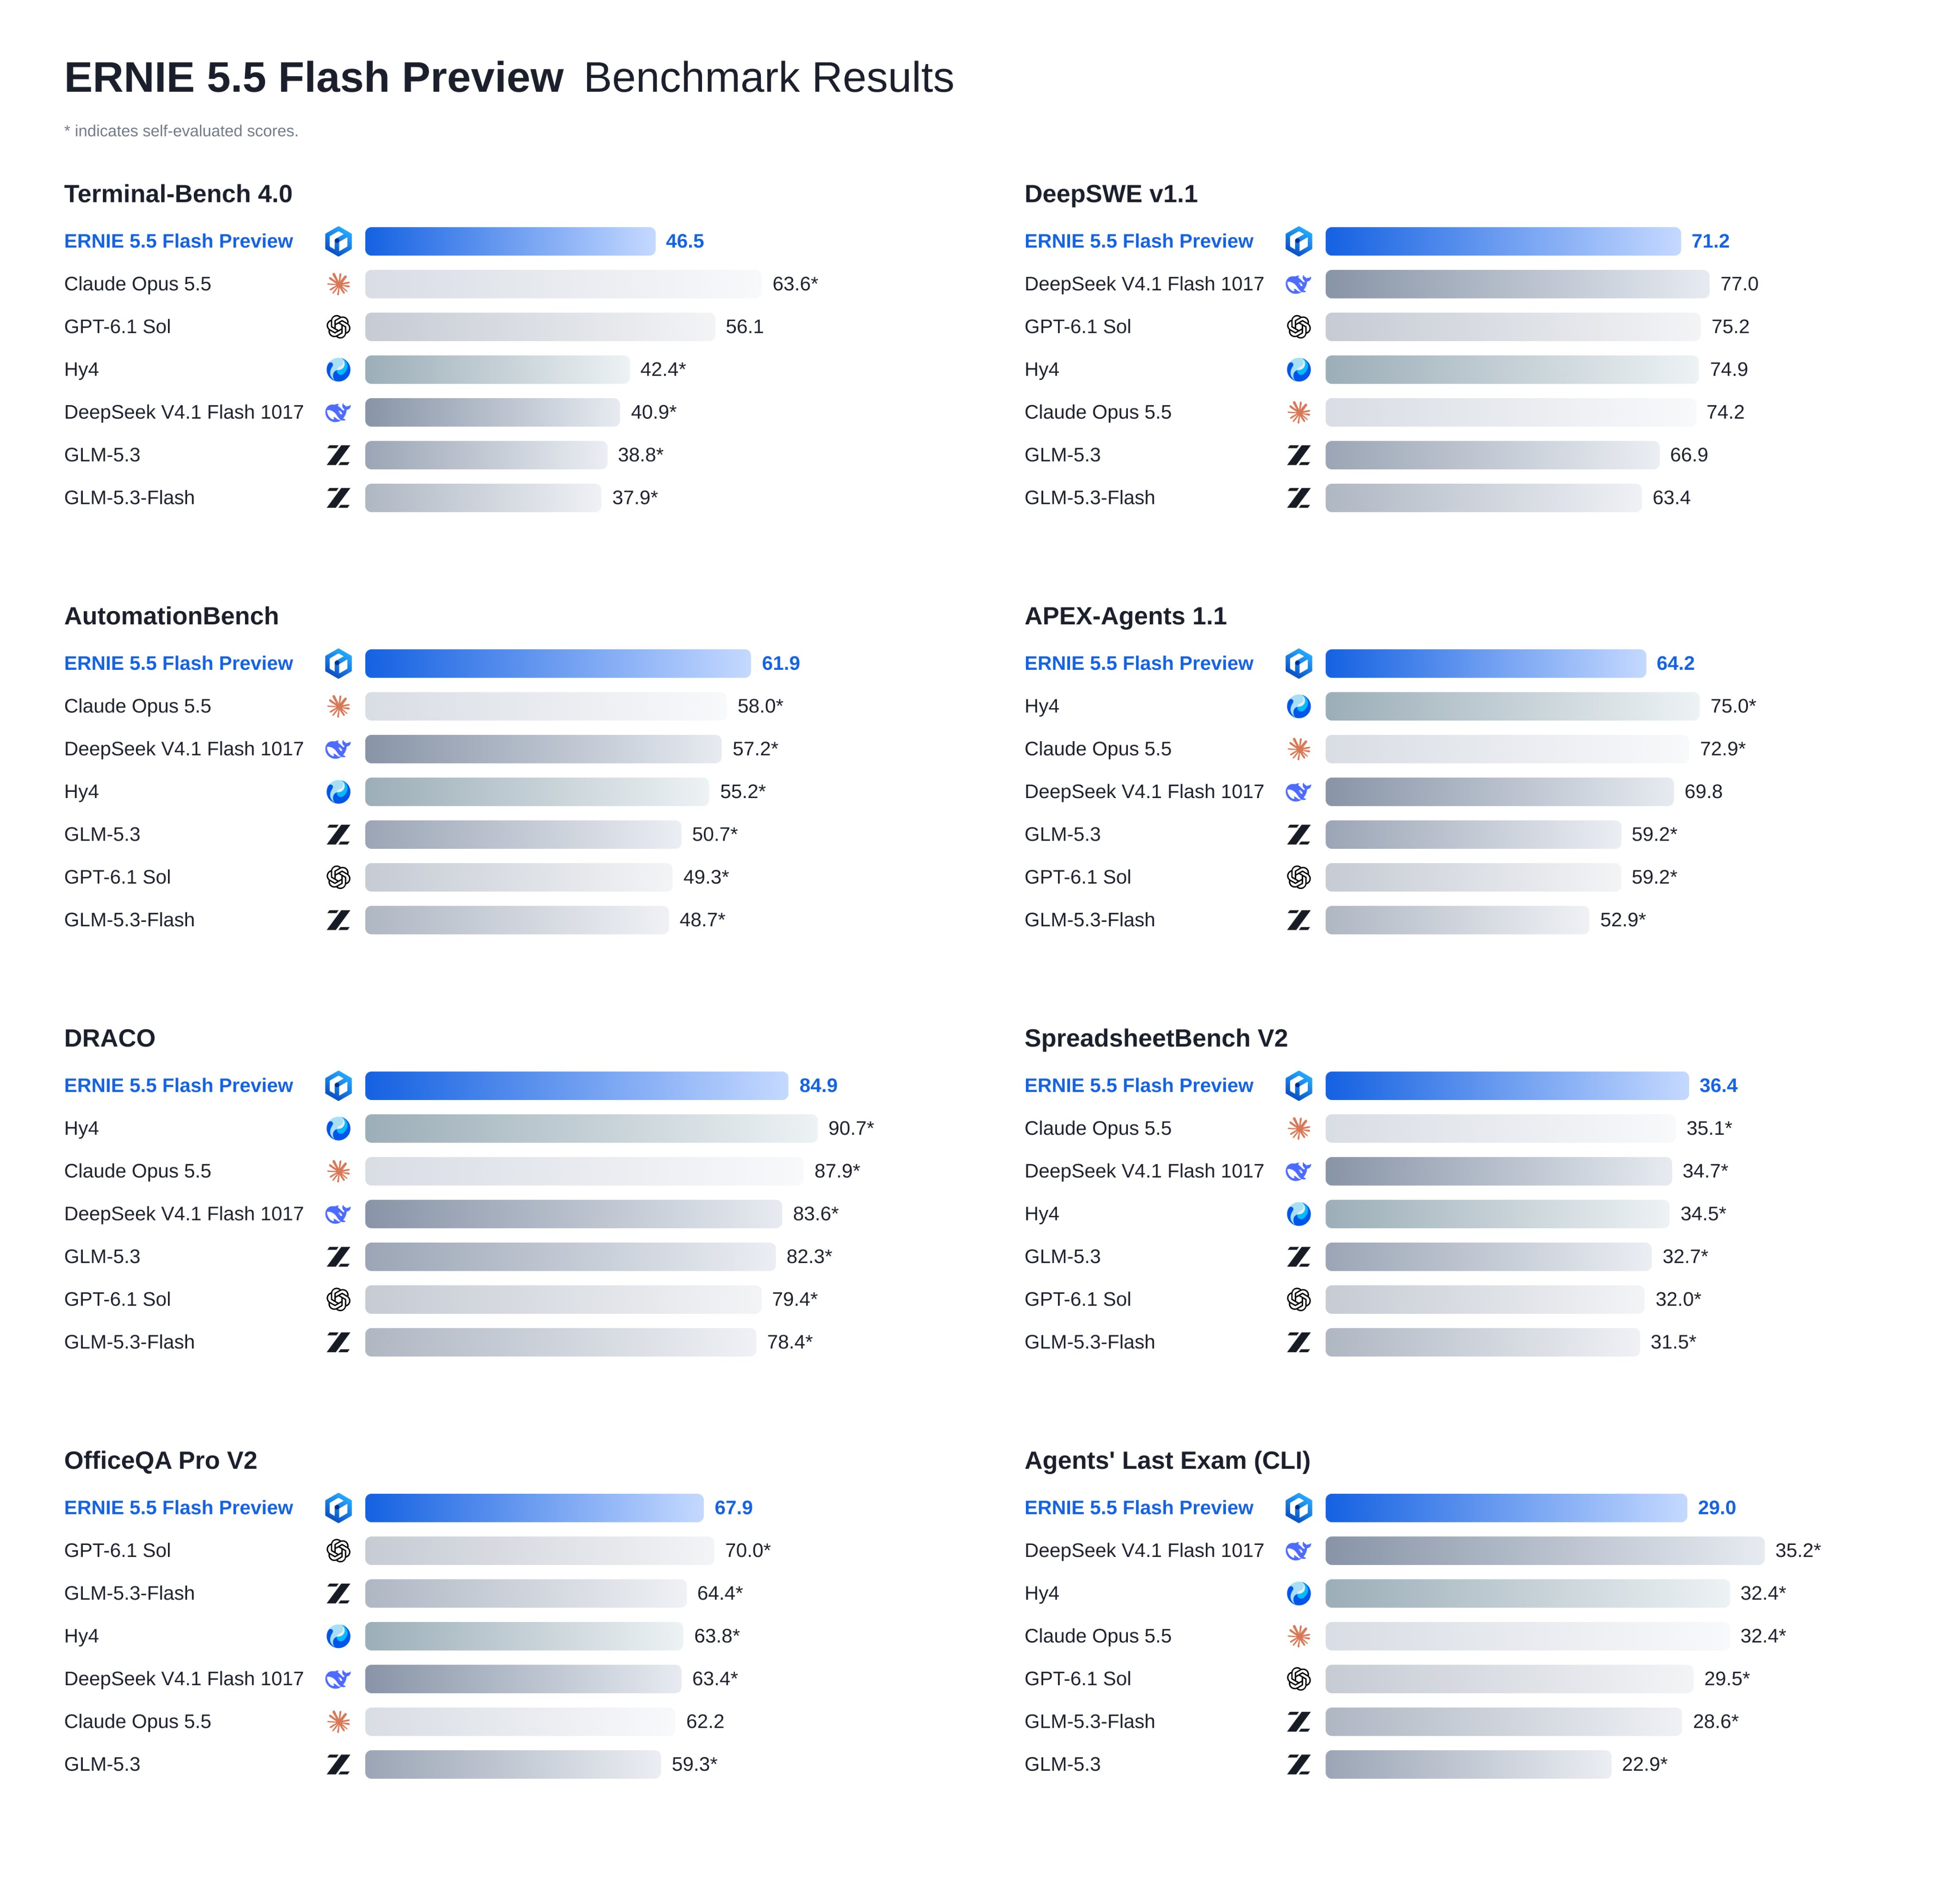
DeepSeek V4.1 Flash is a multimodal MoE with 552B backbone parameters. It activates 8B parameters per token during prefill and 16B during decode, which keeps input-heavy agent work cheap. Weights are MIT on Hugging Face. See the DeepSeek V4.1 Flash explainer.
GPT-6 Luna is OpenAI’s “most efficient model for focused, high-volume tasks.” It takes text and images, supports reasoning effort from none to max, and works with the Responses API tools. See what GPT-6 Luna is.
Price per 1M tokens, and what a real agent call costs
Agent loops resend the same long context every step, so caching and time-of-day rules matter as much as the headline rate.
- GPT-6 Luna: $0.10 input, $0.01 cached input, $0.125 cache writes, $0.50 output. Prompts over 272K input tokens cost 2x input and 1.5x output for the whole request. Batch and Flex run at 50% of standard.
- DeepSeek V4.1 Flash: $0.30 input (cache miss), $0.006 cache hit, $1.20 output during peak hours. Off-peak rates are half. Peak is 01:00 to 04:00 and 06:00 to 10:00 UTC, Monday through Friday; everything else, weekends included, is off-peak.
- ERNIE 5.5 Flash Preview: $0 input and output on the OpenRouter
:freeendpoint, which OpenRouter says is rate limited. Baidu hasn’t published a paid per-token price on a page we could read today, so treat any number you see elsewhere as [VERIFY].
Take one agent step with 50,000 input tokens and 2,000 output tokens, no cache:
| Model | Cost per call | Cost per 1,000 calls |
|---|---|---|
| GPT-6 Luna | $0.0060 | $6.00 |
| DeepSeek V4.1 Flash, peak | $0.0174 | $17.40 |
| DeepSeek V4.1 Flash, off-peak | $0.0087 | $8.70 |
ERNIE 5.5 Flash Preview, :free |
$0 | $0 (within rate limits) |
Now assume 90% of that input is a cache hit, which is normal for an agent rereading the same repo. Luna drops to about $0.0020 per call (plus a one-time cache write). DeepSeek drops to about $0.0042 at peak and $0.0021 off-peak. The gap between the two paid models nearly closes off-peak.
Two caveats: each provider has its own tokenizer, so token counts differ for the same prompt, and reasoning tokens bill as output, so high reasoning effort inflates the output line. Our DeepSeek V4.1 Flash pricing breakdown and the sub-$1 API tier comparison go deeper on cache math.
Context window, output length and speed
Context won’t decide this. Output limits differ more: 384K for DeepSeek, 128,000 for Luna, and 1,024,000 listed for the ERNIE free endpoint. Speed claims need care:
- ERNIE 5.5 Flash Preview: OpenRouter’s model description says more than 200 tokens per second. OpenRouter’s own measured P50 throughput over the last 3 days was 79 tokens per second, with a P50 latency of 2.53 seconds, on a single provider (Baidu Qianfan).
- DeepSeek V4.1 Flash: no tokens-per-second figure on the pricing page; it lists a concurrency limit of 2,500.
- GPT-6 Luna: OpenAI rates it “Fast”, with Build-tier limits of 5,000 requests and 2,000,000 tokens per minute.
Measure from your own region with your own prompts; the Apidog section below sets that up.
Open weights, free access and licensing
- DeepSeek V4.1 Flash is the only one with production weights you can download today, under the MIT license. Self-host it or pick a hosted provider from its Hugging Face card.
- ERNIE 5.5 Flash has two artifacts. The Base model (pretraining only, 33.5T tokens) is already on Hugging Face. The Preview, the chat and agent model, has no public weights yet; Baidu says they’ll be open-sourced under Apache 2.0 “soon.” A date you may see online is unconfirmed [VERIFY].
- GPT-6 Luna is closed. You reach it through OpenAI’s API or Amazon Bedrock, and the API free tier is listed as “Not supported.”
For $0 testing, ERNIE’s :free endpoint is the easiest door. DeepSeek and Luna have their own free routes, covered in how to use DeepSeek V4.1 Flash for free and how to use GPT-6 Luna for free.
Best fit for agents and coding
Each vendor benchmarks in its own harness, so don’t line those numbers up as one test. Compare what each emphasizes.
DeepSeek V4.1 Flash reports 90.6 on Terminal-Bench 2.1 and 74.2 on DeepSWE v1.1 at maximum reasoning effort, both measured by DeepSeek in its own harness. Reasoning effort is a 1 to 100 dial, and the endpoint speaks OpenAI, Anthropic and Responses formats, so it drops into Claude Code, Codex or OpenCode.
ERNIE 5.5 Flash Preview is shown on Baidu’s release page building an Unreal Engine 5.8 game in a single 11-hour coding task and nearly 100 mobile mini-games from design docs. It’s text-only, so screenshot-driven agent loops are out for now. OpenRouter’s dashboard also showed a 21.70% structured-output error rate and a 1.01% tool-call error rate over 3 days, so validate JSON outputs before you trust them in a pipeline.
GPT-6 Luna wins on tooling breadth. The Responses API gives it hosted shell, apply patch, computer use and MCP. One limit: in Chat Completions, function calling only works with reasoning_effort set to none; use the Responses API for tools with reasoning on.
Which cheap model should you pick?
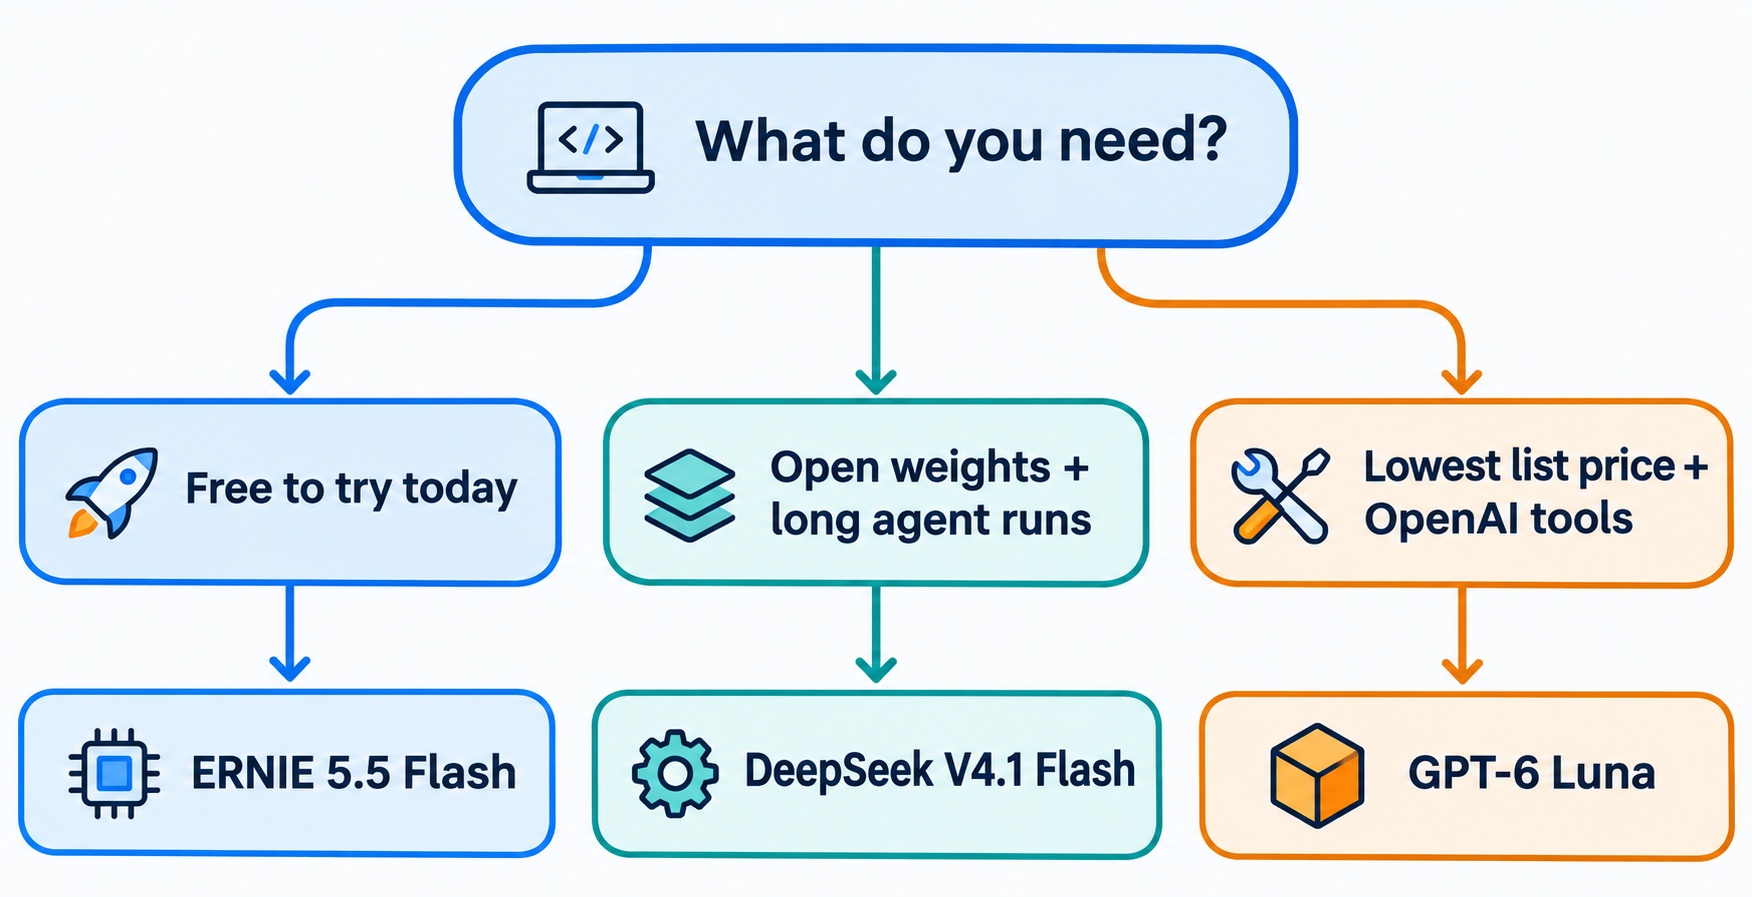
Pick by constraint, not by leaderboard:
- You want to try a new model at $0 today: ERNIE 5.5 Flash Preview on OpenRouter. Expect preview behavior and rate limits.
- You need open weights or plan to self-host: DeepSeek V4.1 Flash.
- Your agent runs long, input-heavy sessions and you can schedule off-peak: DeepSeek V4.1 Flash, where off-peak cache hits cost $0.003 per 1M.
- You want the lowest paid list price and OpenAI’s hosted tools: GPT-6 Luna.
- You need image input: DeepSeek V4.1 Flash or GPT-6 Luna, not ERNIE.
Let your coding agent compare all three with Apidog CLI
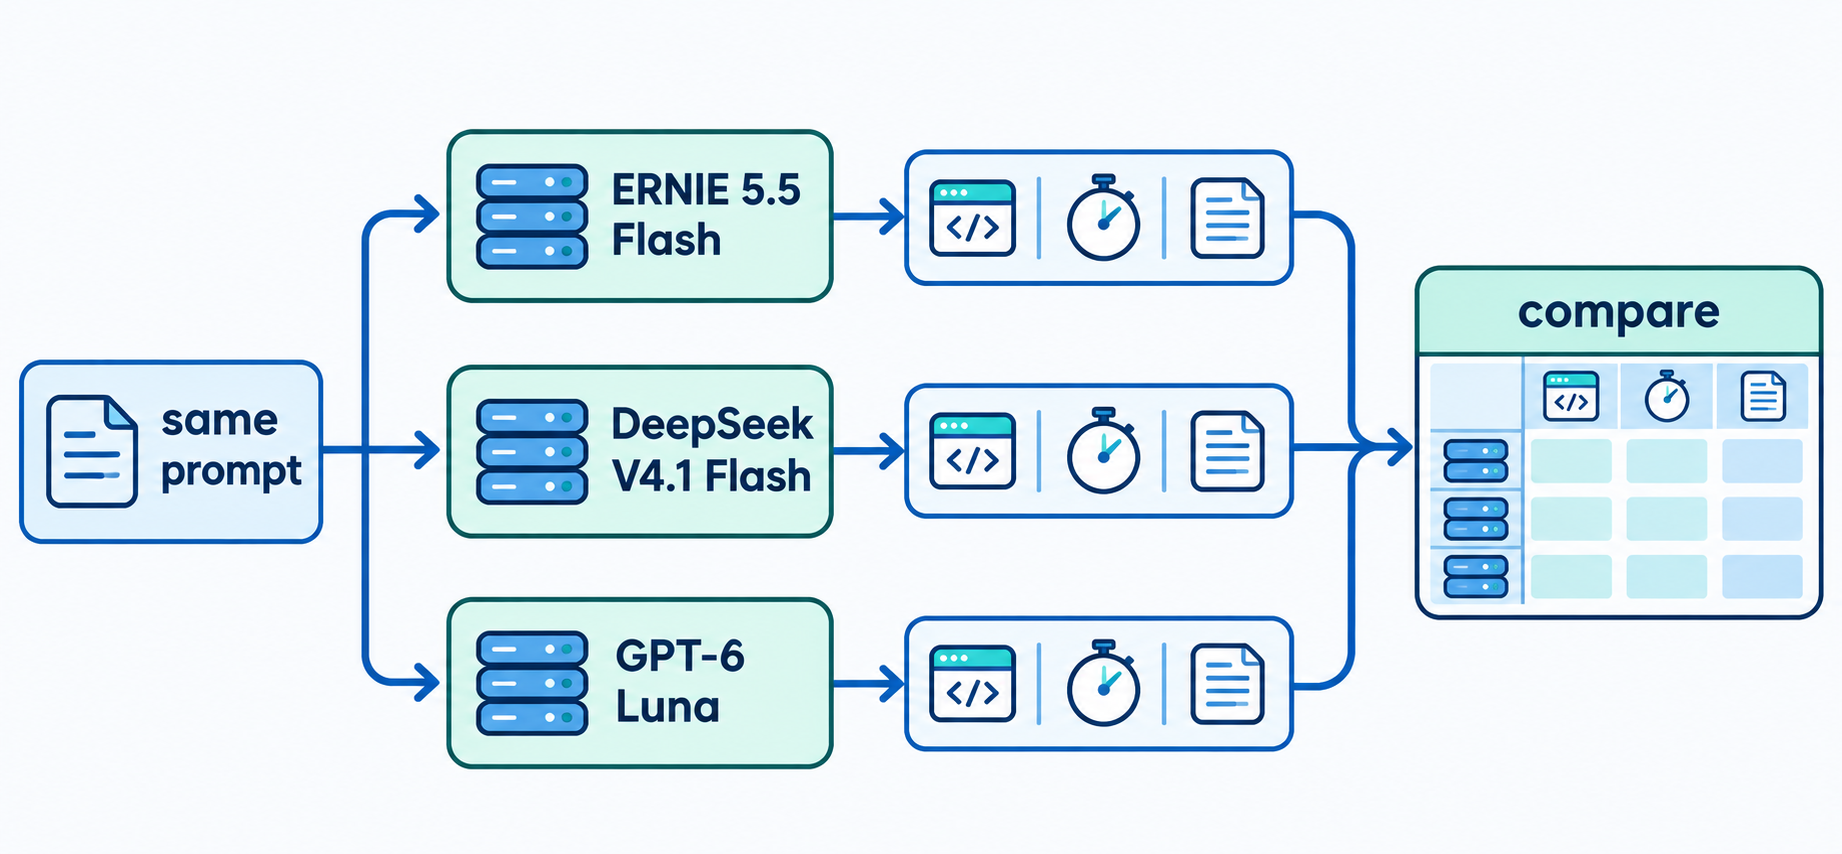
Don’t hand-click three API calls every time a model updates. Let Claude Code, Codex or Cursor build one scenario and run it against each provider with Apidog CLI. All three speak OpenAI Chat Completions, so only the base URL, model ID and key change.
Set up the CLI once:
npm install -g apidog-cli@latest
apidog auth login --with-token <YOUR_TOKEN>
apidog skill install
Then give your agent one prompt:
In Apidog project <projectId>, create three environments: ernie-flash
(base URL https://openrouter.ai/api/v1, model baidu/ernie-5.5-flash-preview:free),
deepseek-flash (https://api.deepseek.com, model deepseek-flash) and gpt-6-luna
(https://api.openai.com/v1, model gpt-6-luna). Create one test scenario that POSTs
the same prompt to {{baseUrl}}/chat/completions with model {{model}}, asserts
status 200 and a non-empty choices[0].message.content, and records
usage.completion_tokens. Run it 5 times per environment and give me a table of
pass rate, average response time and output tokens.
The agent creates the environments, checks the scenario payload against the schema, writes it and runs it:
apidog environment create ernie-flash --project <projectId> --base-url https://openrouter.ai/api/v1 --variables '<json>'
apidog environment create deepseek-flash --project <projectId> --base-url https://api.deepseek.com --variables '<json>'
apidog environment create gpt-6-luna --project <projectId> --base-url https://api.openai.com/v1 --variables '<json>'
apidog cli-schema get test-scenario-create
apidog cli-schema validate test-scenario-create --file scenario.json
apidog test-scenario create --project <projectId> --file scenario.json
apidog test-scenario run <scenarioId> --project <projectId> -e <envId> -n 5 -r cli,json --env-var "apiKey=$OPENROUTER_API_KEY"
Passing keys with --env-var keeps them out of the shared environment. Repeat the run per environment with that provider’s key; the JSON reports feed your table. The same run command with -r junit drops into CI; see the Apidog CLI CI/CD guide and the Claude Code setup walkthrough. Apidog’s Free plan covers up to 4 users, so a small team can run this without a paid seat.
FAQ
Is ERNIE 5.5 Flash cheaper than DeepSeek V4.1 Flash? Right now, yes: the OpenRouter :free endpoint costs $0 within its rate limits. Baidu hasn’t published a paid price we could verify, so a paid-to-paid comparison isn’t possible yet.
Which has the biggest context window? They’re close. GPT-6 Luna lists 1,050,000 tokens, ERNIE 5.5 Flash Preview 1,024,000 on OpenRouter, and DeepSeek V4.1 Flash 1M. Luna’s price doubles on input past 272K tokens.
Can I run any of these models locally? DeepSeek V4.1 Flash, yes: MIT weights on Hugging Face. ERNIE 5.5 Flash Base weights are public, but the Preview chat model isn’t released yet. GPT-6 Luna has no public weights.
Which is best for coding agents? It depends on your harness. DeepSeek V4.1 Flash reports strong agentic scores in its own tests and supports OpenAI and Anthropic formats. GPT-6 Luna has the widest hosted tool set. ERNIE 5.5 Flash Preview is free to try but text-only and still in preview.
Does GPT-6 Luna have a free API tier? No. OpenAI’s model page lists the Free tier as “Not supported.” Paid usage starts at $0.10 per 1M input tokens.