Claude Fable 5.1 replaced Fable 5 on September 1, 2026, at the same $10 and $50 per million tokens, with cache reads cut from $1 to $0.25 per million and better numbers on every benchmark Anthropic published. Fable 5 is still served, and Anthropic’s Fable 5 model page commits to it until at least June 9, 2027. So the question is not whether Fable 5.1 is better on paper. It is whether the upgrade earns its migration cost for your workload, and whether any of the three breaking changes bite you.
This comparison goes through what is identical, what improved, what got more expensive or harder, and a decision rule by workload. The sources are Anthropic’s launch post and What’s new in Claude Fable 5.1. For the full spec sheet, see what Claude Fable 5.1 is.
Side by side
| Claude Fable 5.1 | Claude Fable 5 | |
|---|---|---|
| Model ID | claude-fable-5-1 |
claude-fable-5 |
| Released | September 1, 2026 | June 9, 2026 (suspended June 12, back July 1) |
| Retirement | Not sooner than September 1, 2027 | Not sooner than June 9, 2027 |
| Context / max output | 1M / 128K | 1M / 128K |
| Knowledge cutoff | June 2026 | January 2026 |
| Input / output price | $10 / $50 | $10 / $50 |
| Cache read | $0.25 per million | $1.00 per million |
| Cache writes | $12.50 (5m), $20 (1h) | Same |
| Batch | $5 / $25 | Same |
| Tokenizer | Same (Opus 4.7 generation) | Same |
| Thinking | Adaptive, always on | Adaptive, always on |
Forced tool_choice |
400 | Accepted |
| Thinking blocks readable by older models | No | Yes |
| History-editing check | Yes (enforced for accounts created on or after 2026-08-31) | No |
| Priority Tier | Not supported | Supported |
| Per-message effort | Yes (beta) | No |
| Turn-scoped system messages | Yes (beta) | No |
thinking.display: "updates" |
Yes (beta) | Yes (beta) |
| Content provenance | Text watermark + C2PA on media | Text watermark |
| Data retention | 30-day required, Covered Model | Same |
| Refusal categories | Same five | Same five |
What is identical
More than you might expect. The API surface, the 1M context window, the 128K output cap, the per-token prices, the tokenizer, the 512-token cache minimum, always-on adaptive thinking, the "omitted" default for thinking.display, the prefill ban, the sampling-parameter ban, mid-conversation system messages, and the full set of refusal categories and fallback mechanics all carry over unchanged. Anthropic says existing Fable 5 prompts should perform well on Fable 5.1 without changes.
That means most of what we wrote about Fable 5 still applies: the rate limits guide (the two models even share one rate-limit pool), the safeguards explainer, and the cloud availability guide.
What improved
The benchmarks, on Anthropic’s numbers. Every published row moved in Fable 5.1’s favor. The gaps are not uniform, though.
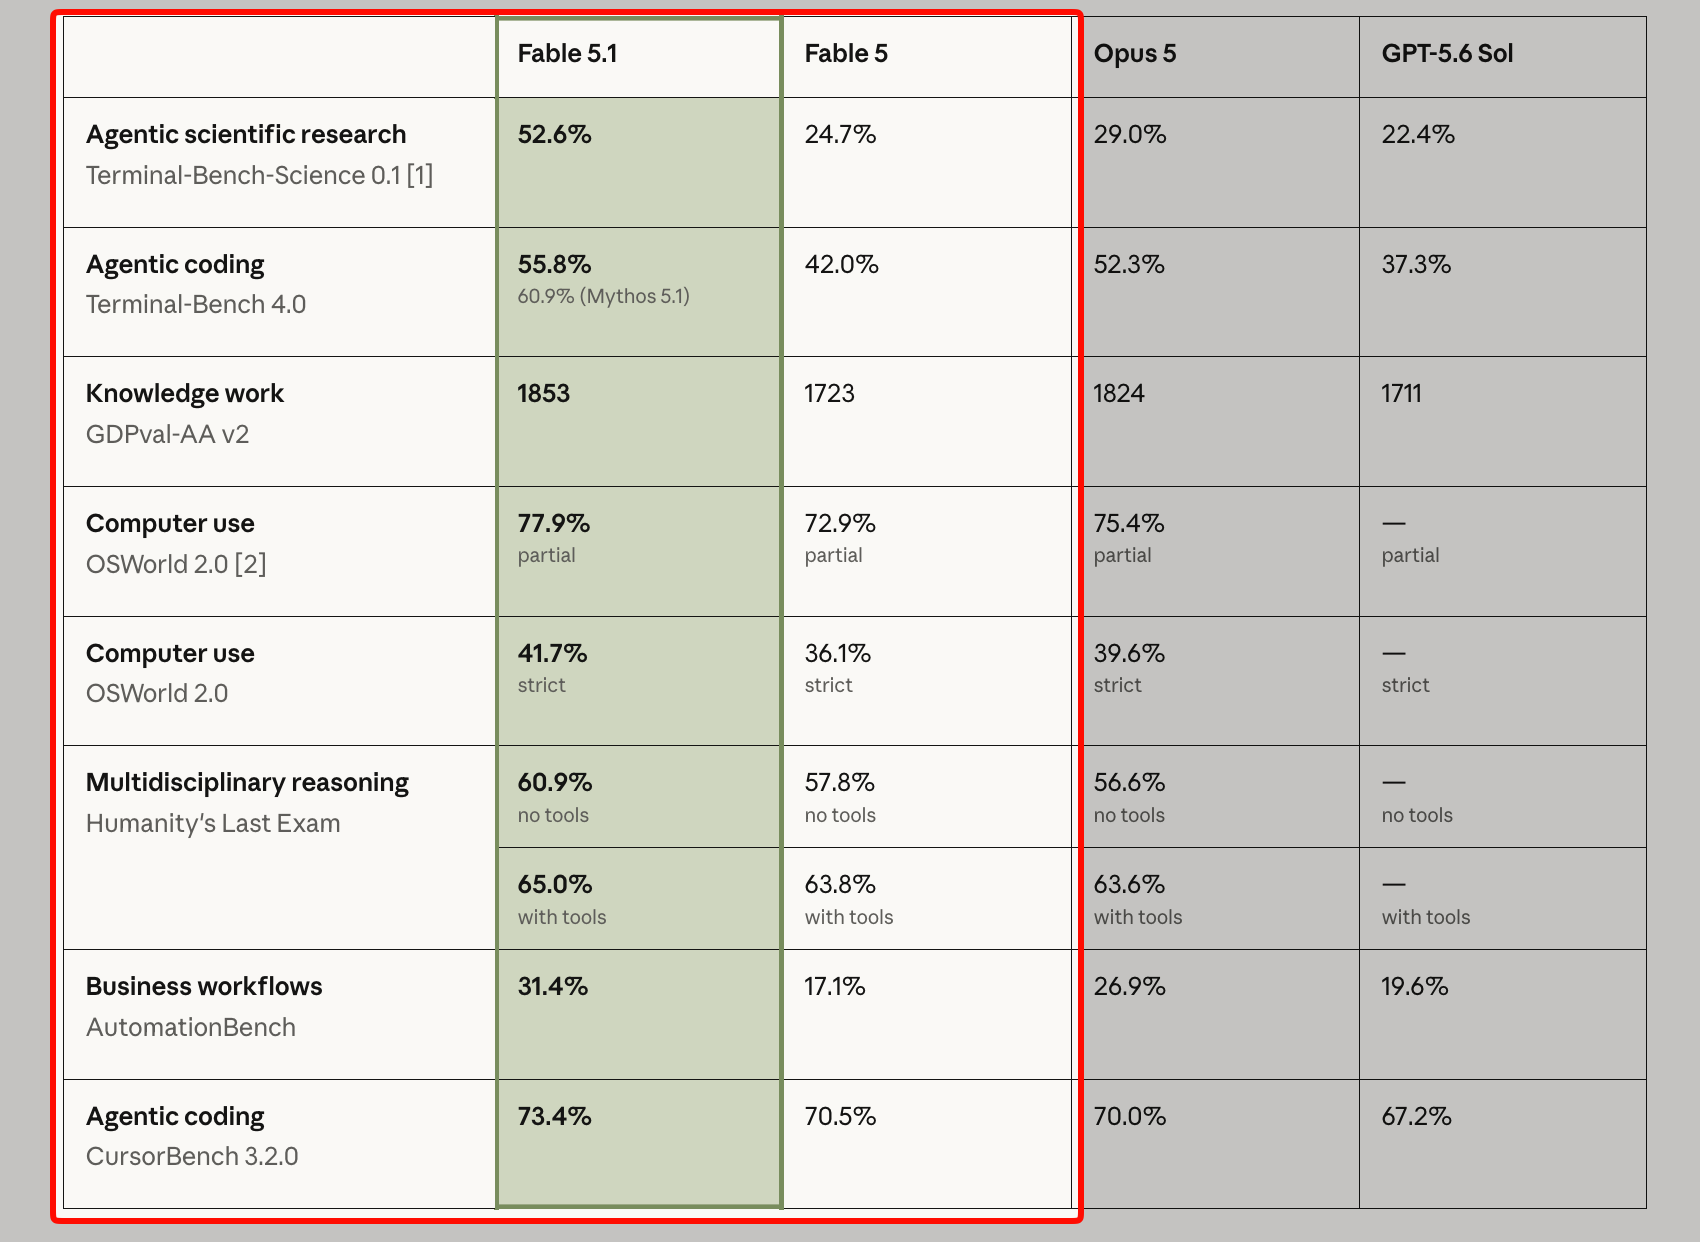
| Benchmark | Fable 5.1 | Fable 5 | Delta |
|---|---|---|---|
| Terminal-Bench-Science 0.1 | 52.6% | 24.7% | +27.9 |
| AutomationBench | 31.4% | 17.1% | +14.3 |
| Terminal-Bench 4.0 | 55.8% | 42.0% | +13.8 |
| GDPval-AA v2 | 1853 | 1723 | +130 Elo |
| OSWorld 2.0 (strict) | 41.7% | 36.1% | +5.6 |
| OSWorld 2.0 (partial) | 77.9% | 72.9% | +5.0 |
| Humanity’s Last Exam (no tools) | 60.9% | 57.8% | +3.1 |
| CursorBench 3.2.0 | 73.4% | 70.5% | +2.9 |
| Humanity’s Last Exam (with tools) | 65.0% | 63.8% | +1.2 |
The pattern: the biggest jumps are on long-horizon agentic benchmarks (scientific research in a terminal, business workflow automation, agentic coding). The smallest are on knowledge and IDE-style coding tasks. If your workload looks like the top of that table, the upgrade is large. If it looks like the bottom, it is a few points. All of these are vendor-run with no independent reproduction yet; the benchmarks breakdown goes row by row.
Cache reads at a quarter of the price. Per the pricing page, this is the change most Fable 5 users will feel first. A long agentic session that re-reads a 150,000-token prefix every turn paid $0.15 per turn in cache reads on Fable 5 and pays $0.0375 on Fable 5.1. Anthropic’s estimate is 25% cheaper on typical workloads and up to 45% on agentic ones. The pricing breakdown reproduces that math with three worked examples.
Fewer false positives from the safeguards. Fable 5’s classifiers were the most common complaint after it came back in July. Anthropic reports the biology classifiers fire 85% less often on benign elementary biology and medical requests than Fable 5’s did at launch, and the cyber safeguards cause around 60% fewer interventions per Claude Code session. Fable 5.1 can also identify vulnerabilities in source code, which Fable 5 declined. Exploit development is still refused.
Effort headroom. Anthropic says medium on Fable 5.1 roughly matches Fable 5 at lower cost, and the gains over Fable 5 are largest at xhigh and max. Practically, a Fable 5 workload running at high can often move to Fable 5.1 at medium for the same quality and fewer output tokens, or stay at high for a quality gain.
Knowledge cutoff. June 2026 versus January 2026. Five extra months of framework releases, API changes, and model launches the model knows without being told.
Three harness features. Per-message effort changes without a cache reset, turn-scoped system messages for per-turn reminders, and readable progress updates between tool calls. Fable 5 has the last one; the first two are new.
What got harder
Forced tool use is gone. tool_choice any and tool return a 400 on Fable 5.1. If you used them to guarantee JSON, move to strict: true under auto or to structured outputs. If you used them because the application requires a call on a given turn, append a mid-conversation system message that says so. Not hard, but it is a code change on every forced-tool call site.
Thinking blocks are one-way. Fable 5.1 reads Fable 5’s thinking blocks, so a conversation moving up keeps its reasoning. Fable 5 cannot read Fable 5.1’s. During a gradual cutover where a router might send a conversation back down, the API drops the blocks, unbilled, and Fable 5 re-plans that turn.
The history-editing check. Fable 5.1 thinking blocks are valid only in the exact conversation that produced them. Edit an earlier turn, rebuild the system prompt, or swap the tools array, and the next request that replays the block fails on accounts created on or after August 31, 2026. Fable 5 never checked. If your harness injects and deletes per-turn reminders, refreshes the date in the system prompt, or compacts on the client while keeping recent turns verbatim, budget real time here. The preserved thinking guide covers the audit and the fixes, and the migration guide has the full checklist.
Priority Tier. Fable 5 supports it; Fable 5.1 does not. For enterprise capacity guarantees, that is a reason to stay on Fable 5 until Anthropic adds it.
Agent-loop behavior. Three prompt-tunable shifts: Fable 5.1 may issue one tool call per turn where Fable 5 batched several, it writes fewer progress updates, and at low effort it answers from memory more often instead of searching. Each has a one-line fix in the prompting guide, but each is also a change you have to notice.
Decision rule by workload
Upgrade now if your work is long-running agentic coding, multistep research, or document and spreadsheet generation. That is where the benchmark gains concentrate, where the cache-read price lands hardest, and where the safeguard false-positive drop matters most. Cognition said it was moving its Devin traffic to Fable 5.1 on launch day, which is the clearest public signal of that logic.
Upgrade after the harness audit if your code builds the messages array itself and does anything beyond appending turns. Run the three-step history-editing check first, fix every prefix_binding_mismatch, then switch. The check is cheap; discovering it in production is not.
Upgrade at medium if Fable 5 at high was doing routine work well and you want the same quality for less. Re-run the effort sweep on your evals rather than assuming the levels map across.
Stay on Fable 5 if Priority Tier is load-bearing, or if your workload is output-heavy with little cached prefix (where the price change barely registers and the migration cost is pure overhead). Fable 5 is committed through at least June 9, 2027, so there is no clock on this yet.
Consider Opus 5 instead if the honest answer is that Fable 5 was already more model than you needed. Anthropic’s own guidance is to start with Opus 5 and move up only when it falls short. The Fable 5.1 vs Opus 5 comparison works through that at half the price.
Testing both models against each other in Apidog
The cleanest way to settle this for your own workload is a side-by-side collection. In Apidog, save your ten hardest production prompts as requests with model as an environment variable, run the collection once against claude-fable-5 and once against claude-fable-5-1 at the same effort, and compare three fields per request: the text, usage.output_tokens, and usage.cache_read_input_tokens on the second run. Add one more request that uses a forced tool_choice, so you see the 400 before your users do. Download Apidog to set it up; the API walkthrough has the request bodies.
FAQ
Is Claude Fable 5.1 a new model or an update to Fable 5? A new model with its own ID, claude-fable-5-1, and its own retirement date. It uses the same tokenizer and per-token pricing as Fable 5 and is trained on data through June 2026.
Does Fable 5.1 cost more than Fable 5? No. Same $10 and $50 per million tokens, same cache writes, same batch rates. Cache reads are cheaper: $0.25 per million versus $1.
Will my Fable 5 code work on Fable 5.1? Most of it. Forced tool_choice returns a 400, and code that edits conversation history between requests will invalidate thinking blocks on accounts created on or after August 31, 2026. Everything else carries over.
Is Fable 5 being retired? Not yet. Anthropic’s commitment is that Fable 5 will not be retired before June 9, 2027, on Anthropic-operated platforms. Bedrock and Google Cloud set their own dates.
Which is better at coding, Fable 5.1 or Fable 5? On Anthropic’s numbers, Fable 5.1: 55.8% vs 42.0% on Terminal-Bench 4.0 and 73.4% vs 70.5% on CursorBench 3.2.0. The agentic-terminal gap is large; the IDE-style gap is small. Both are vendor-run results.
Does Fable 5.1 refuse less than Fable 5? Anthropic reports 85% fewer biology false positives and around 60% fewer cyber interventions per Claude Code session. The categories are the same, so keep your refusal handling and fallbacks in place.