Your API returns 400 Bad Request with the body {"error": "invalid input"}. A human developer opens the docs, checks the payload, spots the missing field, and fixes it in a minute. An agent reads the same two words, has nothing to act on, and does the only thing it can: sends the same request again. Then again. Then it gives up and tells the user the API is broken.
Error responses are the part of an API that agents depend on most and that teams design last. A good error tells the caller what went wrong, whether retrying could help, and what to change. An agent can act on all three. A vague error turns a recoverable problem into a failed task.
This guide is written for the API side of the relationship. Our post on agent error recovery covers what the client should do with retries, backoff, and circuit breakers. This one covers what your API has to return for that client logic to work at all.
Apidog matters here because error responses are the least-tested part of most APIs. You can define them in the spec, mock them, and assert on them in the same place you test the happy path.
The three questions an error must answer
Every error response an agent receives should let it answer three things without guessing.
Is this my fault or yours? A 4xx means the request was wrong and repeating it unchanged will fail again. A 5xx means something on the server went wrong and the same request might succeed later. Agents that cannot tell these apart either retry forever on a validation error or give up on a transient blip.
Should I retry, and when? Some 4xx errors are retryable and some are not. 429 is retryable after a wait. 409 may be retryable after re-reading state. 422 is not retryable without changing the payload. Say which, explicitly.
What exactly do I change? This is the field most APIs omit. “Validation failed” is useless. “The field customer.postal_code is required when country is US” is a fix the agent can apply on the next attempt.
Get those three into every error and most agent retry storms disappear.
Use a structured error format
Do not invent a shape. RFC 9457, Problem Details for HTTP APIs, defines one and it is well supported:
{
  "type": "https://api.example.com/errors/validation-failed",
  "title": "Validation failed",
  "status": 422,
  "detail": "The field 'customer.postal_code' is required when 'country' is 'US'.",
  "instance": "/v1/orders",
  "errors": [
    {
      "field": "customer.postal_code",
      "code": "required_conditional",
      "message": "Required when country is US. Provide a 5-digit or 9-digit US postal code.",
      "example": "94107"
    }
  ],
  "retryable": false,
  "next_action": "Add customer.postal_code to the request body and send again."
}
Four parts carry the weight for an agent.
detail is a full sentence naming the actual field and the actual rule. Not a category. The specific thing that failed on this request.
The errors array is machine-readable, one entry per problem, with a field path an agent can map back onto the payload it sent. Return every failure at once. Returning them one at a time turns a single fix into five round trips.
retryable is a boolean, not something to infer from a status code. This is the extension that helps agents most, and it costs one field.
next_action is plain instruction text. Models follow explicit instructions in a response body more reliably than they reason from error codes, and one sentence here often turns a failed task into a completed one.
Google’s API error design guide reaches similar conclusions from a different direction, notably that error details belong in a structured list rather than in prose.
Say when to come back
For anything transient, say when. An agent that knows to wait 30 seconds waits 30 seconds. An agent that does not know will pick something, and the something is usually too short.
HTTP/1.1 429 Too Many Requests
Retry-After: 30
Content-Type: application/problem+json

{
  "type": "https://api.example.com/errors/rate-limited",
  "title": "Rate limit exceeded",
  "status": 429,
  "detail": "You have used 1000 of 1000 requests in the current minute window.",
  "retryable": true,
  "retry_after_seconds": 30,
  "next_action": "Wait 30 seconds before sending this request again. Do not retry sooner."
}
The Retry-After header accepts either a delay in seconds or an HTTP date; seconds is the easier one for a client to act on. Send it as a header for standard clients and repeat it in the body for the model. Duplication is cheap and both consumers get what they read best. The rate-limit specifics are covered in our rate limit exceeded guide and in how to implement API rate limiting if you are on the server side of it.
The same pattern applies to 503 during maintenance and to 409 on a locked resource. Any error where waiting is the correct response should carry a number.
Never leak internals, never return nothing
Two failure modes sit at opposite extremes, and both hurt agents.
The first is the stack trace. Returning internal exception text exposes framework versions, file paths, and sometimes query fragments. It is a security problem before it is an agent problem, and the concerns in our post on testing APIs against untrusted input apply directly. It also floods the context window with text the model cannot act on.
The second is the empty error: a 500 with no body, or {"error": true}. The agent learns nothing, and its only options are retry or quit.
The middle path is a stable public error with a correlation ID:
{
  "type": "https://api.example.com/errors/internal",
  "title": "Internal error",
  "status": 500,
  "detail": "The order could not be created due to an internal error. No order was created.",
  "retryable": true,
  "retry_after_seconds": 5,
  "request_id": "req_01J8ZK3M2Q",
  "next_action": "Retry once after 5 seconds. If it fails again, stop and report request_id req_01J8ZK3M2Q."
}
The sentence “No order was created” is the most valuable part. Agents facing an ambiguous write have to decide whether retrying risks a duplicate, and most decide badly. Tell them what state you are in. Where you cannot promise that, make the operation idempotent and say so, which is the pattern in our post on idempotency keys for AI agents.
The request_id gives you the thread back to your logs when a human eventually reads the transcript. Pair it with the practices in our API observability guide so the ID actually resolves to something.
Errors belong in the spec
If an error shape is not in your OpenAPI document, it does not exist as far as generated clients, mocks, and agent tools are concerned. Most specs describe a 200 in detail and then wave at everything else.
responses:
  '201':
    description: Order created
    content:
      application/json:
        schema: { $ref: '#/components/schemas/Order' }
  '422':
    description: >
      Validation failed. Not retryable without changing the request body.
      The errors array names each invalid field.
    content:
      application/problem+json:
        schema: { $ref: '#/components/schemas/Problem' }
  '429':
    description: >
      Rate limited. Retryable. Wait for retry_after_seconds before sending again.
    content:
      application/problem+json:
        schema: { $ref: '#/components/schemas/Problem' }
Those descriptions are not decoration. When you generate agent tools from the spec, as in our guide to turning an OpenAPI spec into agent tools, that text becomes what the model reads about the failure case. A description that says “retryable, wait first” produces better behavior than one that says “Too Many Requests”.
Test the errors, not just the successes
Error paths are where testing coverage collapses, because triggering them takes effort. Mocking removes the effort.
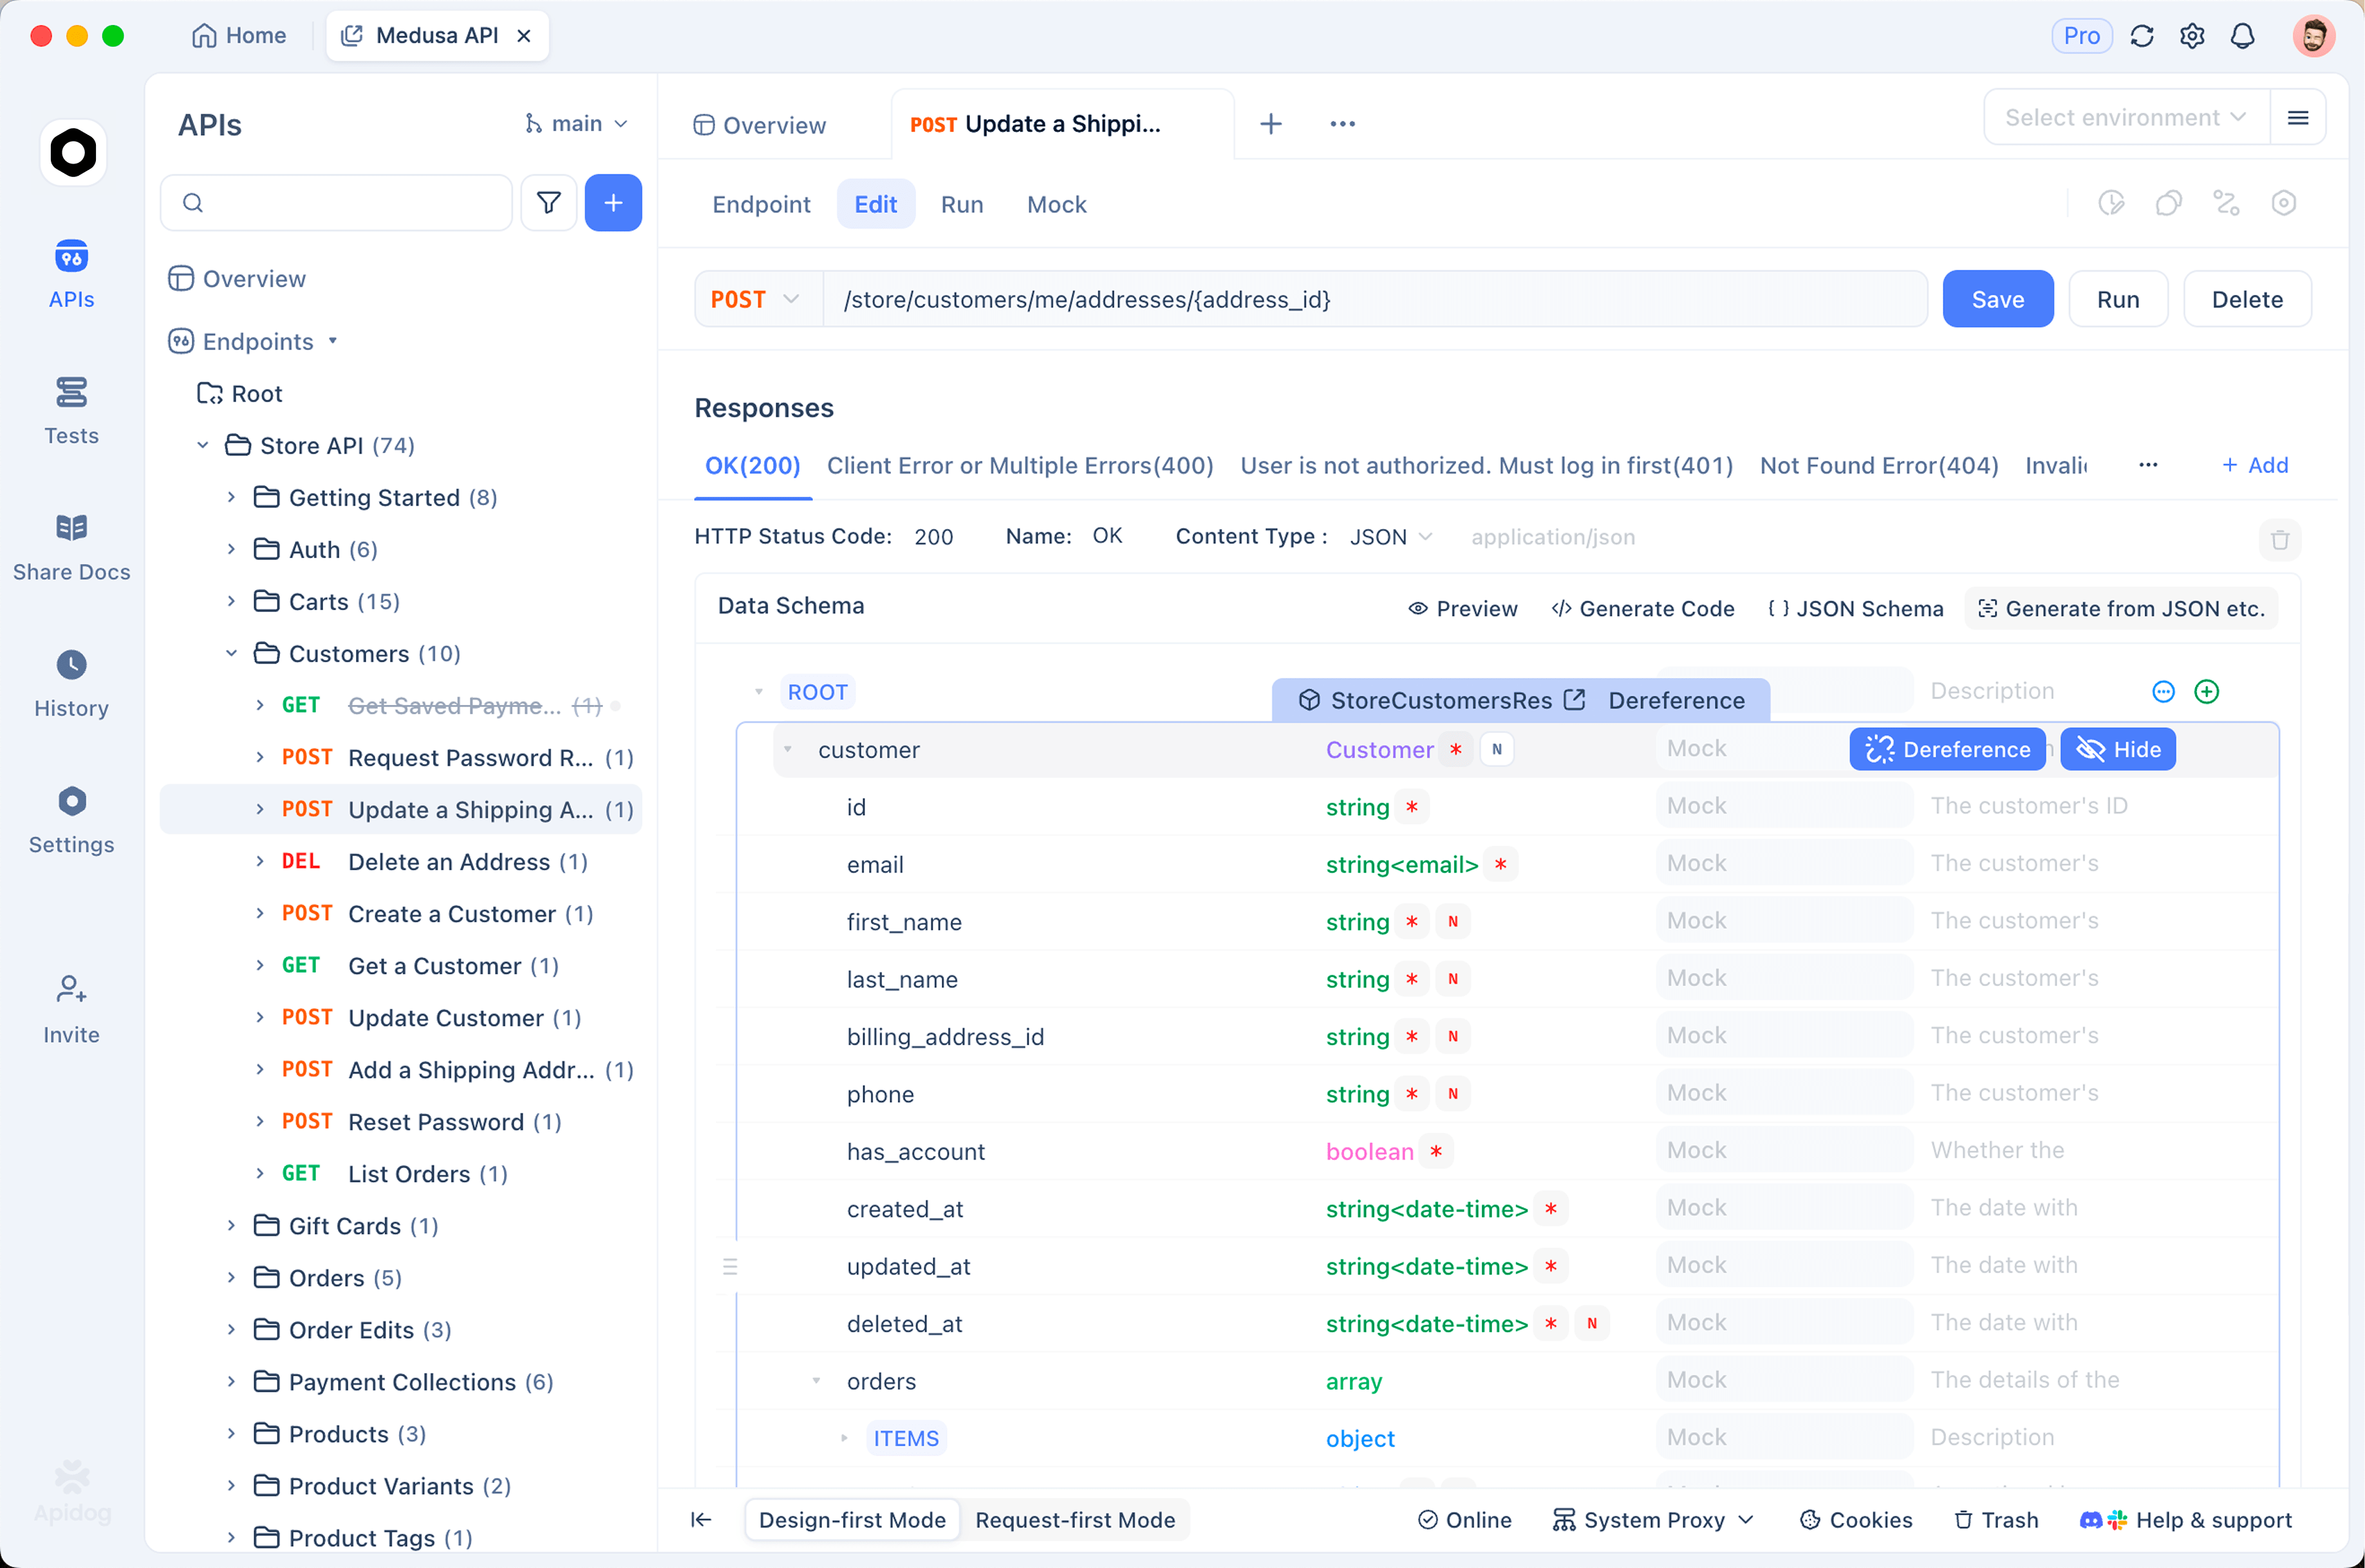
Define each error response in your API project, then mock them so the agent can meet every case on demand. In Apidog you can add the failure responses to the endpoint definition and switch a mock between them, which gives you a repeatable way to run the agent against a 422, a 429, and a 500 without breaking anything real. Our post on running agents against mocks instead of production covers the wider habit.
Five cases to build:
- Validation failure with several bad fields at once. Assert every problem comes back in one response, and that the agent’s next attempt fixes all of them rather than one.
- Rate limit with a wait. Assert the agent waits at least
retry_after_secondsinstead of hammering. - Server error on a write. Assert the agent does not silently create a duplicate when it retries.
- Auth failure. Assert the agent stops rather than retrying, since no amount of waiting fixes a bad token. Our post on least-privilege API keys for agents covers the credentials side.
- Malformed error body. Return something that is not valid JSON and confirm the agent degrades gracefully. Upstream proxies do this to you eventually.
Save the set as scenarios so they run in CI. Error handling regresses quietly, usually when someone refactors a serializer, and the happy-path suite will not notice.
What better errors are worth
The value shows up in three places, and it is easy to measure once you look.
Fewer wasted retries. An agent facing {"error": "invalid input"} typically retries the identical payload two or three times before quitting. Each attempt costs a model turn and the full conversation as context. A response naming the missing field usually produces one corrected attempt. That is the difference between four calls and two on a routine validation slip.
Fewer escalations. Agents that cannot recover hand the task to a human. Every avoidable handoff is the expensive outcome the agent was supposed to prevent. Errors that name a fix keep the run inside the automation.
Shorter debugging. When something does need a person, request_id plus a precise detail turns a hunt through logs into a single lookup. This is the same argument our API observability guide makes about correlation, applied to the moment a run breaks.
There is a fourth benefit that is easy to miss: the same improvements help human developers. Nobody has ever complained that an error message was too specific about which field was wrong.
Design for the escalation too
Some errors are genuinely not recoverable by the agent. A missing scope, a closed account, a rule that needs a human decision. For those, the job of the error is to hand off cleanly: say what happened, say what a person needs to do, and carry the correlation ID that makes the handoff cheap.
That reply has to land somewhere a human reads. If the agent is a coding runtime working through assigned tasks, the surrounding platform is usually where it lands. Sharkly keeps the agent’s result and execution trace on the Task and routes items needing a reply or review into an Inbox, so a blocked run is visible as work rather than as a line in a log. Your error text is what makes that handoff useful, because a message reading “invalid input” gives the reviewer no more than it gave the agent.
Do not make the agent parse prose
One last anti-pattern, common in APIs that grew organically. The status code is right, the body is a sentence, and every distinct failure gets different wording:
{ "message": "Sorry, that didn't work. Please check your details and try again." }
An agent can only respond to this by guessing. Worse, teams often pair it with a 200 status, so the client library does not even see a failure.
Two rules fix it. Give every distinct failure a stable machine-readable code, so the agent can branch on insufficient_funds rather than on the phrase “not enough”. And never return a failure with a success status code, whatever the client-side convenience argument. A 200 with an error inside is invisible to every retry policy, every dashboard, and every alert you own.
A checklist for agent-readable errors
- Every error uses one consistent structured format across the whole API.
detailnames the specific field or condition, never a category.- Validation errors return every problem at once, with field paths.
- A
retryableboolean appears on every error. - Retryable errors carry a wait in seconds, in the header and the body.
- Write failures state whether anything was created or changed.
- Every error carries a correlation ID that resolves in your logs.
- No stack traces, no framework strings, no SQL.
- Error responses are documented in the spec with agent-legible descriptions.
- Mocks exist for each error, and saved tests run them in CI.
Errors are an interface. Design them for the caller you actually have, which increasingly is a model that will do exactly what your response body tells it to do. Download Apidog to define the error shapes and mock them before the agent meets them for real.
Frequently asked questions
Should I use RFC 9457 or my own error format? Use RFC 9457 unless you already have a consistent format in production. Consistency beats standardization: switching half your endpoints to a new shape is worse than keeping one shape everywhere. Add the retryable and next_action extensions to whichever you use.
Is next_action text safe to put in an API response? Yes, when your service generates it from a fixed set of templates. Never echo user-supplied content into that field, since an agent reads it as instruction and that is a prompt-injection path. Our post on testing APIs against untrusted input covers the risk.
Should validation errors be 400 or 422? Use 400 when the request is malformed, such as broken JSON, and 422 when the request parses but fails business rules. Agents benefit from the split because the fixes are different. If you already use one for both, document it rather than changing it.
How much detail is too much? Stop at the point where the caller has enough to act. Field name, rule, and an example value is usually enough. Internal identifiers, query text, and stack frames are past the line.
Do error messages count against the context window? Yes, and a verbose error repeated across retries adds up quickly. Keep them under a few hundred tokens. Our post on trimming API responses for agents applies to failures as much as to successes.
How do I stop an agent retrying a non-retryable error? Set retryable: false, say so in next_action, and enforce it in the tool wrapper so the model’s judgment is not the only guard. Belt and braces is correct here.